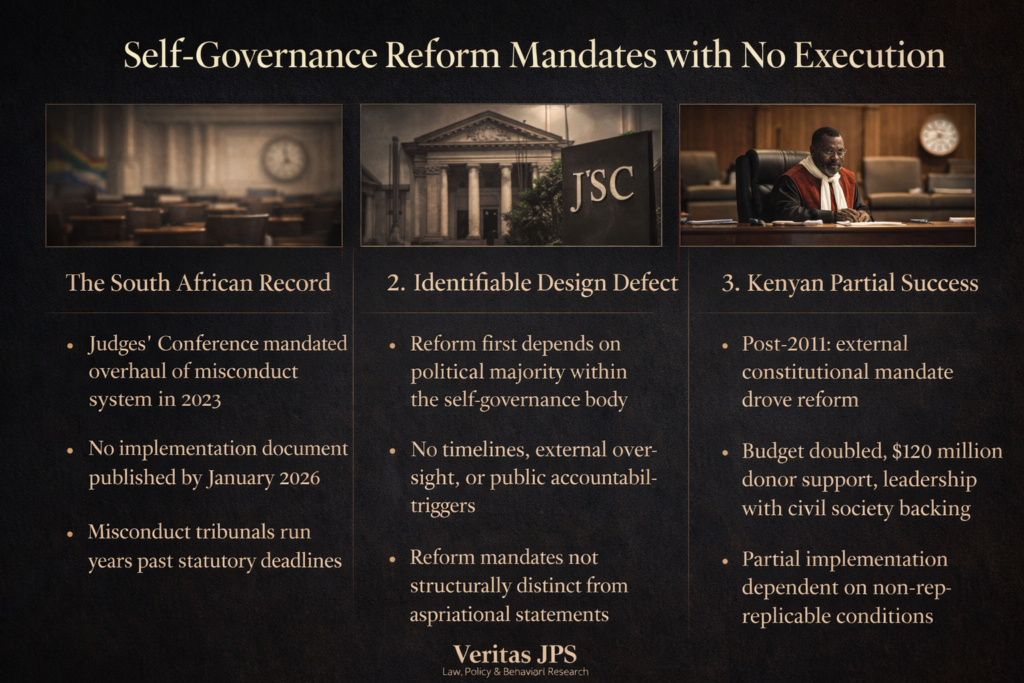
Tag: structural-failure

  • Moral Disengagement and Institutional Ethics: Why Integrity Systems Fail Cognitively

    Moral Disengagement and Institutional Ethics: Why Integrity Systems Fail Cognitively

    Quick Answer: Moral disengagement explains why institutional actors can know ethical rules yet rationalise violations at the moment of conduct. Current integrity systems focus on codes, training, committees, and sanctions, but rarely target the cognitive mechanisms that suspend self-regulation. That design gap leaves judicial and institutional ethics systems structurally exposed.

    Abstract

    Institutional ethics systems — codes of conduct, integrity committees, compliance training, sanctions regimes — address rule knowledge, attitudinal alignment, and deterrence. They do not address the cognitive mechanism through which institutional actors with full knowledge of ethical rules selectively suspend their own self-regulatory standards at the moment of conduct. That mechanism — moral disengagement, formalised by Bandura through eight distinct cognitive processes — is documented as an independent predictor of unethical behaviour in public-sector and organisational settings. This analysis examines the evidence base across peer-reviewed research (Pires et al., 2025; Fida et al., 2025; Hameduddin et al., 2024), institutional compliance assessments (Nigeria ICPC, 2024), and authoritative training frameworks (UNODC, Bangalore Principles) to assess whether current judicial and institutional integrity systems engage the disengagement architecture at the intervention design level. They do not. Intervention redesign targeting specific disengagement mechanisms is both theoretically grounded and empirically overdue.

    Why Do Ethics Violations Persist Among Actors Who Know the Rules?

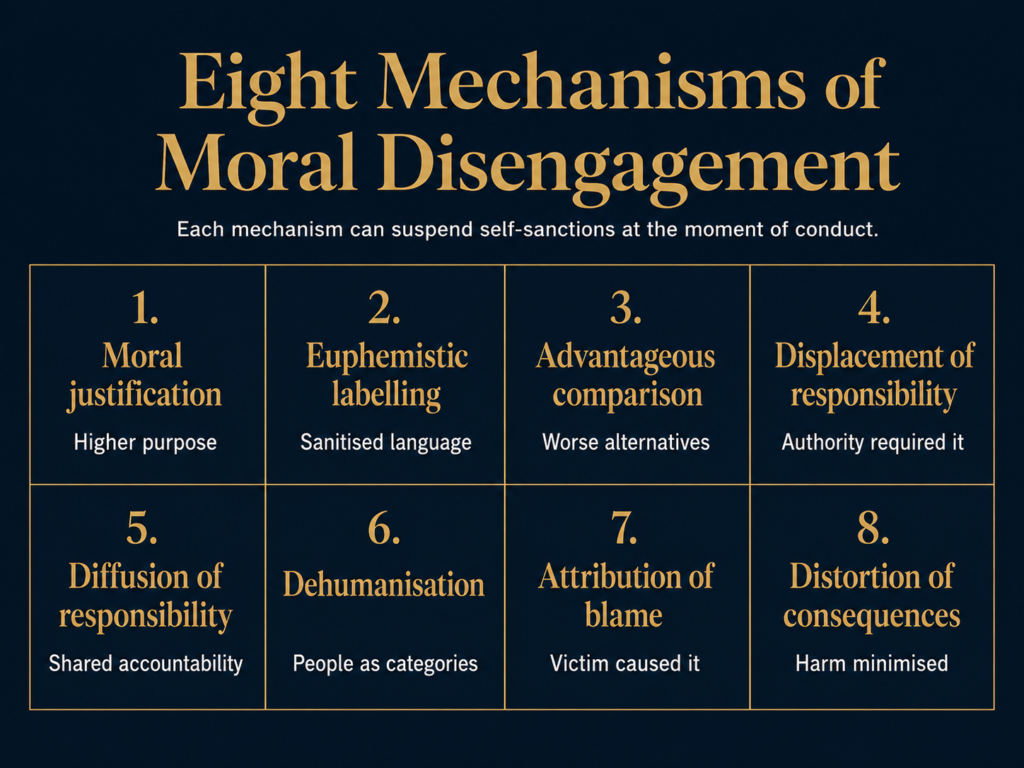
    The conventional institutional response to ethics failures follows a recognisable sequence: strengthen the code, increase training hours, raise sanctions. Each measure assumes a specific failure point. Stronger codes assume ambiguity in the rule. More training assumes a deficit in knowledge. Higher sanctions assume deterrence is insufficient.

    None of these assumptions addresses the documented cognitive process through which an institutional actor — a judge, a regulator, a senior public servant — holds full knowledge of the applicable ethical standard, believes themselves to be an ethical person, and selectively disengages their own moral self-sanctions at the moment the rule would otherwise constrain their conduct.

    The Nigeria ICPC Ethics and Integrity Compliance Scorecard assessed 330 federal Ministries, Departments and Agencies against a procedural checklist covering ethics unit establishment, code of conduct deployment, training delivery, integrity committee operation, and anti-corruption policy compliance. Zero of 330 MDAs achieved full compliance. Fifteen agencies — including the Supreme Court of Nigeria — scored in the failure band. The codes existed. The training infrastructure was constituted. The compliance result was zero.

    This outcome is not anomalous within the moral disengagement literature. It is precisely what the framework predicts when institutional integrity design targets the knowledge and deterrence tiers while leaving the cognitive rationalisation tier unaddressed.
    Mechanism-countermeasure matrix linking moral disengagement routes to institutional design responses

    Bandura’s Framework: Eight Mechanisms of Moral Self-Sanction Deactivation

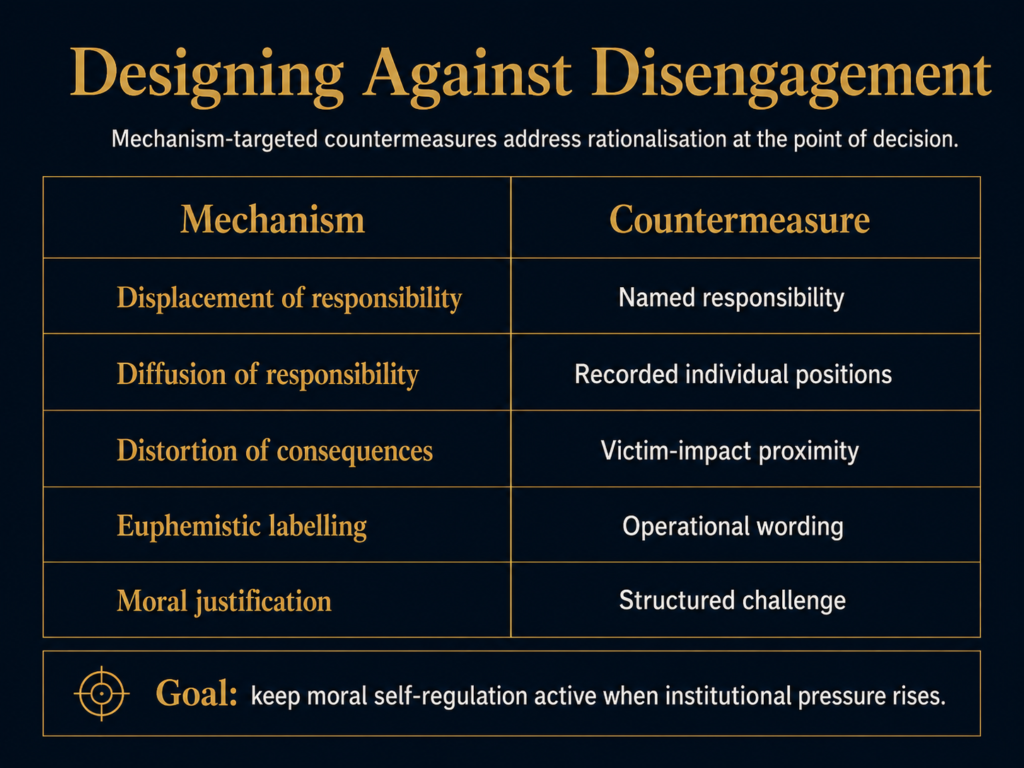
    Albert Bandura formalised the moral disengagement framework across publications from 1986 to 2002, identifying eight cognitive mechanisms through which individuals selectively deactivate their own moral self-sanctions:

    • Moral justification — recasting harmful conduct as serving a higher moral purpose
    • Euphemistic labelling — using sanitised language to obscure the nature of the action
    • Advantageous comparison — comparing the action favourably against worse alternatives
    • Displacement of responsibility — attributing agency to authority figures or institutional mandates
    • Diffusion of responsibility — distributing accountability across group members so no individual bears it
    • Dehumanisation — reducing those affected to categories rather than persons
    • Attribution of blame — assigning causation to the victim or circumstance
    • Distortion of consequences — minimising, ignoring, or misconstruing the harm caused

    Each operates independently. An actor need not activate all eight — a single pathway suffices to suspend moral self-regulation on a specific action while preserving the actor’s general self-concept as an ethical person. This specificity is what makes the framework operationally significant: each mechanism is individually identifiable, measurable, and in principle targetable through specific intervention design.
    Two-column comparison showing ethics system controls beside the cognitive mechanisms they miss.

    The Evidence: Moral Disengagement in Institutional Settings

    Public Sector: Self-Control, Leadership, and the Limits of Sanctions

    Pires, Marques and colleagues surveyed 529 public servants across two major Brazilian federal institutions using structural equation modelling. Instruments included a moral disengagement scale, an ethical culture inventory, self-control measures, and an ethical leadership scale.

    The primary finding: low self-control was the strongest predictor of moral disengagement. Not rule ambiguity. Not weak sanctions. Not pay dissatisfaction. Ethical leadership reduced disengagement scores independently of formal compliance infrastructure. Risk perception and compensation perceptions related to ethical culture but not directly to disengagement. Formal sanctions operated at the extrinsic motivation level — they did not shift disengagement scores.

    The institutional design implication is direct. A system built on sanctions and procedural compliance addresses extrinsic deterrence. The mechanism driving the violation responds to psychological variables: self-regulatory capacity, leadership quality, institutional ethical climate. These are different intervention targets requiring different design logic.

    Limitations are material. Two institutions, one country, no judicial-specific population, no longitudinal arm. Cross-cultural instrument validity outside Brazil is unconfirmed. The findings align with the broader organisational literature but lack replication in judicial populations.

    Organisational Moral Disengagement: When the Institution Itself Disengages

    Fida, Skovgaard-Smith, Barbaranelli and colleagues introduced Organisational Moral Disengagement as a construct distinct from individual moral disengagement. Across four empirical studies, the authors developed and validated a scale measuring the extent to which organisational members perceive the organisation itself as morally disengaged.

    The finding extends the architecture from individual cognition to institutional climate. When members perceive the organisation as morally disengaged, unethical pro-organisational behaviour and silence become normatively expected outcomes. Organisational Moral Disengagement predicted these behaviours independently of individual scores — meaning that even actors with strong personal ethical commitments may engage in or tolerate wrongdoing when the institutional signal is that the organisation has already disengaged.

    For courts and regulatory agencies, the construct raises a pointed question. Does the institutional culture of a given court or judicial council communicate moral engagement — or disengagement? If the signal is disengagement — through tolerance of procedural shortcuts, normalisation of non-compliance, visible non-enforcement of integrity standards — the Fida et al. findings suggest individual-level training will not override the institutional-level signal.

    Constraints on direct application are clear: sector specificity to judicial or regulatory populations is unconfirmed, full sample characteristics are available only in the journal version, and the Organisational Moral Disengagement construct is new and unreplicated in court settings.

    Corruption Rationalisation and the Disengagement Architecture

    The 2025 Regulation & Governance study “The Excuses We Make” maps eight corruption rationalisation strategies directly onto Bandura’s eight mechanisms, establishing a conceptual unification between the corruption rationalisation literature and the disengagement framework. The mapping positions corruption in institutional settings as following the disengagement architecture at the cognitive level — not as a separate phenomenon requiring a separate theory.

    The systematic review by Hameduddin, Engbers and Ritz synthesised 93 studies covering 241 empirical evidence cases on civil servant corruptibility. Moral justification for administrative corruption emerged as the outcome of a multi-layered social cognition process: accountability conflicts, social obligations, and culturally reinforced norms drive rationalisation beyond individual greed. Seven dimensions of corruption micro-foundations were identified, with value conflicts between professional integrity and in-group loyalty constituting a distinct pathway.

    Neither study used the Bandura scale as a primary psychometric instrument. Both mapped cognitive mechanisms conceptually rather than through standardised measurement. Judicial officers were not isolated from general civil service populations. The evidence supports the theoretical architecture but does not provide judicial-specific validation.

    Two-column comparison showing ethics system controls beside the cognitive mechanisms they miss.

    The Gap: Global Judicial Ethics Frameworks and the Missing Cognitive Dimension

    The Bangalore Principles

    The Bangalore Principles of Judicial Conduct remain the primary international reference standard for judicial ethics. Six values — independence, impartiality, integrity, propriety, equality, competence and diligence — are articulated with interpretive commentary.

    The document contains no reference to psychological mechanisms of ethical failure, cognitive disengagement processes, or the behavioural architecture through which judges rationalise violations of the stated values. The framework declares what values judges should hold. It does not engage the mechanism through which judges who hold those values selectively disengage from them under specific conditions. That is a design choice, not an oversight — but it is a design choice with measurable consequences.

    UNODC Judicial Ethics Training

    The UNODC Judicial Ethics Training Package, deployed across 40 pilot sites in 38 countries, is built on the Bangalore Principles and UNCAC Article 11. The training targets knowledge acquisition and principle internalisation through e-learning, trainers’ manuals, and self-directed study.

    One reference mentions awareness of cognitive biases that can affect judicial work. That is the sole psychological element in the training design. Moral disengagement theory does not appear. The eight mechanisms are absent. No intervention exercise targets the rationalisation process.

    The UNODC package is the primary global standard for judicial ethics training. Its reach — 38 countries — makes this gap not incidental but definitional. It is the default condition of the most widely deployed judicial ethics training system operating internationally.

    The ICPC EICS: Infrastructure Without Cognitive Architecture

    The EICS methodology assesses what exists: whether ethics units have been established, codes deployed, training records maintained, integrity committees constituted. It does not assess what these mechanisms produce at the behavioural level. It cannot determine whether zero compliance reflects infrastructure deficit — agencies genuinely lacking the formal apparatus — or disengagement from available infrastructure, where the apparatus exists but actors have cognitively neutralised it.

    That distinction matters for reform design. If the failure is infrastructure deficit, the remedy is investment. If the failure is disengagement from operational infrastructure, the remedy is intervention redesign targeting the cognitive mechanism. The EICS cannot distinguish between these failure modes. Neither can any comparable national integrity assessment framework in the accessible evidence base.

    Does Ethics Training Reach the Disengagement Mechanism?

    The primary counterevidence comes from Mumford and colleagues’ meta-analysis — 66 empirical studies, 106 ethics courses, 150 effect sizes, N=10,069 participants. Ethics training produces medium-effect gains overall, with the largest effects on knowledge acquisition and self-perception, and a smaller but confirmed effect on ethical decision-making.

    The question is whether the decision-making effect reaches the disengagement mechanism or reflects improved performance on training-context scenarios — low-pressure, post-training assessment rather than real institutional decisions under social pressure. No study in the meta-analysis isolated moral disengagement as an outcome variable. None measured pre/post changes in disengagement scale scores following training.

    The meta-analytic evidence is consistent with two interpretations. Training may improve what the actor knows and how they perceive themselves without reducing the cognitive process that suspends knowledge at the moment of conduct. Or some training modalities may partially reach the disengagement mechanism through scenario-based decision practice. The evidence does not resolve which interpretation holds. No subsequent study has tested the question directly in judicial populations.
    Eight-cell matrix listing moral disengagement mechanisms with brief institutional rationalisation labels.

    What Does Disengagement-Targeted Intervention Design Require?

    The framework, unlike general ethics theory, specifies failure points with sufficient precision to design against:

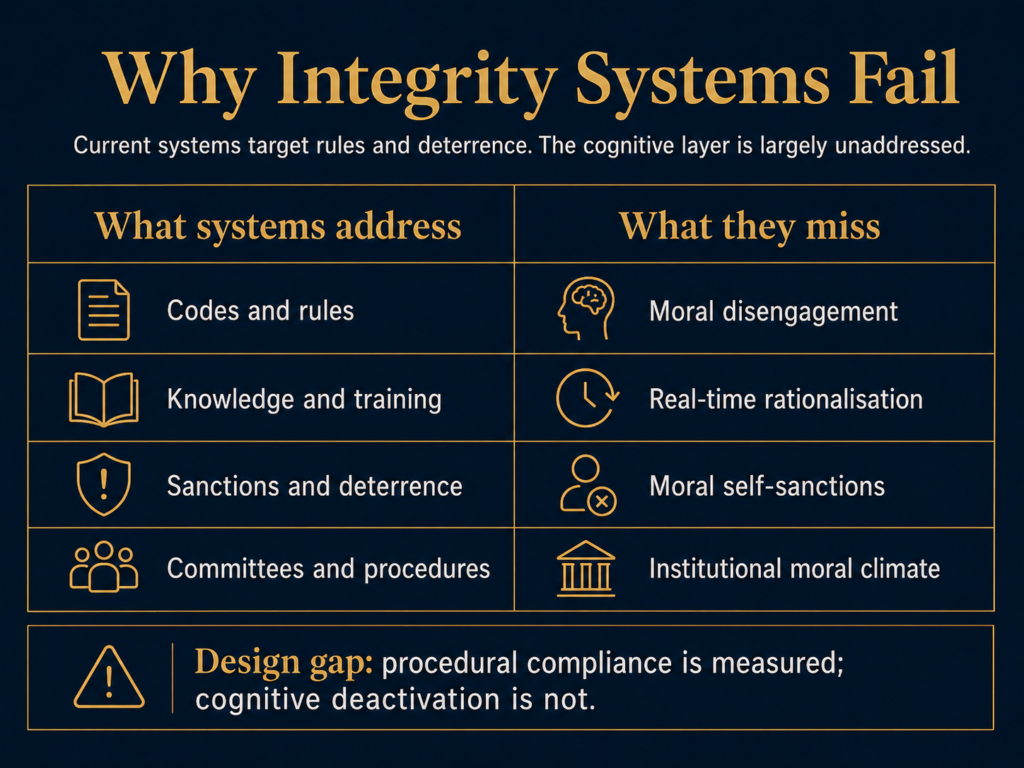
    • Against displacement of responsibility: Named-responsibility provisions that attach an individual officer’s name to specific decisions, eliminating the cognitive availability of “the system required it” or “the committee decided.”
    • Against diffusion of responsibility: Structured accountability where each participant in a collegial decision records their individual position and reasoning before deliberation — preventing post-hoc absorption into collective anonymity.
    • Against distortion of consequences: Victim-impact proximity exercises, not as punitive measures but as cognitive countermeasures making the consequences of institutional action psychologically present at the point of decision.
    • Against euphemistic labelling: Narrative reframing tools requiring institutional actors to describe their actions in operational rather than euphemistic terms during ethics review.
    • Against moral justification: Structured challenge protocols where the justificatory narrative is subjected to peer examination — not the decision itself, but the cognitive frame used to rationalise it.

    No peer-reviewed intervention study has tested these designs against actual disengagement scale scores in public-sector or judicial populations. The intervention logic follows directly from the mechanism theory, but the evidence base is entirely pre-intervention. We know the mechanisms operate. We know current systems do not target them. We know the theoretical architecture for targeting them. The empirical validation gap sits between mechanism evidence and intervention evidence.

    Open Methodological Gaps

    The evidence base, while sufficient to identify the design failure, contains material gaps:

    • No peer-reviewed study has measured Bandura disengagement scale scores in judicial officers as a distinct population
    • No study has assessed whether UNODC Bangalore-based training reduces disengagement scores at any of its 40+ pilot sites
    • No study has mapped which of the eight mechanisms predominate specifically in judicial ethics violations
    • No comparative study tests whether civil law, common law, and hybrid systems differ in mechanism prevalence
    • Bandura’s MMDS has not been validated for non-Western institutional governance populations in the accessible literature
    • The Organisational Moral Disengagement construct has not been applied to courts or regulatory bodies
    • No study has tested named-responsibility provisions, victim-impact proximity, or narrative reframing as interventions against disengagement scores in institutional populations

    Institutional Implications

    Five design implications follow for judicial academies, integrity bodies, and regulatory governance architects.

    Intervention target reclassification. Ethics system design should distinguish between knowledge-tier interventions — codes, training content — and disengagement-tier interventions — mechanism-targeted countermeasures. The two address different failure points. They require different design logic.

    Training redesign. Judicial ethics training programmes, including those built on the Bangalore Principles, should incorporate moral disengagement theory as core curriculum. Officers who understand how they rationalise are better positioned to recognise rationalisation in progress.

    Accountability architecture. Named-responsibility provisions and individual decision recording in collegial contexts target the displacement and diffusion mechanisms directly. These are structural features, not training content — they alter the institutional architecture in which decisions occur.

    Assessment methodology. National integrity assessment frameworks need psychological compliance components alongside procedural ones. A scorecard that cannot distinguish between infrastructure deficit and disengagement from infrastructure cannot diagnose the failure it measures.

    Research commissioning. Judicial academies and international bodies should commission validation studies of the disengagement scale in judicial populations and pilot intervention studies targeting specific mechanisms. The theoretical architecture is mature enough to design against. The validation gap is closeable.


    About VeritasJPS

    VeritasJPS provides evidence-based research and advisory at the intersection of jurisprudence, behavioural science, and institutional governance. Our work supports institutional decision-makers — judges, policymakers, and compliance leaders — with rigorous analysis grounded in empirical evidence and legal scholarship.

    Learn more about VeritasJPS research and advisory work.
  • Cognitive Regulatory Capture: The Independence Failure Anti-Corruption Design Cannot Reach

    Cognitive Regulatory Capture: The Independence Failure Anti-Corruption Design Cannot Reach

    Quick Answer: Cognitive regulatory capture — the gradual alignment of regulator judgment with industry perspectives through familiarity and social proximity — produces enforcement leniency without corruption. A 2025 systematic review establishes it as the dominant capture mode in established democracies. Current governance frameworks, including the OECD Principles, contain no cognitive independence design requirements.


    Abstract

    Regulatory capture discourse centres on structural mechanisms — revolving doors, lobbying, financial incentives — and generates structural solutions: cooling-off periods, disclosure requirements, independent funding. A convergent body of evidence from regulatory sociology, behavioural public administration, and social psychology now documents a distinct capture pathway operating beneath these safeguards. Cognitive regulatory capture — the gradual recategorisation of regulated entities as in-group members through familiarity, social proximity, and professional identity alignment — produces enforcement leniency without any corrupt act, external pressure, or formal institutional failure. A 2025 systematic review consolidates this evidence into a five-concept framework with 33 behavioural indicators, establishing cognitive and cultural capture as the dominant mode in established democracies. The OECD Principles for the Governance of Regulators (2014), still the dominant governance framework, address independence through structural provisions alone and contain no cognitive independence design requirements. This analysis examines the evidence base across jurisdictions, identifies the unresolved empirical questions, and argues that regulatory governance frameworks require cognitive independence protocols — rotation mandates, adversarial review panels, independent challenge functions — as a minimum design standard distinct from anti-corruption rules.

    The Structural Independence Assumption

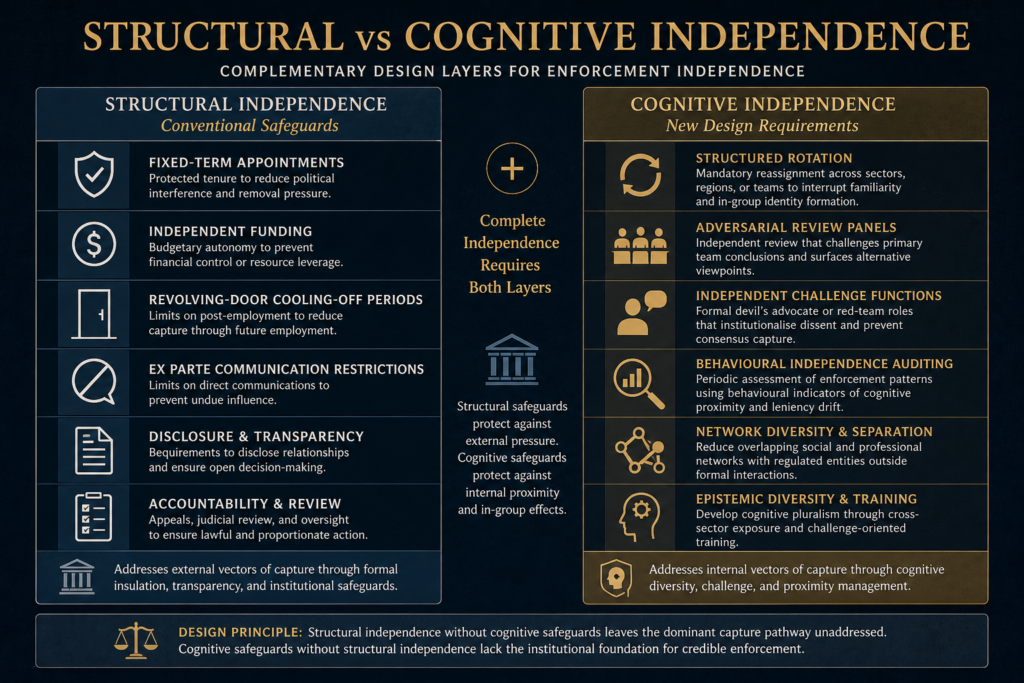
    Regulatory independence doctrine assumes a specific threat model: external actors — industry lobbyists, future employers, political principals — exert pressure on regulatory officials, and institutional design responds by insulating officials from that pressure. Structural provisions follow: fixed-term appointments, independent funding, restrictions on ex parte communications, revolving-door cooling-off periods.

    The OECD Best Practice Principles for the Governance of Regulators (2014) codify this model across seven principles: role clarity, preventing undue influence, decision-making structure, accountability and transparency, engagement, funding, and performance evaluation. The 2017 follow-up, Creating a Culture of Independence, adds five dimensions of de facto independence, including a “culture” dimension addressing staff behaviour norms and conduct policies.

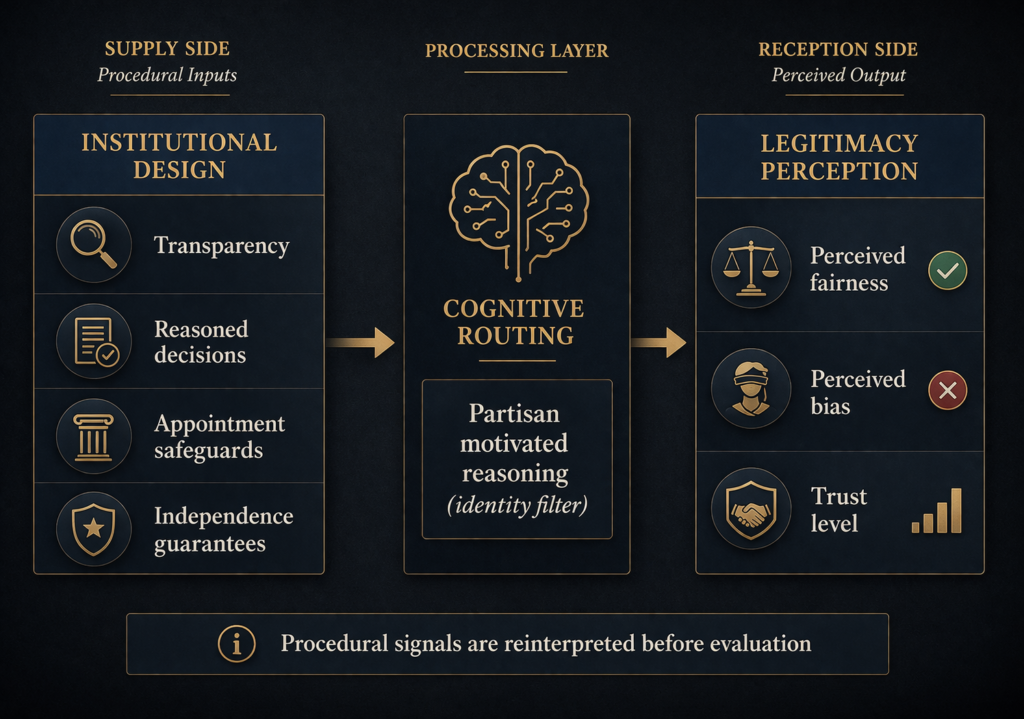
    None of these instruments operationalises cognitive independence. No OECD indicator measures in-group identity formation between regulators and regulated entities. No principle mandates structured rotation. No design requirement specifies adversarial review or independent challenge functions. The governance architecture treats independence as a property of institutional structure. It does not treat it as a property of individual cognition. This is the gap that non-binding guidance — however well-intentioned — cannot close.

    The framework responds to the capture mechanisms that dominated twentieth-century regulatory theory — Stigler’s economic theory of regulation (1971), Peltzman’s refinements, and the post-2008 revolving-door debates. These accounts locate the capture vector outside the regulator. Cognitive capture locates it inside.

    cognitive regulatory capture

    What Is Cognitive Capture — and What Is It Not?

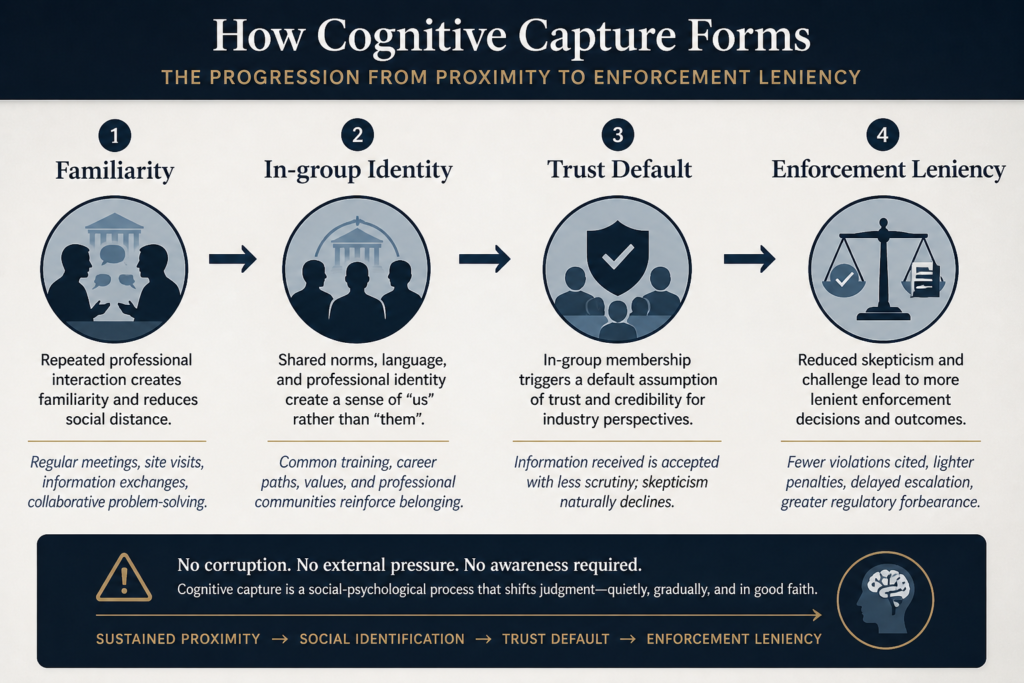
    Cognitive capture is not corruption. No financial incentive. No quid pro quo. No awareness on the part of the captured official. It is not a failure of ethics or integrity in the conventional sense — the official is acting in good faith throughout.

    Chesterfield, Guardiancich, and Heims (2025, Regulation and Governance) provide the most detailed synthesis to date. Their systematic review of 39 studies consolidates cultural capture into five empirical concepts, forming the CHAIN framework:

    • Closeness — direct social ties between regulators and regulated entities developed through repeated professional interaction
    • Homogeneity — shared educational backgrounds, professional training, and career trajectories producing worldview convergence
    • Avoidance — non-challenge of industry positions, where regulators decline to contest industry framing even when evidence supports challenge
    • Identities — shared professional identity formation, where regulators come to see themselves as members of the same professional community as those they regulate
    • Networks — overlapping social and professional networks that sustain proximity outside formal regulatory interactions

    Ten mechanisms operate through these five concepts. The review produces 33 behavioural indicators. The central empirical finding: in established democracies, cultural and cognitive capture has displaced financial capture as the dominant mode. Financial mechanisms have not vanished — but where structural safeguards have reduced explicit corruption, the cognitive pathway has become the primary residual independence risk.

    The definition is precise: cultural capture consists of “social and psychological processes that bias regulators’ beliefs and behaviours, aligning them with those of the regulatees and marginalising alternative viewpoints.” The captured regulator does not adopt industry positions because they have been bought. They adopt them because sustained proximity has made industry perspectives feel reasonable, expert, and aligned with good regulatory practice.

    The Behavioural Independence Gap

    Burchardt (2025, Maastricht Journal of European and Comparative Law) extends this analysis to independence doctrine itself. Working within the ECHR Article 6 and EU judicial framework, Burchardt argues that current independence doctrine is built on formal insulation — structural provisions designed to prevent external interference — and provides no mechanism to address cognitive proximity effects in serving officials.

    In-group bias and familiarity effects, Burchardt argues, operate as structural threats to decisional independence — not episodic ones. They do not arise from a specific conflict of interest that recusal can manage. They arise from accumulated professional proximity over time, producing a baseline shift in judgment that presents as subject-matter expertise rather than bias.

    The design implications follow directly. If independence is treated as a structural property, the response is insulation: separate the decision-maker from external pressure. If independence also has a cognitive dimension, the response must include cognitive interventions: rotation to interrupt familiarity accumulation, adversarial review to challenge in-group consensus, and independent challenge functions to surface viewpoints that proximity has marginalised.

    Burchardt’s analysis is primarily adjudicative — focused on judicial independence within the ECHR framework. Extension to executive regulatory bodies requires an inferential step. But the underlying psychological mechanisms — in-group bias, familiarity-driven trust, cognitive fluency from repeated interaction — are not jurisdiction-specific. They operate wherever sustained professional proximity exists.

    What Does the Field Evidence Show?

    Three empirical studies provide different angles on the mechanism.

    Amore, Le Coq, and Schwenen (2024, HEC Paris working paper) examine US nuclear power plant regulation using administrative panel data and quasi-experimental design exploiting spatial assignment patterns. Inspector experience and spatial proximity interact in determining safety outcomes. Doubling inspector experience is associated with a 0.3 percentage point reduction in emergency training scores at supervised facilities — the authors estimate this as equivalent to approximately USD 1.2 billion in avoided losses annually across the industry. Less experienced inspectors are assigned to facilities farther from regulatory offices, suggesting proximity and experience covary in ways that affect compliance outcomes.

    Clear limitations. Proximity here is spatial and experiential, not social-identity-based. The familiarity mechanism is implicit — the study does not directly measure social identification between inspectors and facility operators. A working paper, peer review pending. But it provides rare quantitative field evidence that something correlated with proximity and tenure affects enforcement stringency in a technically complex regulatory environment.

    Heims (2023, Regulation and Governance) takes a qualitative approach, applying process-tracing to the FDA’s handling of Vioxx — a case study of regulatory failure in pharmaceutical safety. Evidence of cultural capture manifests as absence of critical challenge of industry-submitted data, uncritical repetition of industry framing in regulatory assessments, and failure to seek contradicting evidence during post-market surveillance. Financial capture mechanisms were not confirmed as the primary driver. The behavioural signatures point to cognitive homogeneity and worldview alignment — the regulator and the regulated entity had converged on what constituted reasonable safety evidence without any explicit agreement.

    Inherent limitation of mechanism-tracing: single-case design, selection on a known failure, inability to establish prevalence. But the case provides granular evidence of how cognitive capture manifests — not just that it exists, but what it looks like operationally.

    A 2025 experimental study in Frontiers in Psychology contributes a finding with particular relevance to regulatory staffing. Using a mixed experimental design with an ultimatum game paradigm, the study finds that pro-social individuals — the motivational profile most associated with public service vocations — exhibit stronger in-group favouritism in norm enforcement than pro-self individuals. Pro-socials more readily accept unfair distributions from in-group members. The social identity theory mechanism is confirmed: group identification enhances loyalty and tolerance of in-group norm violations.

    The regulatory implication is counterintuitive. Officials most likely to enter regulatory service — those with strong prosocial orientation and commitment to public good — may be the most susceptible to in-group leniency. Regulatory staffing that selects for public service motivation may simultaneously select for heightened capture vulnerability through the same psychological mechanism.

    Laboratory setting, general population sample, not regulatory professionals. Ecological validity for enforcement contexts is undemonstrated. But the mechanism — pro-social orientation amplifying in-group favouritism — speaks directly to institutional design.

    Two-column framework comparing structural safeguards with cognitive independence design requirements

    The In-Group Identity Puzzle: An Unresolved Conflict

    The social identity theory prediction is straightforward: group identification produces leniency toward in-group members. This aligns with the Chesterfield et al. synthesis, the Heims case study, and the experimental evidence.

    A competing theoretical strand — normative focus theory — predicts the opposite. If group identity heightens normative expectations, in-group members who violate group norms may face harsher enforcement. The in-group violator has betrayed shared standards, triggering a normative enforcement response rather than a leniency response.

    Shayo and Zussman (published in the Journal of the European Economic Association; NBER Working Paper 25355) provide partial field evidence from Israeli small claims courts. Using naturally occurring judicial decision data and judge-litigant ethnicity matching, they find in-group leniency in sentencing — judges are more lenient toward same-group defendants — but a marginally opposing effect in conviction decisions in some specifications. In-group bias operates even under strong non-discriminatory institutional norms. Its direction may vary by decision type.

    For regulatory governance, this unresolved conflict matters practically. If cognitive proximity produces leniency in enforcement discretion (the dominant prediction), rotation and adversarial review are appropriate design responses. If it produces heightened normative enforcement (the minority prediction), proximity might in some contexts serve regulatory objectives. Current evidence supports the leniency prediction in most settings. The conflict is not resolved by existing regulatory field data.

    The Competence-Capture Tradeoff

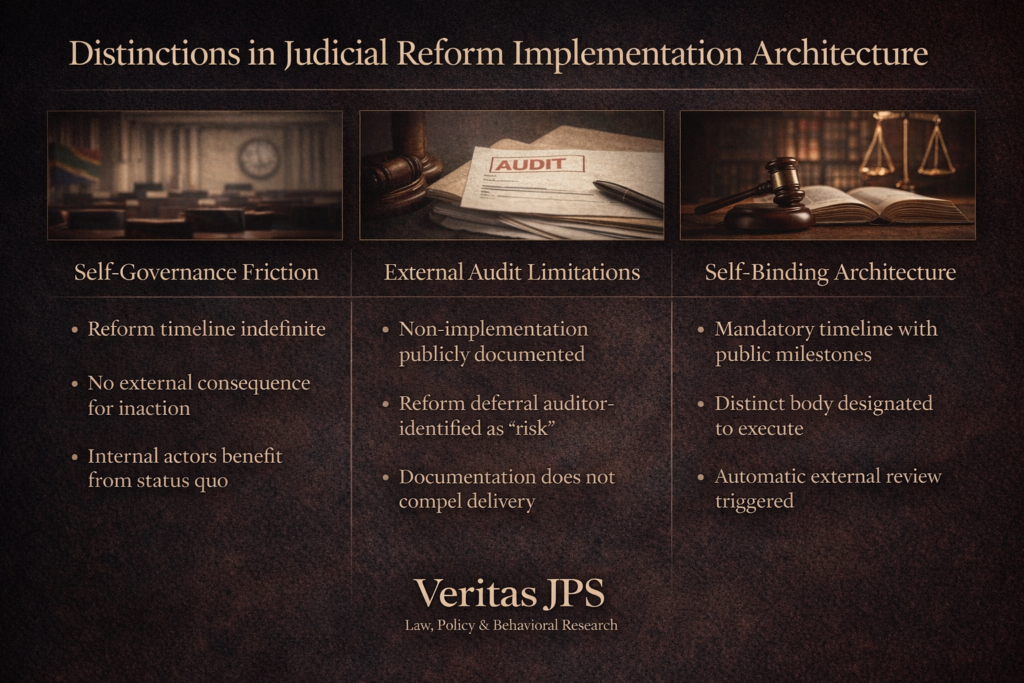
    Any proposal to interrupt cognitive proximity through rotation or tenure limits confronts the competence argument. Deep sector knowledge improves regulatory decision quality. Regulators who understand their industry make more proportionate, better-targeted enforcement decisions. Rotation imposes learning curves, reduces institutional memory, and may undermine deterrence credibility. The structural friction in self-governance bodies — where reform mandates die at implementation — illustrates the practical costs of institutional redesign without adequate transition infrastructure.

    Not merely a theoretical objection. The OECD engagement principle (Principle 5, 2014) explicitly values regulator-industry engagement as a source of regulatory quality. Amore et al. (2024) provide partial empirical support: more experienced inspectors at nuclear facilities are associated with better safety outcomes overall, even as their proximity correlates with reduced enforcement stringency on specific measures. Competence and capture may be co-products of the same exposure.

    No study has quantified this tradeoff. Commentary in the regulatory governance literature identifies rotation costs — competence loss, institutional memory depletion, compliance relationship disruption — but no field study has measured these costs against measured leniency-reduction from rotation. The design question remains empirically open: at what tenure length does the capture cost exceed the competence gain?

    The Audit Detection Gap

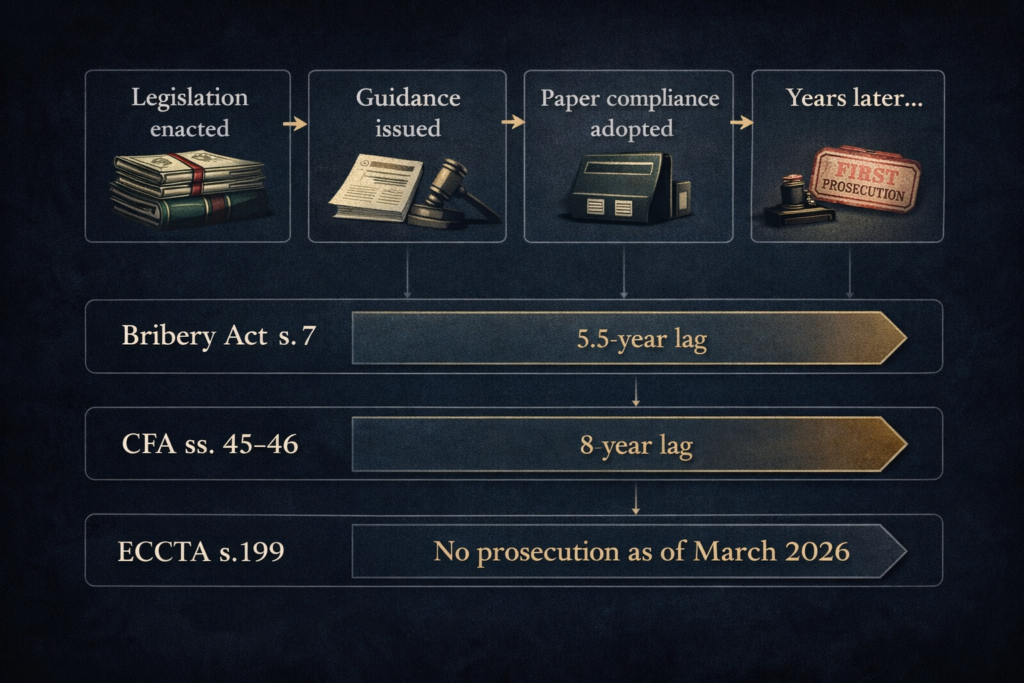
    Cognitive capture is audit-resistant. The enforcement leniency it produces is behaviourally indistinguishable from enforcement proportionality. An inspector who applies a lighter touch because familiarity has shifted their judgment looks identical — to any external audit instrument — to an inspector whose professional judgment has matured. Where paper compliance masks structural failure in corporate liability regimes, cognitive capture masks enforcement drift beneath the appearance of proportionate regulation.

    Moseley and Thomann (2017, in Behavioural Public Administration, Cambridge University Press) document this directly. Inspectors apply more lenient enforcement styles to regulatees they perceive as trustworthy and compliant — a perception developed through repeated interaction. The behavioural output is indistinguishable from proportionate enforcement judgment. Audit instruments measure compliance with procedures. They do not measure the cognitive state producing enforcement decisions.

    The 33 CHAIN indicators developed by Chesterfield et al. represent the most structured attempt to date to make cognitive capture observable at the organisational level. They operate at the organisational level only — identifying cultural capture risk across a regulatory body, not diagnosing it in an individual official. No validated behavioural instrument exists to assess cognitive independence at the individual level.

    What Would Cognitive Independence Design Require?

    If regulatory governance frameworks incorporated cognitive independence as a design parameter — alongside structural independence — the evidence base points to several candidate interventions.

    Structured rotation — mandatory reassignment of regulatory staff across sectors, regions, or regulatory teams at defined intervals. Interrupt familiarity accumulation before in-group identity consolidates. The cost: competence loss and learning-curve effects that remain unquantified against capture reduction.

    Adversarial review panels — independent review functions that challenge enforcement decisions from outside the primary regulatory team. Surface alternative viewpoints that cognitive proximity has marginalised — the “Avoidance” concept in CHAIN. Untested against cognitive capture pathways.

    Independent challenge functions — formalised devil’s advocate or red-team roles within the regulatory body. Institutionalise dissent as a structural feature rather than relying on individual willingness to challenge in-group consensus.

    Behavioural independence auditing — periodic assessment of enforcement patterns using the CHAIN behavioural indicators or equivalent instruments, looking for organisational-level signatures of cognitive proximity effects.

    None has been empirically validated in a regulatory field context. These are design proposals derived from the evidence base, not evidence-based designs. The gap between identifying the mechanism and demonstrating that a specific intervention interrupts it remains open.

    Jurisdictional Coverage and Missing Evidence

    The evidence base is concentrated in established democracies. The United States provides the most granular field evidence — nuclear safety, pharmaceutical regulation, judicial sentencing. The EU contributes doctrinal and institutional analysis. Cross-national systematic review evidence covers established democracies broadly but does not disaggregate by jurisdiction.

    Entirely absent: sub-Saharan African regulatory bodies, South and Southeast Asian regulatory systems, Latin American regulators, post-Soviet transition economies. Whether cognitive capture mechanisms operate differently in lower-capacity regulatory environments — where structural independence may be weaker to begin with — is unknown.

    Sector coverage is similarly uneven. Financial conduct regulation, telecommunications, environmental enforcement, and competition authorities post-2020 have no identified field-level evidence on cognitive capture mechanisms. Cross-sector comparative evidence — whether capture intensity differs between high-discretion regulators and rule-bound inspectorates — does not exist.

    Conclusion: Design Implications for Institutional Decision-Makers

    Five institutional implications follow from the evidence.

    Cognitive proximity is a measurable regulatory governance risk, not a speculative concern. The 2025 systematic review, corroborated by field studies across nuclear safety, pharmaceutical regulation, and judicial decision-making, establishes that social-psychological mechanisms produce enforcement leniency independent of financial incentives.

    Structural independence is necessary but insufficient. Governance frameworks built exclusively on formal insulation — including the OECD Principles — leave the dominant capture mechanism in established democracies unaddressed. The architecture assumes the problem is external. The evidence shows it is internal.

    Cognitive independence design requirements — rotation mandates, adversarial review, challenge functions — belong in governance frameworks as minimum standards, not optional supplements or conduct guidance. A different threat vector than anti-corruption rules. A separate design layer. The risk to institutional legitimacy is not hypothetical — integrity systems that fail by design share the same structural blind spot.

    The competence-capture tradeoff requires empirical quantification before rotation mandates can be calibrated. Design without evidence risks replacing one governance failure with another. The tradeoff is real. The current evidence base does not resolve it.

    Audit and evaluation frameworks need cognitive independence indicators. Structural independence assessments that measure governance arrangements, funding autonomy, and appointment procedures without measuring behavioural indicators of cognitive proximity miss the mechanism that poses the greatest residual risk to enforcement independence.


    About VeritasJPS

    VeritasJPS provides evidence-based research and analysis and advisory at the intersection of regulatory governance, behavioural science, and institutional design. Our work supports institutional decision-makers — regulators, judicial councils, policymakers, and compliance leaders — with analysis grounded in empirical evidence and legal scholarship.

    Learn more: [website URL]

  • Reactive Devaluation in ENE Design: Why Proposal Attribution Defeats Settlement

    Reactive Devaluation in ENE Design: Why Proposal Attribution Defeats Settlement

    Abstract

    Reactive devaluation in ENE design explains why early neutral evaluation programs that use attributed proposals may undermine settlement before substantive evaluation begins. Early neutral evaluation programs in courts worldwide use attributed proposals as the default format for settlement exchange — the opposing party’s name attaches to the offer. Experimental evidence spanning three decades establishes that this design choice activates reactive devaluation, a cognitive mechanism by which disputants automatically discount proposals attributed to the counterparty regardless of substantive merit. This analysis traces the evidence from foundational social psychology experiments through legal negotiation replications and commercial dispute contexts, examines the absence of cognitive architecture provisions in the UNCITRAL Model Law on International Commercial Mediation (2018) and the Singapore Convention on Mediation (2019), and evaluates debiasing mechanisms including anonymous framing and single-text procedures. It maps the jurisdictional and methodological gaps that leave this design defect unaddressed by any binding international instrument, and assesses the boundary conditions — ecological validity, repeat-player attenuation, cultural moderation — that qualify the extrapolation from laboratory to courtroom.

    The Cognitive Mechanism: What Reactive Devaluation Does

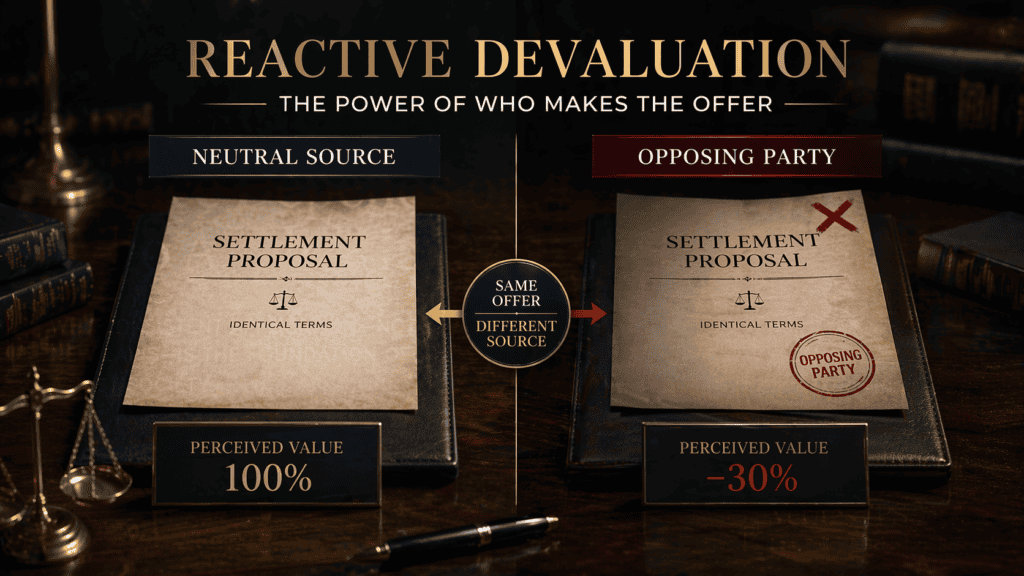
    Reactive devaluation describes a specific and replicable cognitive pattern: when a proposal is attributed to an adversary, recipients rate it as less attractive, less fair, and representing a smaller concession than an identical proposal attributed to a neutral source or their own side. The mechanism is automatic — it operates before substantive evaluation of the proposal’s terms.

    Stillinger, Epelbaum, Keltner, and Ross (1990) documented this effect in two experiments. The first presented US members of the public with nuclear arms-reduction proposals attributed to either President Reagan or General Secretary Gorbachev — identical proposals received different attractiveness ratings depending on attributed source. The second asked Stanford undergraduates to evaluate a divestment compromise attributed to the university administration versus a neutral source. Proposals attributed to the administration were rated as representing a less significant concession. Ross and Stillinger (1991) subsequently characterised reactive devaluation as one of three psychological barriers to conflict resolution, alongside partisan perception and naive realism.

    The finding is directional and consistent: across every experimental condition, attribution to an adversarial source reduced proposal acceptance. The mechanism is not strategic posturing — subjects did not consciously decide to reject the counterparty’s offer for tactical reasons. The discounting was perceptual. They genuinely evaluated the same terms as worse when they knew who proposed them.

    Proposal attribution triggering reactive devaluation in ENE

    Replication in Legal Negotiation Settings

    The question for ENE program design is whether reactive devaluation operates in legal dispute contexts with the same reliability as in social psychology experiments. The available evidence says yes. The caveats concern ecological validity.

    Korobkin and Guthrie (1994), published in the Michigan Law Review, conducted nine laboratory experiments with approximately 450 subjects — law students and lay populations at Stanford’s Center on Conflict and Negotiation. Their findings confirmed that reactive devaluation was operational in simulated litigation settlement negotiation. Subjects discounted settlement offers attributed to the opposing party relative to identical offers attributed to a neutral or own-side source. The effect held alongside framing and equity-seeking biases, suggesting reactive devaluation operates as an independent cognitive variable rather than a downstream effect of other negotiation biases.

    Korobkin and Guthrie (2004), writing in the Harvard Law Review, extended this analysis by examining how reactive devaluation, anchoring, and framing biases interact in legal bargaining. Their synthesis identified the cognitive architecture of proposal exchange — who proposes, at what stage, in what format — as a design variable with measurable effects on settlement outcomes. When counterparty attribution triggers reactive devaluation and combines with initial offer anchoring, settlement resistance amplifies beyond what either bias produces alone.

    The ecological validity caveat is real. These were laboratory experiments. Subjects operated without legal counsel, without the iterative positional dynamics of actual litigation, and without the institutional structure of a formal ENE session. Korobkin and Guthrie acknowledged that legally represented parties in institutional ENE may exhibit different magnitudes of reactive devaluation — counsel may partially buffer direct client-to-counterparty attribution exposure. Whether counsel reduces the effect, amplifies it by adopting the bias on behalf of clients, or has no measurable impact remains untested.

    Early neutral evaluation and settlement negotiation bias

    Beyond the Laboratory: Commercial Dispute Evidence

    Yam, Fong, and Chan (2020), published in the ASCE Journal of Management in Engineering, extended reactive devaluation documentation into construction project dispute negotiation. Through practitioner survey and conceptual framework synthesis, they found that counterparty attribution of proposals reduced acceptance rates among construction industry practitioners — a finding consistent with the foundational psychological literature but situated in a commercial, repeat-player-adjacent context.

    This matters for ENE design because construction disputes are among the most common candidates for court-annexed ADR, and construction disputants are often repeat players within the same industry. If reactive devaluation operates even where parties have prior transactional history, the assumption that familiarity attenuates the effect is weakened. The Yam et al. study does not resolve this conclusively — its survey methodology lacks the experimental control needed to isolate attribution as an independent variable — but it provides directional evidence that the mechanism persists outside the laboratory.

    A 2023 laboratory experiment on conciliation and pre-trial settlement, published through HAL Open Science, examined neutral third-party conciliation — structurally analogous to a single-text procedure — in a French civil dispute simulation. Conciliation improved bargaining efficiency by reducing impasse rates. Not a direct test of reactive devaluation, but the finding aligns with debiasing theory: removing bilateral attribution from the exchange process and substituting a neutral third-party text reduces the cognitive triggers that impede agreement.

    The International Instrument Gap

    The most consequential finding for institutional decision-makers is not what the experimental record shows about reactive devaluation. It is what the binding international instruments do not address.

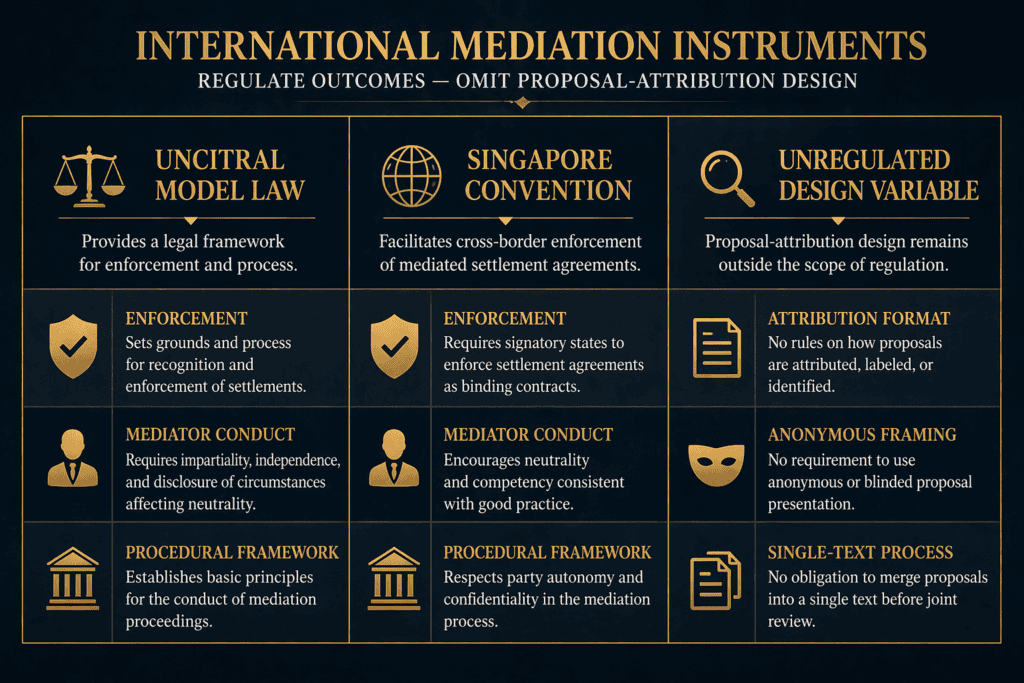
    The UNCITRAL Model Law on International Commercial Mediation, as amended in 2018, governs the procedural framework for international commercial mediation and the enforcement of international settlement agreements. Its provisions address mediator appointment (Article 5), conduct of mediation (Article 6), confidentiality (Article 7), the mediator-as-arbitrator restriction (Article 12), and enforcement mechanisms. The 2018 amendments focused on terminology standardisation — replacing “conciliation” with “mediation” — and enforcement of settlement agreements resulting from mediation. No article, no provision, and no explanatory note addresses the cognitive architecture of proposal exchange. Whether proposals should be attributed, anonymous, or mediator-owned is not covered.

    The United Nations Convention on International Settlement Agreements Resulting from Mediation (Singapore Convention, 2019) governs the cross-border recognition and enforcement of mediated settlement agreements. Article 5 establishes grounds for refusing enforcement, including mediator impartiality failure and breach of applicable standards. The Convention addresses the enforceability of outcomes but contains no provision addressing the cognitive architecture of the process that produces those outcomes. Proposal attribution format, cognitive bias mitigation, and single-text procedure requirements are absent from the text.

    Both instruments regulate the downstream products of mediation — the enforceability of settlement agreements, the conduct of mediators, the procedural framework — while leaving the upstream cognitive variables that determine whether settlement is reached entirely unaddressed. A building code that specifies the tensile strength of structural steel but says nothing about where to pour the foundations.

    reactive devaluation

    Debiasing Mechanisms: What Exists, What Has Been Tested

    Two principal debiasing mechanisms target reactive devaluation at the design level.

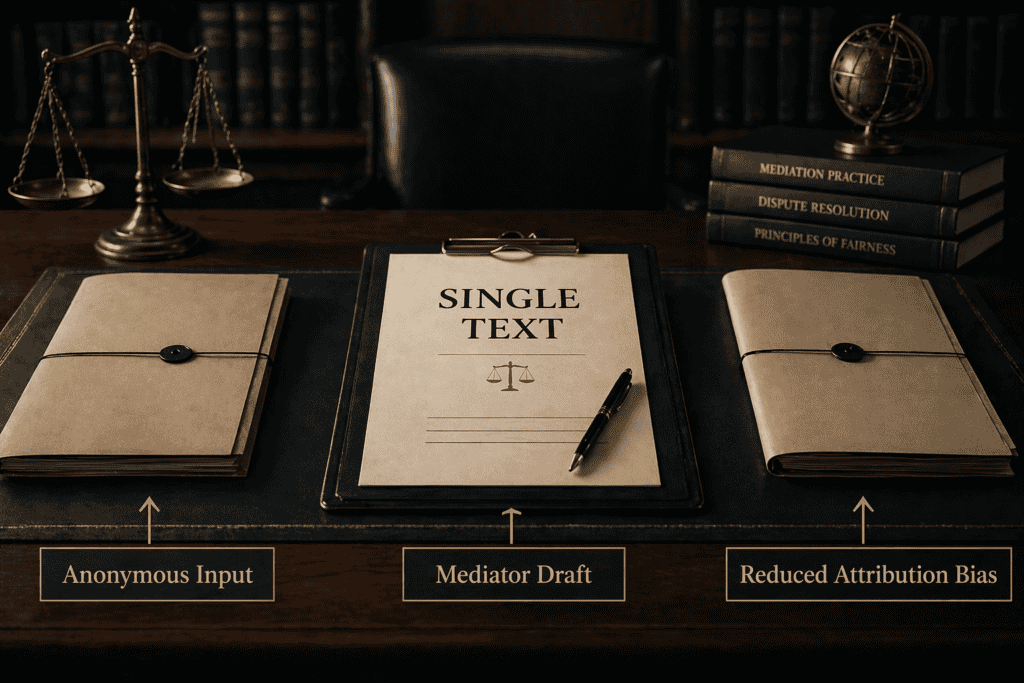
    Anonymous framing removes counterparty attribution entirely. Proposals are submitted and presented without identifying which party originated them. The neutral evaluator receives both parties’ positions and presents options without source labels. This directly eliminates the cognitive trigger — if the disputant does not know who proposed the terms, the attribution-based discounting mechanism has no target.

    Single-text procedure, formalised in Roger Fisher’s scholarship and operationalised most prominently at the Camp David negotiations (1978), takes a different structural approach. The mediator drafts and owns a single working document. Neither party is identified as the source of any specific term. The mediator revises the text iteratively based on each party’s input, but the document is always attributed to the mediator — never to either disputant. This neutralises reactive devaluation by ensuring that no term in the working text can be discounted based on counterparty attribution.

    Camp David is the most prominent application. President Carter used a single-text process over 13 days of negotiation between Israeli and Egyptian delegations. Neither delegation proposed terms directly to the other. Carter’s team drafted and revised a single document — 23 successive drafts before the final version. The process produced a binding peace treaty. Fisher and Ury subsequently formalised the method in Getting to Yes (1981).

    The limitation is clear: one case in an exceptional political context. No randomised comparison with attributed-proposal formats exists. The ecological validity for court-annexed ENE — where stakes are commercial rather than geopolitical, where parties are private litigants rather than sovereign states, and where time horizons are weeks rather than decades — is asserted by analogy rather than demonstrated by experiment.

    ENE Program Efficiency and the Attribution Question

    Empirical analysis of mandated ENE programs in US federal courts has found no discernible increase in settlement efficiency among courts that mandate ENE compared to those that do not. Citation reflects reported judicial practice. Verify with primary case law databases for specific authority. If mandatory ENE does not improve settlement rates, what design variables account for the underperformance?

    The reactive devaluation literature suggests one candidate: the default attributed-proposal format. If ENE sessions present proposals with counterparty attribution, and the mechanism operates with the reliability the experimental record indicates, then settlement rates in attributed-proposal ENE would be systematically lower than those achievable under anonymous or single-text alternatives — even when all other programme variables are held constant.

    No study in the accessible record has isolated proposal attribution format as an independent variable in a field study of court-annexed ENE settlement rates. That is the primary measurement gap.

    Counterevidence and Boundary Conditions

    Three qualifications apply.

    A 2022 behavioural analysis published in the German Law Journal examined mediator role in international disputes and found that a biased mediator does not negatively affect settlement efficiency. This partially complicates the cognitive architecture argument: if mediator neutrality itself is less outcome-determinative than assumed, the claim that attribution-format design is the dominant variable requires closer examination. The study does not directly test reactive devaluation, but it introduces a competing hypothesis about which cognitive variables carry the most weight.

    The laboratory-to-courtroom ecological validity gap remains unresolved. Every experimental replication used simulated disputes without legal counsel. Whether the effect attenuates when parties are legally represented — because counsel buffers direct counterparty attribution exposure — or persists at full magnitude is not established. Counsel may also amplify the bias by adopting adversarial framing on behalf of clients.

    The record is silent on cultural moderation. Whether reactive devaluation operates with the same magnitude in civil law inquisitorial systems, where judicial mediation is structurally different from common law adversarial ENE, has not been tested. Cross-cultural replication is absent.

    Jurisdictional Coverage and Evidence Gaps

    The experimental and field evidence covers:

    • United States — foundational social psychology experiments (Stillinger et al., 1990), legal negotiation laboratory replications (Korobkin & Guthrie, 1994, 2004), and federal ENE efficiency data
    • Hong Kong / International — construction dispute practitioner evidence (Yam et al., 2020)
    • France — laboratory conciliation experiment (HAL, 2023)

    Missing from the record: the United Kingdom (no published study on reactive devaluation in CPR-governed ENE), the European Union (no study within the EU Mediation Directive 2008/52/EC framework), Australia (no study in court-annexed mediation under Federal Court or state court rules), Singapore, any civil law jurisdiction with a controlled attribution study, and any Global South jurisdiction.

    Implications for ENE Program Design

    Five conclusions for institutional decision-makers.

    Reactive devaluation is the most empirically documented cognitive obstacle to voluntary settlement in adversarial dispute resolution. The mechanism replicates across contexts, and no published experiment reports a null finding.

    The default attributed-proposal format used in court-annexed ENE programs activates this mechanism by design. The format is not cognitively neutral.

    No binding international ADR instrument — including the UNCITRAL Model Law and the Singapore Convention — addresses proposal attribution format or cognitive architecture in procedure design.

    Debiasing mechanisms exist. Anonymous framing and single-text procedures directly target the attribution trigger. Both are implementable as procedural design changes without legislative amendment.

    The primary gap is not in the cognitive science — it is in the field evidence. No controlled comparison of attributed versus anonymous ENE settlement rates has been published. Until that study is conducted, the case for format change rests on laboratory evidence extrapolated to institutional settings. For any judicial council considering ENE programme reform, the threshold question is whether three decades of consistent laboratory findings justify a procedural design change that carries no downside risk and requires no legislative action.


    About VeritasJPS

    VeritasJPS provides evidence-based research and advisory at the intersection of jurisprudence, behavioural science, and dispute resolution design. Our work supports institutional decision-makers — judges, policymakers, and ADR programme administrators — with rigorous analysis grounded in empirical evidence and legal scholarship.

    Learn more: [website URL]

  • Courts Have Never Been Sludge-Audited — That Is a Governance Failure, Not an Oversight

    Courts Have Never Been Sludge-Audited — That Is a Governance Failure, Not an Oversight

    Abstract

    Sludge audits — structured assessments of cognitive, emotional, and administrative friction in government processes — have been applied across tax, benefits, health, and licensing in 14 OECD member states since 2023. Court-facing procedural communications remain absent from every published audit. The administrative burden framework, validated across multiple government domains, predicts that procedural complexity triggers citizen disengagement before formal non-compliance occurs — through heuristic shortcuts activated at first contact with documentation requirements. This analysis examines why sludge audit courts exclusion persists in the highest-stakes compliance environment in public administration, and argues that judicial councils should treat sludge audits of procedural communications as a governance obligation.

    The Cognitive Mechanism: Friction Before Failure

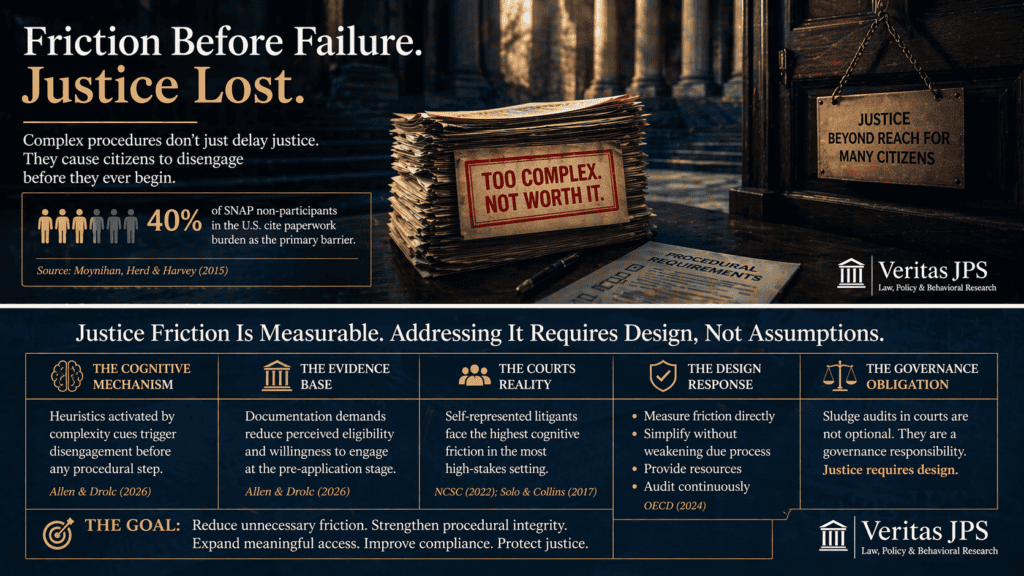
    The administrative burden framework developed by Moynihan, Herd, and Harvey identifies three distinct cost types that predict citizen disengagement from government programmes: learning costs (knowing what is required), psychological costs (stigma, stress, confusion), and compliance costs (documentation and procedural steps). Of these, compliance costs carry the strongest direct empirical base. In U.S. federal programme data, 40% of SNAP non-participants cited paperwork burden as the primary barrier to participation.

    The mechanism is not rational calculation. It is heuristic. Allen and Drolc’s 2026 experiments (N=4,376 across three pre-registered studies) demonstrate that documentation requirements and mismatched effort-time cues reduce perceived eligibility and willingness to apply at the pre-application stage — before any procedural step has been taken. Citizens assess complexity cues and withdraw. The cognitive shortcut fires before the rational evaluation begins.

    This finding has a critical qualification. Allen and Drolc found that prompting respondents to estimate effort concretely reversed the heuristic effect — but only among those who already possessed the required documentation or could form a concrete time estimate. For populations that lack both resources and procedural familiarity — the defining characteristic of self-represented litigants — friction reduction alone is insufficient without resource provision. The two interventions are complementary, not substitutable.

    Administrative burden framework showing learning, psychological, and compliance costs in court procedures

    Sludge Audits: Where They Have Been Applied — and Where They Have Not

    The OECD’s Fixing Frictions report (2024), documenting the International Sludge Academy’s work across 16 government teams in 14 countries, establishes Good Practice Principles for auditing time, cognitive, emotional, and social burdens in administrative processes. Ten case studies cover tax administration, health check attendance (NSW achieved a 24% increase), licensing, and internal government operations.

    Court-facing procedural communications are absent from all ten case studies. The OECD OPSI’s October 2025 update confirms that an international sludge audit methodology is under development by an expert panel chaired by Cass Sunstein, scoped to “administrative processes and services.” Enforcement communications receive a reference in the context of regulatory compliance — not citizen-facing court procedure.

    Pakistan’s PIDE has produced a judicial system sludge audit (Vol. 3, 2023-2025) estimating the economic costs of procedural delays and administrative friction in criminal trials. This appears to be the only published sludge audit applied to a judicial system in any jurisdiction. Its focus on transaction costs rather than citizen cognitive pathways limits direct comparability with the OECD framework, but its existence confirms that judicial procedure is auditable — the institutional choice not to audit it elsewhere is a governance decision, not a technical constraint.

    Why Courts Have Been Excluded from Sludge Audits

    Three structural features distinguish court procedures from the government domains where sludge audits have been applied.

    First, procedural complexity in courts is mandated by statute. Civil procedure rules, service requirements, and filing deadlines exist because the adversarial system requires procedural integrity. Friction reduction in tax forms does not raise due process concerns. Friction reduction in court filing requirements does — or is perceived to.

    Second, court procedures are adversarial. In benefits and tax settings, the government and the citizen share an interest in successful completion. In litigation, one party may benefit from the opponent’s cognitive friction. Sludge audit methodology has not been tested in adversarial contexts where friction serves a strategic function.

    Third, procedural design in courts has been treated as a question of law, governed by rules committees and judicial councils, rather than a question of behavioural design. Brennan-Marquez and Maher’s 2025 analysis in the Georgetown Law Journal identifies “micro-costs” — tiny attentional impositions that deplete cognitive resources cumulatively — as a mechanism producing procedural dropout among justice-impacted individuals. The framing is significant: it places cognitive friction inside legal scholarship, not outside it.

    None of these features justifies the absence of cognitive friction assessment. They explain why courts have avoided it. They do not establish that avoidance is defensible.

    sludge audit courts

    The Access-to-Justice Dimension

    Self-represented litigants constitute 50-80% of family law proceedings in Canada and an estimated 12-30% of federal civil caseloads in the United States. In U.S. federal courts between 1998 and 2017, pro se plaintiffs won only 3% of final judgments compared with parity outcomes when both parties were represented.

    The dominant reform discourse frames this gap as a legal representation deficit. It is — but it is also a procedural design deficit that cognitive friction analysis predicts and that the current reform frame cannot diagnose. The European Court of Human Rights held in Airey v Ireland (1979) that the right of access to court under Article 6 must be practical and effective, not theoretical and illusory. Procedural communications that exceed the cognitive processing capacity of the populations they govern produce theoretical access — and court accessibility frameworks that omit cognitive dimensions remain incomplete.

    Default judgment rates in SRL-heavy dockets, case abandonment, and strike-out rates are downstream outputs of cognitive friction. No published study has isolated default judgment rates attributable specifically to procedural cognitive load — as distinct from legal representation gap or case-merits disparity — in any jurisdiction. That isolation is the single most actionable empirical gap for judicial councils.

    Institutional Implications for Judicial Sludge Audits

    Three governance actions follow from this evidence.

    First, judicial councils should commission sludge audits of their public-facing procedural communications — filing requirements, hearing notices, self-represented litigant guides, default judgment warnings — using the OECD Good Practice Principles as a methodological starting point, adapted for adversarial contexts. The failure of judicial integrity systems to self-diagnose procedural barriers reinforces the case for external audit methodologies.

    Second, the OECD’s ongoing international sludge audit methodology development should explicitly include judicial and enforcement procedures in its scope. The absence of courts from the current framework is not a technical limitation — it is a scope decision that can be revised.

    Third, the cognitive friction finding and the legal aid finding are complementary, not competing. Friction reduction without resource provision is insufficient for populations lacking documentation and procedural familiarity. Resource provision without friction reduction leaves the procedural architecture intact as a cognitive barrier. Reform strategies that address one without the other will produce incomplete results.

    Citation reflects reported judicial practice. Verify with primary case law databases for specific authority. (Applied to: Hjalmarsson & Neilson 2026 working paper; PIDE judicial sludge audit)

  • Confirmation Bias on the Bench: Why Judicial Debiasing Without Psychometric Baseline Assessment Is Institutional Guesswork

    Confirmation Bias on the Bench: Why Judicial Debiasing Without Psychometric Baseline Assessment Is Institutional Guesswork

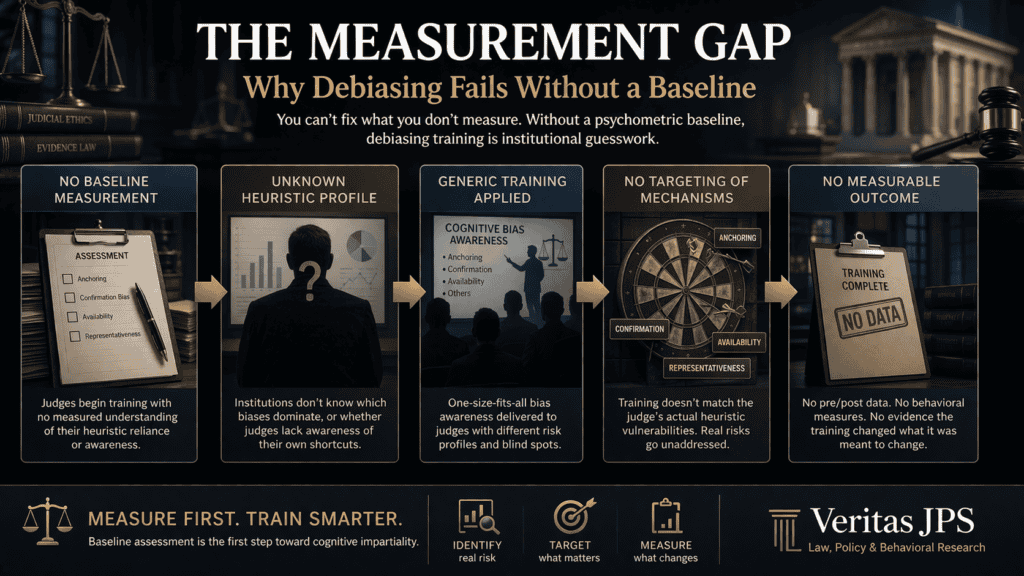
    Judicial training institutions across common law and civil law systems deliver cognitive debiasing curricula without first establishing whether — or to what degree — the judges being trained rely on the heuristics those programmes target. The publication of the Judicial Heuristics Awareness Questionnaire (J-HAQ) by Malegiannaki, Chatzopoulos, and Tsagkaridis in March 2025 marks the first validated psychometric instrument designed specifically for judicial populations. Its central findings — that years of professional experience show no statistically significant correlation with heuristic reliance or metacognitive awareness, and that judges fall into distinct high- and low-awareness clusters — expose a structural gap in every existing judicial training design: no programme in the documented record uses validated pre-intervention baseline assessment. This analysis examines the J-HAQ’s methodology and implications alongside two decades of convergent empirical evidence, the comparative institutional training landscape, and the normative frameworks that govern judicial competence — none of which currently require measured cognitive performance as a training design input. The absence of judicial debiasing psychometric assessment at the programme design stage means that interventions remain untested against the very cognitive mechanisms they claim to address.

    The Measurement Problem in Judicial Debiasing

    Judicial education on cognitive bias is not new. Since Guthrie, Rachlinski, and Wistrich published their landmark 2001 study demonstrating that 167 US federal magistrate judges were susceptible to all five tested cognitive illusions — anchoring, framing effects, hindsight bias, representativeness, and egocentric bias — the proposition that judges are not immune to systematic cognitive error has moved from controversial claim to settled premise. Judicial academies in multiple jurisdictions now include cognitive bias content in continuing professional development programmes.

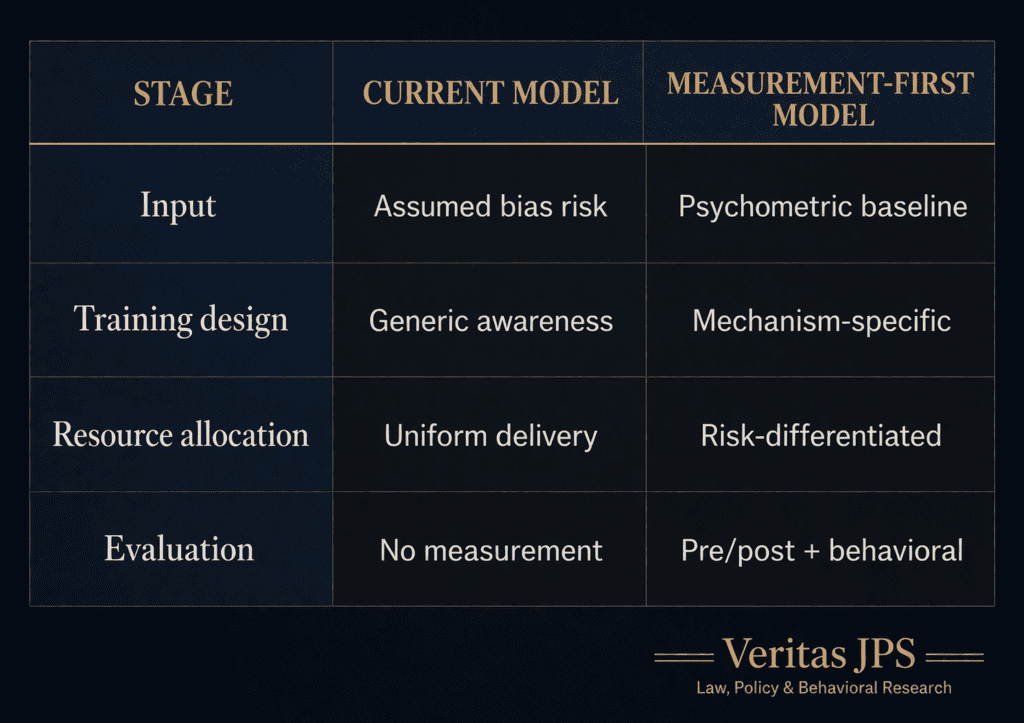
    What has not moved is the measurement infrastructure. The question is no longer whether judges are susceptible to heuristics — the empirical record is convergent on that point across methods, jurisdictions, and legal traditions. The question is whether any judicial training institution can demonstrate that its debiasing intervention actually changes the target behaviour. That requires measurement before and after the intervention. Until March 2025, no validated psychometric instrument existed to provide that measurement for judicial populations specifically.

    The distinction matters more than it might appear. General cognitive bias instruments — the Cognitive Reflection Test, anchoring sensitivity tasks, framing manipulation checks — measure heuristic susceptibility in laboratory conditions across generic populations. They were not designed to capture the decision-making ecology specific to judicial work: the interaction between legal reasoning, evidentiary evaluation, procedural constraints, and the professional culture of adjudication. A judge deciding bail under time pressure in an adversarial hearing operates in a different cognitive environment from a psychology undergraduate completing a survey. Instruments validated on the latter do not automatically transfer to the former. The gap in judicial debiasing psychometric assessment is not merely administrative — it is methodological.

    J-HAQ four-factor structure showing availability confirmation bias representativeness and anchoring

    The J-HAQ: First Psychometric Assessment Tool for Judges

    Malegiannaki, Chatzopoulos, and Tsagkaridis (2025) addressed this gap directly. Their Judicial Heuristics Awareness Questionnaire was developed and administered to 52 active-duty judges drawn from 54 of 63 First Instance Courts and 11 of 19 Appeal Courts across Greece — a civil law jurisdiction where judges play an active inquisitorial role in evidence gathering and case management.

    The instrument began with 19 items, reduced to 12 through Principal Component Analysis (KMO = 0.77; Bartlett’s χ²(66) = 199.96, p < .001). The final version confirmed a four-factor structure — availability, confirmation bias, representativeness, and anchoring — explaining 67.13% of total variance with an overall Cronbach’s α of 0.82. A five-item Cognitive Reflection Test served as a concurrent validity comparator.

    Three findings carry institutional weight.

    First, the four-factor structure itself. The J-HAQ empirically decomposes “cognitive bias” — a term judicial training programmes typically treat as a monolithic category — into four distinct measurable components. The decomposition has direct design implications: a training programme targeting anchoring requires different pedagogical architecture than one targeting confirmation bias. Generic “bias awareness” sessions conflate mechanisms that operate through different cognitive pathways.

    Second, the two-cluster metacognitive finding. Two-step Cluster Analysis identified a high-awareness group (n=30) and a low-awareness group (n=22). The clusters differed significantly by educational level (t(40.52) = 1.98, p = 0.03) but not by age, gender, or — critically — years of professional experience. Judges in both clusters self-reported relatively low heuristic use overall. The authors’ interpretation: this reflects “metacognitive myopia” rather than genuinely reduced reliance. Judges who cannot detect their own heuristic use will naturally report low use, regardless of actual reliance levels.

    Third, the experience null finding. Years of professional judicial experience showed no statistically significant correlation with either heuristic reliance or metacognitive awareness. This directly contradicts the assumption embedded in most judicial training design — that seniority brings cognitive sophistication and that debiasing resources should be concentrated on newer judges. The J-HAQ data point in the opposite direction: metacognitive assessment should apply equally across career stages.

    Limitations of the J-HAQ and What Remains Untested

    The instrument’s limitations are substantial. They must be stated plainly. The sample of 52 judges falls below the authors’ own recommended minimum of 67 for adequate statistical power. The study draws from a single jurisdiction — Greece — with a civil law inquisitorial tradition that differs structurally from common law adversarial systems where oral cross-examination, party-led evidence presentation, and adversarial challenge provide external debiasing pressures absent in civil law proceedings.

    The exclusive reliance on self-report creates an interpretive ambiguity the instrument cannot internally resolve. Low self-reported heuristic use could indicate genuine low reliance — consistent with Gigerenzer’s ecological rationality framework, which holds that heuristics are adaptive tools calibrated to environmental structure rather than systematic errors. Under high-caseload conditions, fast heuristic processing may represent efficient decision-making rather than cognitive failure. The J-HAQ study acknowledges this theoretical tension without resolving it.

    No concurrent behavioural outcome measure was administered. The instrument cannot tell us whether a judge who scores high on the confirmation bias factor actually produces more biased decisions — or whether metacognitive cluster membership predicts reversal rates, sentencing variance, or other measurable performance indicators. That validation step remains entirely untested.

    Replication is absent. The factor structure, cluster distribution, and the experience null finding remain specific to one Greek sample until independent work confirms generalisability.

    judicial debiasing psychometric assessment

    Two Decades of Convergent Evidence on Judicial Cognitive Bias

    The J-HAQ did not emerge in an empirical vacuum. It sits within a body of research that has documented judicial heuristic susceptibility through different methodological lenses since the early 2000s.

    Guthrie, Rachlinski, and Wistrich’s foundational 2001 study used experimental vignettes with 167 US federal magistrate judges and found statistically significant effects for all five tested cognitive illusions. Judges were marginally less susceptible to framing effects and representativeness than lay populations, but the core finding — that legal training and judicial experience do not eliminate systematic heuristic reliance — has been replicated and extended by the same research team in subsequent work.

    Englich, Mussweiler, and Strack (2006) demonstrated that experienced German legal professionals, including judges, were significantly influenced by irrelevant numerical anchors in sentencing scenarios — even when participants were aware of the anchor’s irrelevance. The anchoring effect persisted despite expertise, awareness, and high motivation for accuracy.

    Citation reflects reported judicial practice. Verify with primary case law databases for specific authority.

    Qualitative evidence from a non-Western jurisdiction tells a consistent story. Semi-structured interviews with retired judges and senior advocates in Pakistan (ASSA Journal, 2025) documented confirmation bias in precedent interpretation and anchoring bias in sentencing. Sociocultural and moral frameworks were found to interact with cognitive shortcuts in ways the Western experimental literature has not examined. The study recommended embedding psychological literacy in judicial education but applied no standardised measurement instrument.

    What these studies share — across experimental vignettes, psychometric self-report, and qualitative interview; across the United States, Germany, Greece, and Pakistan; across common law and civil law traditions — is a convergent conclusion: legal training does not eliminate heuristic reliance, professional experience does not reduce it, and judges themselves frequently cannot detect when they are relying on cognitive shortcuts rather than deliberative legal reasoning. The structural failure of mixed court deliberation documented in lay-professional judge interactions illustrates the same metacognitive blind spot in a different institutional setting.

    The Ecological Rationality Counterargument

    Intellectual honesty requires confronting the strongest objection to the bias-as-error framing that underpins most judicial debiasing programmes.

    Gigerenzer’s adaptive toolbox model holds that heuristics are not systematic cognitive failures but ecologically rational tools — fast, efficient decision strategies calibrated to the structure of the environment in which they are deployed. Under this model, a judge who relies on availability heuristics in a high-volume docket is not necessarily committing a cognitive error. The judge may be making decisions that are “good enough” for the decision context, conserving cognitive resources for cases that genuinely demand deliberative processing.

    This is not a fringe position. It represents a major theoretical divide in cognitive science — one that the empirical literature on judicial decision-making has not resolved. The J-HAQ study explicitly acknowledges the tension: its data are consistent with both the metacognitive myopia interpretation (judges do not detect their own bias) and the ecological rationality interpretation (judges genuinely do not rely heavily on heuristics because their professional environment selects for deliberative processing).

    The resolution matters for intervention design. If heuristic reliance is pathological, training should aim to reduce it. If heuristic reliance is adaptive, training should aim to improve metacognitive calibration — helping judges recognise when heuristic processing is appropriate and when it is not — rather than treating all heuristic use as error.

    No existing judicial training programme engages with this distinction. Debiasing curricula uniformly assume the bias-as-error model without testing whether that assumption applies to the specific population being trained.

    The Comparative Judicial Training Landscape

    Judicial academies across different legal traditions include cognitive bias content in their curricula. None in the documented record use validated psychometric baseline assessment.

    The École Nationale de la Magistrature (ENM) in France — the principal training institution for the French judiciary — incorporates neuroscience and cognitive bias content into at least some programmes. Documentation from a 2022 co-design project with the user-centred design firm Amurabi confirms integration of cognitive bias modules into non-professional judge training. No ENM documentation references a validated psychometric instrument for pre- or post-training assessment of heuristic reliance.

    The UNODC Judicial Conduct and Ethics framework — the principal international training package implementing the Bangalore Principles — lists “awareness of a range of cognitive biases” and “reflective skills to counter these biases” among its stated learning outcomes. It specifies no measurement instrument, no baseline assessment protocol, and no outcome evaluation methodology.

    The Australian Law Reform Commission’s Background Paper JI6 (2021) represents the most thorough institutional review of the evidence base. It synthesises international empirical literature and recommends both structural procedural reforms — such as separating bail and trial judges to reduce confirmation bias — and integration of cognitive psychology into judicial education. It does not recommend psychometric baseline assessment. It pre-dates the J-HAQ by four years.

    Notably absent from the documented record: curriculum-level details for the Deutsche Richterakademie (Germany), the Judicial College (England and Wales), the Federal Judicial Center (United States), and the National Judicial Institute (Canada). Whether these institutions use any form of psychometric baseline assessment cannot be confirmed from available evidence. The gap in comparative data is itself telling — if leading judicial training institutions were conducting validated pre/post cognitive assessment, the practice would likely appear in published evaluations or institutional reports. The pattern mirrors the broader judicial reform mandates that fail at implementation — where design intent does not survive institutional execution.

    The Normative Gap: Bangalore Principles and Cognitive Competence

    The Bangalore Principles of Judicial Conduct (2002) — the nearest thing to a universal normative standard for judicial behaviour — address competence through Value 6: judges must “maintain and enhance” the knowledge, skills, and personal qualities necessary for proper judicial performance.

    Value 6 is oriented toward legal knowledge and professional diligence. It does not address psychometric assessment of cognitive competence, heuristic reliance measurement, metacognitive training design, or validated instrument deployment as a condition of programme design or evaluation.

    The gap between “impartiality” as an ethical aspiration (Value 2) and “confirmation bias” as a measurable cognitive mechanism is not bridged in the text, its commentary, or any known implementing guidance. The Principles assume that judicial commitment to impartiality — expressed through ethical conduct, absence of prejudice, and procedural fairness — translates into cognitive impartiality. The empirical record documented above suggests that assumption is unsupported. Where judicial integrity systems fail by design, the failure extends to the cognitive dimension — accountability frameworks that do not measure cognitive performance cannot assure it.

    No judicial council in the documented record has interpreted Value 6 to require validated cognitive baseline assessment as part of continuing judicial education. The instrument to enable such assessment now exists. The normative mandate for its use does not.

    What Measurement-Before-Intervention Design Would Require

    If a judicial training institution adopted the J-HAQ or a successor instrument as a baseline assessment tool, the training design cycle would change in three concrete ways.

    First, training needs analysis would become empirically grounded rather than assumption-driven. Instead of designing a generic “cognitive bias awareness” module, an academy could identify which heuristics dominate in its specific judicial population — and whether that population splits into metacognitive clusters requiring differentiated pedagogical approaches.

    Second, training evaluation would acquire a measurable endpoint. Pre/post J-HAQ administration would allow assessment of whether the intervention shifted self-reported heuristic awareness — and, with concurrent behavioural measures added, whether awareness change correlated with decision quality change. No judicial training programme currently publishes outcome data on heuristic reliance as a primary metric.

    Third, resource allocation would become defensible. Judicial training budgets are finite. An institution that can demonstrate measured change in the target variable can justify continued investment. An institution that cannot is funding professional comfort rather than cognitive performance improvement.

    Institutional Implications

    1. Baseline assessment mandate. Judicial academies and judicial councils should require validated psychometric baseline assessment of heuristic reliance before designing or procuring debiasing training programmes. The J-HAQ provides a starting instrument; cross-jurisdictional replication should be commissioned as a priority.
    2. Differentiated training design. The J-HAQ’s four-factor structure and two-cluster metacognitive finding indicate that generic “bias awareness” training conflates distinct cognitive mechanisms. Training architecture should differentiate between confirmation bias, anchoring, availability, and representativeness — and between judges who demonstrate metacognitive awareness and those who do not.
    3. Outcome measurement infrastructure. Judicial training effectiveness should be evaluated against measured cognitive and behavioural outcomes, not against participant satisfaction surveys or attendance metrics. Pre/post psychometric assessment should become a standard component of programme evaluation.
    4. Normative framework revision. The Bangalore Principles’ silence on cognitive competence assessment represents an outdated conception of judicial competence that predates the empirical evidence base. Implementing bodies should consider whether Value 6 guidance requires supplementation to address validated cognitive performance measurement.
    5. Cross-jurisdictional replication priority. The J-HAQ’s construct validity for common law adversarial systems remains untested. Judicial training institutions in common law jurisdictions — particularly those with established continuing judicial education infrastructure — should commission replication studies before adopting or dismissing the instrument’s findings.

    About VeritasJPS

    VeritasJPS provides evidence-based research and advisory at the intersection of jurisprudence, cognitive science, and institutional governance. Our work supports institutional decision-makers — judges, policymakers, and compliance leaders — with rigorous analysis grounded in empirical evidence and legal scholarship.

    Learn more: [website URL]

  • Partisan Motivated Reasoning and the Limits of Judicial Legitimacy Reform

    Partisan Motivated Reasoning and the Limits of Judicial Legitimacy Reform

    Institutional reform discourse treats judicial legitimacy as a function of procedural quality — transparency, enhanced reasoning, appointment diversity, open hearings. Recent evidence from political psychology and judicial legitimacy research challenges this assumption at its cognitive foundation. Studies across multiple democratic jurisdictions (2023–2026) document that partisan identity governs how citizens process court decisions, producing asymmetric trust updating where identical judicial outputs generate opposite legitimacy signals depending on prior political alignment. This analysis examines the empirical evidence for motivated reasoning as the primary input-processing mechanism in judicial trust formation, evaluates the gap between international independence frameworks and cognitive reception architecture, and considers what non-procedural institutional levers — particularly legitimacy communication design — might credibly shift trust perceptions when procedural inputs are cognitively rerouted by partisan identity. The findings carry direct implications for judicial councils, court leadership, and policymakers who allocate reform resources on the assumption that better procedure yields higher trust.

    The Procedural Assumption and Its Cognitive Blind Spot

    Partisan motivated reasoning has reframed what was once a settled premise in judicial legitimacy reform: that if courts demonstrate fairness through transparent reasoning, neutral treatment, respectful process, and visible independence safeguards, citizens will recognise those inputs and update trust accordingly. The logic runs from institutional behaviour to public perception in a relatively direct line. Improve the signal, and the receiver adjusts.

    This premise has shaped everything from judicial training curricula to court administration strategy. The UN Basic Principles on the Independence of the Judiciary (1985) and the Bangalore Principles of Judicial Conduct (2002) articulate structural guarantees — security of tenure, adequate remuneration, transparent appointment, behavioural standards of impartiality — that courts worldwide have adopted as the architecture of independence. The unstated assumption is that visible compliance with these structural conditions will be read at face value as evidence of genuine independence.

    Chart showing asymmetric trust updating in judicial legitimacy studies 2023–2026

    Partisan Motivated Reasoning and Judicial Legitimacy

    The cognitive science of the last decade exposes a specific flaw in that logic. It presumes a quasi-rational evaluator who processes institutional cues and updates beliefs accordingly. The motivated reasoning literature documents something different: citizens in partisan environments first route judicial outputs through identity-protective cognition — classifying decisions as favourable or threatening to their political group — and only then generate attributions of fairness or bias. The procedural inputs are not ignored. They are reinterpreted after partisan filtering has already set the evaluative direction.

    This distinction changes the entire reform calculus. If procedure is upstream of trust, then procedural improvements are the right investment. If partisan cognition is upstream of procedural evaluation, then procedural reforms are operating on a variable that has already been processed and relabelled before it reaches the citizen’s legitimacy judgment.

    Asymmetric Trust Updating: Evidence Across Jurisdictions

    The empirical case for motivated reasoning in judicial trust has strengthened substantially between 2023 and 2026, with convergent findings across different democratic systems and research designs.

    A 2025 study published in the British Journal of Political Science examined citizen reactions to judicial checks on incumbent governments. The experimental design exposed respondents to identical descriptions of courts ruling against the government. The central finding was directionally split: government supporters decreased their trust in the judiciary following the ruling, while opposition supporters increased theirs. Same institutional act. Opposite trust trajectories. The procedural characteristics of the decision were held constant. What varied was the partisan lens through which the output was processed.

    This pattern is not confined to a single jurisdiction. Gadarian et al. (2023), writing in the Proceedings of the National Academy of Sciences, documented a parallel mechanism at the U.S. Supreme Court. Their experimental and observational data showed that respondents attributed decisions they agreed with to the Court’s legal character and principled reasoning, while attributing decisions they opposed to political motivation. The institutional process was identical — the same Court, the same procedural posture, the same constitutional framework. But citizens cognitively split that single process into “law” when outcomes aligned with their preferences and “politics” when outcomes contradicted them. The Court’s hybrid legal-political character enabled this by providing two available interpretive frames that respondents selected based on policy agreement rather than procedural observation.

    partisan motivated reasoning judicial legitimacy

    The geographic scope extends to European constitutional courts. A 2025 experiment published in the Journal of Law and Courts tested partisan, procedural, and populist frames on perceptions of the Czech Constitutional Court. Frames emphasising which political actors had appointed the judges, or portraying the court as an unelected elite overriding democratic will, significantly reduced perceived fairness and legitimacy. Legalistic and procedural frames had more limited or contingent positive effects. The identity cue — who owns this court — dominated the procedural cue — how this court operates. Comparable findings were reported by Magalhães et al. (2023) in experiments involving courts in Norway and Portugal, where signalling partisan appointment reduced fairness perceptions relative to neutral legalistic descriptions.

    Motivated reasoning also operates within the judiciary itself. Lu (2025), analysing over a century of U.S. Circuit Court opinions in PLOS ONE, found that judicial writing styles and citation patterns were predictive of judges’ political affiliations. While this study addresses judicial behaviour rather than public trust, it identifies a potential feedback loop: if judicial outputs carry detectable partisan signals in their reasoning patterns, those signals provide raw material for motivated reasoning among the public, reinforcing the identity-based interpretive cycle.

    The Procedural Fairness Counterpoint — and Its Limits

    The motivated reasoning evidence does not eliminate procedural fairness as a variable in legitimacy formation. It repositions it.

    A 2026 study accessible through Cambridge Core tested whether reasoning styles in judicial opinions — specifically the incorporation of procedural fairness elements such as clear explanation and acknowledgement of competing arguments — could improve perceived legitimacy independently of outcome agreement. The findings suggest they can, at least under some conditions. Reasoning quality retains an independent effect on fairness perceptions.

    Two qualifications constrain this finding. First, the study does not fully map the interaction between procedural fairness and strong partisan identity. It remains unclear whether procedural improvements retain their positive effect when partisan stakes are high and elite cues are actively framing the court as a partisan actor. The motivated reasoning studies suggest that under those conditions, procedural signals become secondary — absorbed or overridden by identity-driven processing.

    Second, ecological validity. Most motivated reasoning experiments use stylised vignettes with high-salience, politically charged cases — the conditions where partisan cognition is strongest. Real-world judicial legitimacy includes routine, low-salience decisions where partisan identity may be less activated and procedural quality may exert greater independent influence. But legitimacy crises do not emerge from routine cases. They emerge from exactly the high-stakes, politically polarised decisions where motivated reasoning is most operative.

    The pragmatic implication: procedural reform and motivated reasoning operate on different legitimacy registers. Procedural improvements may contribute to a baseline reservoir of institutional goodwill that cushions courts during low-salience periods. When legitimacy is contested — when political actors frame courts as captured, biased, or illegitimate — procedural quality alone appears insufficient to counteract identity-driven reinterpretation.

    Citation reflects reported judicial practice. Verify with primary case law databases for specific authority.

    International Frameworks and the Cognitive Architecture Gap

    The mismatch between the reform paradigm and cognitive reality is mirrored at the level of international standards. The UN Basic Principles specify structural conditions for independence: security of tenure, adequate remuneration, freedom from inappropriate interference, transparent appointment. The Bangalore Principles add behavioural requirements: integrity, impartiality, propriety, equality, competence, diligence.

    Both instruments are designed to ensure that courts actually behave independently. Neither addresses the question of whether citizens are cognitively equipped to perceive that independence accurately when partisan identity provides an alternative interpretive frame. The assumption is that structural independence, if visibly maintained, will be read as independence. The motivated reasoning evidence suggests that this assumption fails precisely when it matters most — in polarised environments where political actors actively contest the meaning of judicial decisions.

    The practical consequences are measurable. Judicial integrity systems that fail by design illustrate this supply-side limitation clearly: judicial councils and court leadership bodies worldwide invest in appointment transparency, diversity initiatives, enhanced reasoning, and public communication on the assumption that these measures will build legitimacy. If motivated reasoning intercepts these signals — reinterpreting transparency as a screen for partisan capture, diversity as political tokenism, enhanced reasoning as sophisticated rationalisation of predetermined outcomes — then the reform investment produces no return on the trust variable it targets.

    This is not a marginal gap. International and domestic judicial independence frameworks address the supply side of legitimacy (structural conditions) but leave the demand side (cognitive reception) entirely unspecified. Legitimacy communication design — how courts control the interpretive frame through which their decisions are processed — exists in no international standard, no model judicial training curriculum, and no court administration guideline that the current evidence base identifies. Judicial reform mandates that rely exclusively on structural compliance face the same cognitive reception failure at the implementation stage.

    Non-Procedural Levers for Judicial Legitimacy

    If procedural reform operates on the wrong variable in partisan contexts, the institutional question becomes: what operates on the right one?

    The research base does not yet provide a validated playbook. But several directions emerge from the evidence structure.

    Institutional Identity Framing

    The Czech framing study demonstrates that the interpretive frame applied to courts substantially affects legitimacy perceptions. Partisan and populist frames depress trust; legalistic frames partially protect it. Courts may need to actively maintain a legalistic frame for their work through their own communication — not through political intermediaries. The current default, in which courts produce decisions and leave interpretation to media, politicians, and social platforms, surrenders the interpretive frame to actors with motivated reasoning incentives.

    Insulated Legitimacy Communication Channels

    If partisan elites recode judicial independence as partisan alignment, courts need communication infrastructure that bypasses elite intermediation. Judicial councils, court press offices, and judicial education bodies are potential vehicles — but only if they operate with genuine editorial independence from the political actors whose framing drives motivated reasoning. Many judicial communication bodies are themselves politically appointed or resourced. That is the transmission problem.

    Counter-Attitudinal Credibility Design

    The motivated reasoning literature outside judicial contexts identifies conditions under which counter-attitudinal information can update beliefs: source credibility that crosses partisan lines, unexpected messengers who share the audience’s identity but challenge its conclusion, and institutional framing that separates the decision from the partisan contest. Translating these findings into judicial communication design is speculative but directionally promising.

    Legitimacy Reservoir Investment

    If procedural reforms build a baseline reservoir of goodwill during low-salience periods — even if they cannot counteract motivated reasoning during high-salience crises — then the argument for continued procedural investment is not that it drives trust directly, but that it builds the cushion that absorbs partisan shocks. The institutional design question becomes one of portfolio allocation: how much to invest in procedural improvement (baseline resilience) versus legitimacy communication (crisis resistance).

    Institutional Implications

    The convergent evidence on partisan motivated reasoning in judicial trust evaluation produces several direct implications for institutional decision-makers.

    Reform resource allocation requires recalibration. Judicial councils that invest exclusively in procedural improvement — transparency, reasoning quality, appointment diversity — are addressing a variable that motivated reasoning intercepts before it reaches legitimacy evaluation. Procedural reform is not worthless. It is insufficient. Legitimacy communication design deserves dedicated budget, staffing, and strategic attention alongside procedural improvement.

    The governance vacuum around judicial legitimacy communication demands institutional attention. If neither the UN Basic Principles nor the Bangalore Principles address how citizens cognitively process independence signals, and if political actors fill that vacuum with partisan framing, then courts are structurally exposed to legitimacy erosion that no procedural reform can remedy. Closing that gap requires new institutional infrastructure — expanded mandates for judicial councils, dedicated legitimacy communication units, or international standard-setting that extends independence frameworks to include cognitive reception. The problem is not isolated: constitutional redesign as a mechanism for judicial delegitimization demonstrates how structural vulnerability enables politically motivated erosion when no cognitive-reception framework exists to defend institutional credibility.

    The ecological validity gap in the evidence base requires its own institutional investment. Most motivated reasoning findings come from experimental vignettes with high-salience cases. Courts need longitudinal data tracking how real populations update trust across sequences of favourable and unfavourable decisions in real political environments. Without that data, the evidence base tells us what happens in controlled conditions but not how durable or modifiable these effects are in the field. AI judicial oversight introduces a further layer of legitimacy risk in this gap — algorithmic decision-making tools deployed before governance frameworks can frame their outputs are especially vulnerable to partisan motivated reasoning.

    Judicial training curricula need to incorporate the cognitive science of legitimacy perception. Judges who understand that their decisions will be processed through identity-protective cognition — regardless of reasoning quality — are better positioned to design communications that anticipate and partially mitigate that processing. This is not about judges becoming political communicators. It is about judges understanding the cognitive environment in which their work is received.

    The uncomfortable conclusion is that courts cannot earn trust solely by being trustworthy. In a partisan information environment, trustworthiness is necessary but not sufficient. The gap between institutional behaviour and public perception is filled by cognitive architecture that courts did not design and do not address. Closing that gap is not a communication problem to be delegated to a press office. It is a governance architecture problem that belongs on the agenda of every judicial council, court president, and justice ministry that claims to take institutional legitimacy seriously.


    About VeritasJPS

    VeritasJPS provides evidence-based research and advisory at the intersection of jurisprudence, political psychology, and institutional governance. Our work supports institutional decision-makers — judges, policymakers, and compliance leaders — with rigorous analysis grounded in empirical evidence and legal scholarship.

  • Physical Infrastructure Failure as Structural Denial of Access to Justice for Persons with Disabilities

    Physical Infrastructure Failure as Structural Denial of Access to Justice for Persons with Disabilities


    Abstract

    Court accessibility failures represent the most fundamental barrier to justice for persons with disabilities — exclusion that begins not with legal frameworks but with physical infrastructure. The Convention on the Rights of Persons with Disabilities obligates states to ensure effective access to justice for persons with disabilities. Across jurisdictions — Nepal, India, Ireland, Canada — the same structural sequence repeats: CRPD ratification, domestic disability legislation, and then no binding independent audit of whether justice facilities are physically accessible. The result is that compliance remains unverifiable. This analysis examines six jurisdictions and institutional mechanisms to argue that CRPD Article 13, read with Article 9 and General Comment No. 2, creates a justiciable infrastructure obligation that states routinely acknowledge but structurally refuse to enforce. The gap is not between rights and resources. It is between rights and audit.

    The Problem That Precedes All Other Problems

    Disability and access to justice disability scholarship concentrates on procedural accommodation: sign language interpretation, accessible document formats, modified hearing procedures. These matter. But they share a common precondition that receives far less attention: the person with a disability must be able to enter the building.

    A wheelchair user who cannot reach a district court hearing room has no use for procedural accommodation rules. A person with a mobility impairment who cannot access a police station’s complaint registration desk cannot benefit from improved FIR procedures. Physical infrastructure is the precondition for every procedural right that follows.

    The Nepal National Human Rights Commission and National Federation of the Disabled-Nepal (2022/2025) study across all seven provinces documented this directly. Courtrooms lacked ramps and elevators. A woman using a wheelchair missed multiple district court hearings because the court building offered no wheelchair access. A deaf woman could not file a First Information Report at a police station — not because the law excluded her, but because the building’s design did. Province-level recommendations — install ramps, mandate accessibility in infrastructure budgets, conduct disability inclusion audits — confirm that these were not isolated maintenance failures. They were design defaults.

    CRPD Article 13 and the Physical Infrastructure Obligation

    CRPD Article 13 requires states to “ensure effective access to justice for persons with disabilities on an equal basis with others, including through the provision of procedural and age-appropriate accommodations.” The text names procedural accommodation explicitly. It does not prescribe minimum physical infrastructure standards for justice facilities, and it does not mandate periodic independent facility audits.

    The CRPD Committee, through Concluding Observations compiled by the International Disability Alliance (April 2025 edition), has extended the obligation. States have been directed to eliminate physical and attitudinal barriers to all justice facilities, ensure physical accessibility of court buildings through universal design, and adopt action plans for physical access including accessible transportation. These are not suggestions. They are treaty body directives to signatory states.

    Here is the structural gap. Article 13 names procedural accommodation. Physical infrastructure accessibility derives from Article 9’s general accessibility obligation as applied to justice facilities. The Committee treats the two obligations as complementary. States exploit the interpretive space between them — prioritising procedural accommodations (cheaper, more visible, easier to report on) over capital infrastructure investment (which requires budgetary commitment across building cycles).

    Article 9’s General Comment No. 2 (2014) calls for states to establish “a monitoring, reporting and evaluation system” covering National Accessibility Standards, with “redress and sanctions for non-compliance.” This is the strongest formal hook for an independent audit argument in the treaty architecture. It does not specify that the monitoring body must be independent of the state. No jurisdiction identified in this analysis has implemented it as a third-party audit mechanism covering justice facilities.

    Disability Access to Justice Across Five Jurisdictions

    The structural sequence is consistent across the jurisdictions examined.

    Map comparing court accessibility audit gaps across six jurisdictions

    Nepal

    Nepal ratified the CRPD in 2010. The NHRC/NFDN study (2022, reported 2025) found systemic physical inaccessibility across police stations, courtrooms, and detention facilities in all seven provinces. Province-specific recommendations included installing ramps and tactile guiding paths (Lumbini Province), mandating accessibility in infrastructure budgets (Karnali Province), and conducting disability inclusion audits in courts (Gandaki Province). The NHRC’s Sixth Strategic Plan (2021–2026) now prioritises access to justice for persons with disabilities. No independent audit mechanism has been established.

    India

    India presents a striking case. The Supreme Court of India itself constituted an Accessibility Committee in December 2023, chaired by Justice S. Ravindra Bhat, which audited the Court’s own premises. The committee found an absence of wheelchair-friendly amenities, inadequate tactile flooring, and insufficient designated seating for persons with disabilities. India’s apex court formally recognised it did not meet basic physical accessibility standards. A November 2024 court order directed the Central Government to frame mandatory accessibility rules under the Rights of Persons with Disabilities Act 2016 (RPWD Act), Section 40, within three months. Citation reflects reported judicial practice. Verify with primary case law databases for specific authority. Whether those rules have been formally notified as of early 2026 is not confirmed in available public records. The Supreme Court audit was internal — not an independent third-party review. Approximately 25,000 district and subordinate courts across India were not covered.

    Ireland

    Ireland, a common law jurisdiction that ratified the CRPD in 2018, produced a direct assessment. The Irish Human Rights and Equality Commission (IHREC, November 2024) recommended that accessibility reform “be informed by an end to end accessibility audit” implemented with “a publicly reported, timetabled and resourced plan.” The core finding was the absence of an audit mechanism — the audit gap itself was the structural finding. Ireland’s independent monitoring body for the CRPD recommended an audit. It did not have one.

    Canada

    Canada represents the most institutionally developed self-reporting mechanism found. The Courts Administration Service (CAS, 2025) began systematic facility inspection under the Accessible Canada Act (S.C. 2019, c. 10). The Act mandates published accessibility plans, progress reports, and a complaints route through the Accessibility Commissioner. The CAS can identify non-compliance without being able to fix it — Public Services and Procurement Canada (PSPC) is “ultimately responsible for implementing corrective actions.” That split between identifier and implementer is itself an accountability gap. Plans are self-reported, not independently audited. No compliance rate for identified physical items is publicly available. Federal courts represent a fraction of justice proceedings; provincial and territorial courts — where most criminal and civil disability-related matters are heard — operate under separate frameworks.

    Wheelchair user facing courthouse steps without ramp access

    Infrastructure Barriers as Gendered Denial of Justice

    The UN Secretary-General’s report to the Commission on the Status of Women (March 2026), prepared for CSW70, identifies physical infrastructure barriers at police stations, courts, jails, prisons, and government buildings as a specific access barrier for women and girls with disabilities. Organisations referencing the report cite concrete implementation measures: lifts, ramps, and sign language interpretation at justice facilities.

    The report situates infrastructure inaccessibility within a finding that women hold 64% of the legal rights of men globally. Physical barriers compound that inequality — a woman with a disability faces both the legal rights deficit and the infrastructure exclusion. In crisis zones, the report identifies infrastructure collapse as a distinct denial mechanism separate from legal framework gaps.

    This has doctrinal consequences. The International Review of the Red Cross (June 2025) argues that failure to eliminate physical and attitudinal barriers post-armed conflict potentially engages ICC jurisdiction over crimes against women and girls with disabilities. The argument is doctrinal — not yet confirmed by case law — but it reframes infrastructure failure. Not an administrative shortcoming. A violation with jurisdictional consequences.

    The Accessibility Audit Gap: Why Compliance Is Unverifiable

    A peer-reviewed analysis published in PMC (October 2025) examining Article 13 operationalisation confirms that reasonable accommodation obligations apply to access to justice even though Article 13 does not explicitly mention them. The study identifies access to justice as a determinant of the realisation of all other rights — health, employment, education. Physical facility accessibility is implied by Article 13’s equal-basis obligation.

    Implying an obligation and enforcing it are different acts. Across every jurisdiction examined, the same enforcement architecture is missing:

    No state has implemented a binding, periodic, independent third-party audit of physical accessibility across courts, police stations, and detention facilities with published compliance rates. Canada comes closest with statutory self-reporting, but self-reporting without independent verification and without published compliance rates does not constitute an audit. India’s Supreme Court conducted an internal review — of one facility. Ireland’s independent monitoring body recommended an audit that does not exist. Nepal’s NHRC documented the problem across seven provinces but has no audit mandate. The CRPD Committee directs states to establish monitoring systems but does not specify independence from the state.

    The pattern is consistent: states acknowledge the obligation, produce reports, and sometimes even document non-compliance — but the mechanism that would make court accessibility verifiable and enforceable does not exist.

    Independent periodic audit with published results and sanctions for non-compliance. That is the missing architecture.

    What Remains Unmeasured

    One gap runs through the entire evidence base. No peer-reviewed study found in this analysis has measured the causal relationship between physical facility inaccessibility and case attrition or withdrawal rates for disabled litigants. The Nepal study documents a woman who missed multiple hearings. No jurisdiction systematically tracks how many cases are abandoned, delayed, or never filed because the person could not physically access the facility.

    Without that data, the scale of exclusion stays invisible. Physical infrastructure failure does not produce visible denials of justice — it produces invisible ones. Cases never filed do not appear in court statistics. Hearings missed due to building inaccessibility are recorded as non-attendance, not as infrastructure failure. The measurement gap protects the status quo.

    Institutional Implications

    Three conclusions follow.

    First, CRPD Article 13, read with Article 9 and General Comment No. 2, creates a justiciable obligation for physical infrastructure accessibility at justice facilities. The Committee’s Concluding Observations — directing states to eliminate physical barriers, ensure universal design, and adopt resourced action plans — are specific enough to ground domestic legal challenges. The obligation exists. The enforcement mechanism does not.

    Second, the gap between obligation and enforcement is a design choice, not a resource constraint. States that can build courthouses can build accessible courthouses. The absence of independent audit reflects a governance decision to leave compliance to political discretion rather than subject it to verifiable, periodic, independent review with published results.

    Third, measuring case attrition linked to facility inaccessibility should be a research and policy priority. Until jurisdictions track cases lost to infrastructure failure — not just cases heard despite it — the full scale of exclusion will remain undocumented.

    The right to access justice means nothing if you cannot enter the building where justice is administered. That is not a metaphor. It is a measurable infrastructure condition. No jurisdiction currently measures it.


    About VeritasJPS

    VeritasJPS provides evidence-based research and advisory at the intersection of access-to-justice policy, disability rights law, and institutional governance design. Our work supports institutional decision-makers — judges, policymakers, and compliance leaders — with rigorous analysis grounded in empirical evidence and legal scholarship.

    Learn more:

  • Before the Audit: How Pre-Oversight AI Deployment Undermines Judicial Legitimacy

    Before the Audit: How Pre-Oversight AI Deployment Undermines Judicial Legitimacy


    Abstract

    Judicial systems across multiple jurisdictions are deploying AI in decision-support functions before external oversight architecture exists to detect or challenge errors. The structural consequence is not hallucination risk or explicit bias — both of which receive adequate attention — but the normalization of opacity in judicial reasoning before any accountability mechanism is operational. This analysis maps the AI judicial oversight vacuum across the EU AI Act’s classification-without-competency gap, Pakistan’s Supreme Court directive that remains without implementing guidelines, Canadian courts sanctioning AI-fabricated citations, and the Stimson Center’s identification of four bias vectors in Global Majority judicial systems. The evidence converges on a single structural failure pattern: deployment speed consistently outpaces oversight readiness, and the resulting legitimacy erosion compounds before institutions recognize the deficit. A minimum AI governance readiness standard — established at the international level before further operationalization — is not a regulatory luxury. It is a prerequisite for maintaining the institutional authority on which judicial legitimacy depends.

    The Structural Problem: AI Deployment Without Oversight Detection

    The dominant framing of AI risk in judicial settings focuses on two failure modes: hallucination (AI fabricating legal authorities) and explicit bias (algorithmic outputs that discriminate along racial or socioeconomic lines). Both are real. Neither captures the deeper structural problem.

    The structural legitimacy risk operates at a different level. When an AI system enters a judicial decision-support function — case scheduling, risk assessment, legal research assistance, sentencing recommendation — without external audit requirements, the system’s reasoning becomes embedded in institutional practice before anyone outside the deploying body can examine how it works. Opacity becomes the default. And defaults, once institutionalized, resist reversal. The absence of AI judicial oversight at the point of deployment is the root structural failure.

    The Stimson Center’s January 2026 report identifies four distinct bias vectors in judicial AI deployment across Global Majority systems: data bias (training data that reflects existing disadvantage), coding bias (programmer assumptions embedded in legal logic translation), intentional misuse (political exploitation of AI’s apparent neutrality in weak judicial systems), and human-AI interaction bias (judges either over-relying on or superficially dismissing AI outputs). The report concludes that opaque AI tools generate an accountability deficit producing what it terms “obscure justice.” Each vector is individually addressable — but only if an external audit mechanism exists at the point of deployment. Without one, the vectors compound undetected.

    The Hallucination Cases: Demand-Side Evidence of Systemic Fragility

    Canada’s courts produced three separate sanctions for AI-fabricated legal citations in 2025, each escalating in severity.

    In Ko v Li, 2025 ONSC 2766, the Ontario Superior Court addressed a lawyer who submitted non-existent cases generated by AI. Justice Meyers noted that the legal community had been explicitly warned since 2023 that AI-generated content requires verification — the failure was not technological ignorance but institutional discipline breakdown. In October 2025, a Quebec court imposed a C$5,000 sanction on a self-represented litigant who submitted eight fictitious case citations. By December, the Alberta Court of Appeal levied $500 in costs against a litigant for three fabricated authorities, with an explicit warning that future violations would attract substantially greater penalties.

    These are demand-side failures — lawyers and litigants misusing AI tools, not courts deploying them. But they expose the same structural vulnerability. The fabricated authority entered the judicial record each time through a channel that lacked any automated verification gate. The court detected the error only through traditional human review. Scale that detection requirement across hundreds of thousands of filings per year, and the governance gap becomes quantifiable: human review cannot catch what automated systems generate at volume without institutional infrastructure built for the task.

    Timeline comparing AI judicial oversight frameworks across EU, Pakistan, Canada, and Singapore

    Pakistan’s “Calibrated Integration”: AI Judicial Oversight Without Architecture

    In April 2025, Pakistan’s Supreme Court issued an 18-page ruling addressing AI use in the judiciary. Led by Justice Syed Mansoor Ali Shah, the two-judge bench articulated a “calibrated integration” standard: AI functions as a facilitative tool only, never replacing human judicial autonomy or constitutional fidelity under Articles 10A and 37(d) (the rights to fair trial and speedy justice).

    The ruling directed the National Judicial (Policy Making) Committee and the Law and Justice Commission of Pakistan to jointly develop guidelines delineating clear boundaries for permissible AI uses in courts. The diagnosis was precise. The institutional follow-through has been absent.

    As of early 2026, available records contain no published guidelines from either body. The ruling identifies the governance gap without closing it. “Calibrated integration” remains a standard without operational definition — a judicial instruction that AI deployment should be careful, issued to institutions that have not yet built the infrastructure to determine what “careful” means in practice.

    Citation reflects reported judicial practice. Verify with primary case law databases for specific authority.

    This pattern — a senior court articulating the principle while the implementing bodies lack the capacity or mandate to operationalize it — is not unique to Pakistan. It is the structural failure mode that pre-oversight deployment produces. The diagnosis exists. The institutional machinery to act on it does not.

    The EU AI Act: Classification Without Competency

    The EU AI Act (Regulation 2024/1689) addresses judicial AI directly. Annex III, Category 8(a) classifies AI systems intended for use by courts to research and interpret facts or law, or to apply law to concrete facts, as high-risk. This classification triggers conformity assessment before deployment, risk management systems, technical documentation, transparency obligations, and human oversight requirements. The compliance deadline for Annex III systems is August 2, 2026.

    The classification is correct. The governance infrastructure to support it is incomplete.

    The Act does not prescribe minimum audit competency standards for national judicial bodies. It does not specify what technical expertise, what independence criteria, or what institutional capacity a national court system must possess to commission or validate a conformity assessment for an AI system it intends to deploy. The conformity assessment obligation under Article 43 falls primarily on providers — the companies building the systems — not on the judicial institutions deploying them.

    Article 6(3) compounds the problem. It creates a derogation: a system is not classified as high-risk if it does not “materially influence the outcome of decision making” or performs only a “narrow procedural task.” A provider can claim that a legal research tool merely surfaces information — it does not influence outcomes. Whether that claim is tested depends on whether the deploying institution has the audit capacity to challenge it. Most do not.

    The gap between classification and operational readiness is the EU AI Act’s structural weakness for judicial deployment. The Act tells member states that judicial AI is high-risk. It does not tell judicial institutions how to verify that classification is being properly enforced.

    The Fairness Impossibility: What AI Governance Cannot Solve

    Any governance framework for judicial AI must confront a mathematical constraint that limits what even the best-designed oversight can achieve.

    Chouldechova (2017) demonstrated that when base rates differ across demographic groups — as recidivism rates do across racial groups in every jurisdiction where they have been measured — no algorithm can simultaneously satisfy predictive parity (equal accuracy across groups) and equalized error rates (equal false positive and false negative rates across groups). These fairness criteria are mutually exclusive. The ProPublica analysis of COMPAS — examining over 7,000 defendants in Broward County, Florida — found that Black defendants who did not reoffend were nearly twice as likely as white defendants to be incorrectly classified as high-risk (45% versus 23% false positive rate). Northpointe contested the analysis by arguing that COMPAS satisfies predictive parity. Both findings are independently replicated. The conflict is mathematical, not empirical.

    This matters for the governance argument because it establishes what external audit can and cannot deliver. Pre-deployment oversight can guarantee bias detection and disclosure. It cannot guarantee bias elimination. A governance readiness checklist must therefore include not only audit mechanisms but also disclosure protocols: how will courts inform defendants, litigants, and the public that the system they rely on produces irreducible disparities? No framework currently in operation answers that question.

    Counterpoint: Governance-First Models That Work

    The structural failure pattern is not universal. Several jurisdictions have built governance infrastructure before or alongside deployment.

    The National Center for State Courts published its AI Readiness for State Courts guide in October 2025, convening 16 subject-matter experts to produce a three-level framework: strategic planning (governance committee, guiding principles, data governance), project implementation (stakeholder co-creation, total cost assessment), and continuous adaptation (human oversight, performance monitoring, drift prevention). The framework operationalizes a 12-month governance plan. Its core principle is direct: governance infrastructure must be established before deployment, not retrofitted.

    Singapore’s Ministry of Justice launched a public consultation in September 2025 on a Guide for Using Generative AI in the Legal Sector, mandating a “lawyer in the loop” and verification of all AI output before use. Singapore’s broader public-sector agentic AI framework, analyzed by GovInsider in November 2025, operates from a principle that trust is infrastructure — governance reduces adoption resistance rather than increasing it.

    The CEPEJ 2025 guidelines on generative AI in judicial systems — building on the Council of Europe’s 2018 Ethical Charter — require incremental deployment, pilot phases with evaluation, regular audits, ongoing monitoring, and independent expert certification. These are non-binding recommendations, and compliance tracking is not yet publicly available. But they represent the most detailed international standard for judicial AI governance currently in existence.

    The counterpoint is real but limited. No jurisdiction has published longitudinal data demonstrating that governance-first deployment prevented the legitimacy harm that deployment-first approaches produce. The NCSC framework has not been empirically tested against outcomes. Singapore’s framework is too recent for outcome measurement. The evidence supports the feasibility of pre-deployment governance. It does not yet demonstrate its effectiveness at the institutional trust level.

    Chart illustrating the mathematical impossibility of simultaneous algorithmic fairness criteria

    The Perception Problem: Judicial Legitimacy Is Not Outcome-Neutral

    A 2025 peer-reviewed study published in PubMed Central examined public perception of judges’ use of AI tools in bail and sentencing decisions. Using an experimental survey design grounded in Tyler’s (2006) procedural justice framework, the study found that AI tools affect public perception of procedural fairness and judicial legitimacy — even when the outcomes are equivalent.

    The finding is direct: AI in judicial decision-making is not perception-neutral. The process by which AI is used materially affects whether the public attributes legitimacy to the resulting decision. The authors concluded that failure to implement ethical guidelines, regulations, and monitoring systems for AI threatens perceived procedural justice and produces legitimacy loss.

    Citation reflects reported judicial practice. Verify with primary case law databases for specific authority.

    This creates a compounding problem. Deployment without oversight produces opacity. Opacity reduces perceived procedural fairness. Reduced fairness perception erodes institutional legitimacy. And legitimacy erosion, once established in public perception of a court system, does not reverse when the governance framework is eventually built. The damage is structurally cumulative. It is not retroactively correctable.

    What a Minimum AI Governance Readiness Standard Requires

    The evidence supports a specific institutional response: international judicial standards bodies — the CEPEJ, the International Association for Court Administration, relevant UN bodies — should establish a minimum AI governance readiness checklist that must be satisfied before any AI system is operationalized in judicial decision-support functions.

    Based on the evidence reviewed, that checklist must address at minimum:

    • External audit requirement — no judicial AI system deployed without independent technical review by a body with no commercial relationship to the provider (addressing the Stimson Center’s accountability deficit and the EU AI Act’s provider-side conformity assessment gap)
    • Bias disclosure protocol — mandatory disclosure to affected parties of known algorithmic fairness trade-offs, including which fairness criterion was selected and which was sacrificed (addressing the Chouldechova impossibility constraint)
    • Human override architecture — documented mechanism for judicial officers to override AI recommendations, with audit trails capturing override frequency and rationale (addressing human-AI interaction bias)
    • Appellate review pathway — procedural mechanism allowing parties to challenge the AI methodology used in their case, not only the outcome (addressing due process concerns raised in State v. Loomis and the opacity problem)
    • Competency threshold for deploying institutions — minimum technical expertise, independence criteria, and institutional capacity a judicial body must demonstrate before commissioning AI deployment (addressing the EU AI Act’s classification-without-competency gap)
    • Periodic re-evaluation mandate — scheduled external re-audit, not only at deployment but at defined intervals, to detect model drift, data staleness, and changing baseline conditions

    The absence of any of these elements does not merely increase risk. It creates a governance vacuum that normalizes opacity before detection mechanisms exist — the structural failure pattern this analysis documents.

    Conclusion

    The structural legitimacy risk of judicial AI is not that the technology fails. It is that the technology is deployed into institutions that lack the architecture to know when it fails.

    The Stimson Center’s four bias vectors, Pakistan’s directive without guidelines, Canada’s hallucination sanctions, the EU AI Act’s classification without competency standards, and the mathematical impossibility of simultaneous fairness criteria all converge on a single finding: deployment speed consistently exceeds oversight readiness. That gap is not a temporary inefficiency to be corrected by catching up. It is a structural failure that produces cumulative, difficult-to-reverse legitimacy damage.

    International judicial standards bodies have the institutional authority to establish minimum AI judicial oversight requirements. The CEPEJ 2025 guidelines provide the closest existing template. The NCSC framework operationalizes the pre-deployment governance principle for U.S. state courts. Neither has been empirically validated at scale. But the alternative — continued deployment into governance vacuums — has an evidence base. COMPAS demonstrated it. Canada’s sanction escalation documents it. Pakistan’s unfulfilled directive illustrates it.

    A minimum readiness checklist is not a barrier to efficiency gains. It is the prerequisite for those gains to be exercised without dismantling the institutional legitimacy that makes judicial authority possible.


    About VeritasJPS

    VeritasJPS provides evidence-based research and advisory at the intersection of jurisprudence, behavioral science, and institutional governance. Our work supports institutional decision-makers — judges, policymakers, and compliance leaders — with rigorous analysis grounded in empirical evidence and legal scholarship.

    Learn more:

  • When Judicial Reform Mandates Die at Implementation: Structural Friction in Self-Governance Bodies

    When Judicial Reform Mandates Die at Implementation: Structural Friction in Self-Governance Bodies

    Abstract

    Judicial reform mandates are routinely issued — and routinely fail at implementation. South Africa’s 2023 Judges’ Conference directed a complete overhaul of the judicial misconduct system. By January 2026, no implementation document had been released. This is not an isolated failure. The Parker misconduct complaint ran nearly six years from filing to determination. The Maumela Tribunal entered its fourth year without producing findings — against a three-month statutory reporting deadline. This analysis examines the structural friction inside judicial self-governance bodies that converts judicial reform mandates into multi-year inaction, drawing on South African, Kenyan, and English institutional evidence alongside the Bangalore Principles framework. The central design defect is identifiable: reform mandates issued without mandatory implementation timelines, public accountability triggers, or external monitoring are structurally indistinguishable from aspirational statements. The question is whether judicial governance architecture should treat them differently.

    The South African Record: From Mandate to Silence

    In 2023, the Judges’ Conference — the judiciary’s own deliberative forum — mandated an overhaul of the misconduct system. Chief Justice Maya confirmed that a Code of Judicial Conduct review was underway. By January 2026, as documented by [EXT-LINK: Judges Matter’s institutional review → institutional review], nothing had been made public. No draft code. No implementation timeline. No progress report. A mandate generated by the judiciary’s own conference, directed at its own governance infrastructure, had produced zero public output in over a year.

    The same architecture produced the Parker Tribunal timeline: a complaint filed in March 2020 that reached a JSC gross misconduct determination only in [EXT-LINK: January 2026 → institutional case report]. Nearly six years. The Maumela Tribunal, documented in [EXT-LINK: Judges Matter’s December 2025 review → institutional review], entered its fourth year with hearings still subject to rolling postponements. The statutory deadline for a tribunal finding is three months. Maumela exceeded that by a factor of twelve.

    These are not delays in the ordinary sense. They are the predictable output of a governance architecture that assigns reform responsibility to the bodies that benefit from the status quo, imposes no enforceable timelines, and provides no external trigger when mandates stall.

    Diagram showing how judicial reform mandates stall at implementation inside self-governance bodies

    The Structural Design Defect

    The Helen Suzman Foundation’s [EXT-LINK: analysis of JSC composition → policy report] identifies the architecture that enables this. The JSC has up to fifteen members from political spheres against eight from non-political backgrounds — judiciary, legal profession, academia. No code of conduct governs commissioner behaviour during interviews or deliberations. The JSC does not meet its own annual reporting obligations. Eleven reform proposals catalogued in the HSF report share a single structural feature: none require binding timelines or external enforcement. All depend on JSC self-implementation.

    This is not a South African peculiarity. It is a design feature of judicial self-governance wherever the Bangalore Principles model operates.

    The [EXT-LINK: Bangalore Principles of Judicial Conduct (2002) → international standard] — the nearest thing to a universal normative framework for judicial accountability — establish that the judiciary should assume an active role in strengthening judicial integrity by effecting systemic reforms within its competence. The [EXT-LINK: Commentary → interpretive guidance] confirms: judges are accountable to appropriate institutions established to maintain judicial standards.

    The defect is embedded in the accountability architecture itself. The Principles presuppose that judges will design, constitute, and operate their own accountability institutions. They contain no mechanism for external intervention when those institutions fail to act on their own mandates. The framework is self-referential. When the self-governance body does not implement its own reform mandate, the Principles provide no consequence, no escalation path, no trigger for external review.

    That gap between normative obligation and enforcement architecture is not a bug in the Bangalore framework. It is the framework.

    Comparative Evidence: Kenya’s Partial Reform and Its Conditions

    Kenya’s post-2010 judicial overhaul offers the most instructive comparison — not because it succeeded, but because the conditions under which it partially succeeded are absent from most self-governance contexts.

    Maya Gainer’s [EXT-LINK: Princeton ISS case study (2015) → case study] documents that by 2010, Kenya had accumulated thirteen separate prior reports on judicial reform. None implemented. The explanation was structural: no political will at leadership level, and an institutional culture characterised by unaccountability, distance, hierarchy, opacity — sometimes driven by a self-serving invocation of the principle of independence.

    Post-2011, partial implementation occurred under a specific combination: an external constitutional mandate; a reform-credentialled Chief Justice (Willy Mutunga) with civil society legitimacy; a judiciary budget that doubled from KSh 3.9 billion to KSh 7.5 billion in a single year; $120 million in World Bank support; thirty-eight nationwide workshops designed to build bottom-up ownership.

    Even then, implementation was incomplete. ICT reforms mandated from the centre failed where internal buy-in was absent. The principal-agent problem persisted — central leadership lacked reliable information about what judicial officers around the country were doing. Many reforms remained in early stages four years in. No post-2015 data tracks whether gains survived Mutunga’s departure.

    Two conclusions follow. Voluntary reform implementation can work — under conditions that include external constitutional mandate, dedicated leadership, doubled budget, and substantial donor support. Those conditions are not replicable by institutional design alone. Where they are absent — as in South Africa’s JSC misconduct reform — the default outcome is the one structural friction predicts: indefinite deferral.

    The HMCTS Counter-Case: External Audit Without Enforcement

    England and Wales offer a different lesson. The HMCTS court and tribunals reform programme — £1.3 billion, multi-year — was subject to independent public audit by the [EXT-LINK: National Audit Office → public audit report]. The 2023 report found that after seven years, HMCTS had completed fifty-five percent of reform projects. The 2018 audit had already identified successful delivery as a significant risk. Four years passed between those two findings.

    The HMCTS case involves operational-technical reform, not judicial conduct governance. The relevance is structural: even with external audit monitoring, programme targets were repeatedly revised without enforcement consequence. The NAO could identify underperformance. It could not compel delivery. Scope reductions and timeline extensions proceeded with no binding accountability trigger at intermediate milestones.

    External monitoring without enforceable consequence functions as documentation, not accountability. Publishing a reform mandate creates a record. Publishing an audit of non-implementation creates a better record. Neither creates a mechanism for compelling action.

    Comparison of judicial reform mandates in South Africa, Kenya, England, and Mexico

    The Counterevidence: When Timelines Become Instruments of Capture

    The strongest argument against mandatory implementation timelines comes from Mexico. López Nachón’s [EXT-LINK: analysis in the Yale Journal of International Law (2025) → legal analysis] documents the 2024 constitutional judicial reform — passed in record time without deliberation by state legislatures. Popular election of judges, terms synchronised to presidential electoral cycles.

    Speed-forcing in judicial reform, when controlled by an executive branch with consolidation objectives, becomes an instrument of authoritarian capture. The absence of deliberation — the condition mandatory timelines could create if politically weaponised — is the mechanism by which reform quality deteriorates and institutional legitimacy erodes.

    That is the legitimate constraint on the mandatory timeline thesis. Timelines imposed from outside the judiciary risk the pathology Mexico demonstrates. The [EXT-LINK: American Progress analysis (2024) → policy analysis] adds a secondary qualification: where the only enforcement mechanism is congressional impeachment — a politically prohibitive threshold — mandatory commitments without functional enforcement create compliance theatre.

    These cases qualify the proposal but do not defeat it. Mexico involves externally imposed reform by an executive branch. South Africa’s problem is the reverse: a self-governance body failing to implement its own mandate. The design variable is who controls the timeline and whether deliberation is preserved. Self-binding timelines — where the governance body commits itself to deadlines with public reporting obligations — sit in a different category from externally imposed political compression.

    The Unaddressed Design Variable: Self-Binding Implementation Architecture

    The evidence across jurisdictions converges. Judicial reform mandates issued without implementation architecture are structurally inert. South Africa documents this. Kenya shows the conditions under which it can be partially overcome. HMCTS shows that monitoring without enforcement is insufficient. Mexico shows that externally imposed speed-forcing creates its own pathologies.

    What no jurisdiction has systematically tested is self-binding implementation architecture: a model in which the governance body that issues a reform mandate simultaneously commits to a public implementation timeline, designates a responsible implementation body distinct from the deliberative body, establishes intermediate milestones with public reporting obligations, and triggers automatic external review — not intervention — when milestones are missed.

    This model preserves judicial independence. The governance body sets its own timeline and milestones. It eliminates the structural permission for indefinite deferral — public reporting and automatic external review create reputational and institutional cost for non-implementation. It is distinct from both the Mexico model (externally imposed, no deliberation) and the current Bangalore model (normatively aspirational, no enforcement).

    The [EXT-LINK: Oslo Law Review analysis (2023) → legal scholarship] identifies one reason this model is underexplored: legal frameworks governing judicial accountability focus almost exclusively on institutional independence, structurally underaddressing individual and internal dimensions. Reform mandates that presuppose individual-level compliance — a code of conduct requiring each judge to act in specified ways — cannot be enforced through institutional accountability frameworks alone. Self-binding implementation architecture would need to operate at both levels.

    Institutional Implications

    Five conclusions for institutional decision-makers.

    Judicial reform mandates issued without implementation timelines, designated implementation bodies, and public reporting obligations are structurally equivalent to aspirational statements. The South African record from 2023 to 2026 documents this with precision.

    The Bangalore Principles framework contains a design-level gap. It establishes the normative obligation for self-governance bodies to implement reform but provides no architecture for accountability when they do not. The gap is inherent to the self-referential accountability model.

    External audit without enforcement authority — the HMCTS model — documents non-implementation but does not remedy it. Monitoring creates transparency. Only enforceable timelines create accountability.

    Mandatory timelines imposed by external political actors — the Mexico model — risk authoritarian capture and deliberation collapse. The design challenge is self-binding architecture, not externally imposed deadlines.

    Kenya’s partial success under specific non-replicable conditions demonstrates that voluntary implementation can work but cannot be relied upon as a structural default.

    The structural question is not whether judicial reform mandates should have implementation timelines. The evidence that undated mandates produce indefinite deferral is consistent across jurisdictions. The question is whether judicial governance bodies will adopt self-binding implementation architecture voluntarily — or whether the structural friction documented here will continue to convert conference-level reform mandates into multi-year inaction.


    About VeritasJPS

    VeritasJPS provides evidence-based research and advisory at the intersection of judicial governance, policy design, and institutional accountability. Our work supports institutional decision-makers — judges, policymakers, and compliance leaders — with rigorous analysis grounded in empirical evidence and legal scholarship.

    Learn more:

  • Paper-Compliance Lag: Why UK Corporate Liability Regimes Structurally Fail in Their First Years

    Paper-Compliance Lag: Why UK Corporate Liability Regimes Structurally Fail in Their First Years

    Abstract

    Paper-compliance lag defines the first-year enforcement pattern visible across three successive UK corporate liability regimes — the Bribery Act 2010 (s.7), the Criminal Finances Act 2017 (ss.45–46), and the Economic Crime and Corporate Transparency Act 2023 (s.199, failure to prevent fraud).

    Three successive UK corporate liability regimes — the Bribery Act 2010 (s.7), the Criminal Finances Act 2017 (ss.45–46), and the Economic Crime and Corporate Transparency Act 2023 (s.199, failure to prevent fraud) — share a structurally repeatable enforcement trajectory: legislation passes, guidance follows, organisations adopt paper compliance, and prosecutions arrive years later. The first s.7 corporate conviction took approximately five and a half years. The first prosecution under ss.45–46 took eight. No prosecution has been brought under s.199 since it entered force in September 2025. This paper-compliance lag pattern is not random.. It is produced by identifiable features of legislative design, prosecutorial resourcing, and organisational response — and it is design-predictable. This analysis argues that enforcement agencies should adopt explicit first-year activation protocols for new corporate liability regimes, rather than accepting structural dormancy as an inevitable cost of corporate criminal law.

    The Dormancy-Then-Activation Arc

    Every major UK “failure to prevent” offence has traced the same arc. Legislation receives Royal Assent. The government publishes guidance — typically months after assent, sometimes after commencement. Organisations respond with compliance documentation. Prosecutors accumulate intelligence. Years later, the first case arrives.

    The Bribery Act 2010 entered force in July 2011. The Ministry of Justice published its “adequate procedures” guidance in March 2011 — nine months after Royal Assent but four months before commencement. The first corporate conviction under s.7, Sweett Group PLC, came in February 2016. Five and a half years. Sweett did not rely on the adequate procedures defence — the company admitted its procedures were absent entirely. The penalty was £2.25 million, a fraction of the financial sanctions secured through Deferred Prosecution Agreements over the same period.

    The Criminal Finances Act 2017 (ss.45–46, failure to prevent facilitation of tax evasion) entered force in September 2017. HMRC published guidance that year. The first corporate prosecution — against an accountancy firm in Stockport — arrived in August 2025. Eight years. By autumn 2025, HMRC confirmed 11 live investigations, 27 “opportunities” under review, and 121 further cases reviewed but not proceeded with. Citation reflects reported judicial practice. Verify with primary case law databases for specific authority.

    The ECCTA 2023 failure to prevent fraud offence (s.199) entered force on 1 September 2025 — nearly two years after Royal Assent in October 2023. Government guidance was published in November 2024. As of March 2026, no prosecution has been brought. The dormancy clock is running.

    What Produces the Lag

    Compliance commentary treats early dormancy as incidental — a by-product of case-building timelines and prosecutorial caution. It is structural. Four interlocking mechanisms generate it across all three regimes.

    Guidance publication timing. In each regime, the gap between Royal Assent and usable guidance opens a window of statutory ambiguity. The MoJ’s Bribery Act guidance drew criticism from Transparency International UK for its insufficient clarity on what “adequate procedures” required — a judgment the House of Lords Select Committee on the Bribery Act endorsed in its 2019 post-legislative scrutiny (HL Paper 303). The Committee found guidance to be vague, high-level, and insufficiently prescriptive. The ECCTA guidance, published twelve months before commencement, was framed as giving organisations time to build fraud prevention procedures. That framing is deliberate design. But it replicates the same compliance-signal-without-enforcement dynamic that characterised each predecessor regime.

    Evidential threshold complexity. Each offence imposes a distinct burden that prosecutors must discharge before initiating proceedings. Under ss.45–46 CFA 2017, HMRC must prove that an “associated person” criminally facilitated tax evasion — not merely that the organisation’s controls were deficient. The ratio of 121 cases reviewed but not proceeded with against 11 live investigations tells a clear story: evidential thresholds operate as a structural brake on prosecution volume in the early years, irrespective of political intent.

    Prosecutorial resource allocation. The SFO’s first decade of s.7 enforcement was characterised by a marked preference for Deferred Prosecution Agreements over criminal convictions. Six DPAs secured financial sanctions exceeding £1 billion — dwarfing the £2.25 million criminal penalty in Sweett Group. That preference may reflect strategic prioritisation rather than incapacity. But it means criminal conviction rates are a misleading metric for enforcement activity — and organisations calibrating their compliance investment to conviction risk are reading the wrong signal. Under ECCTA s.199, both the SFO and CPS hold prosecution authority. The SFO’s updated Compliance Programme Guidance (November 2025) addresses evaluation criteria for “reasonable fraud prevention procedures” but publishes no case-initiation targets or priority sequencing for the new offence.

    Organisational paper compliance. This is the most persistent mechanism and the hardest to measure. When organisations respond to new offences by documenting policies rather than changing conduct, the resulting compliance posture is difficult for prosecutors to falsify at investigation stage. Nine months after the Bribery Act’s commencement, an FTI Consulting survey found that 29% of respondents described themselves as “risk takers” prepared to contravene the Act to win business. Twenty per cent were confident they could do so without detection. Citation reflects reported judicial practice. Verify with primary case law databases for specific authority. That gap — between documented compliance and actual behavioural intent — is precisely where enforcement dormancy takes root.

    The 2025 Anti-Corruption Strategy: Signalling Without Sequencing

    The UK Anti-Corruption Strategy 2025, published in December 2025, contains 123 stated commitments. It signals expansion of the Domestic Corruption Unit, deployment of AI to accelerate investigations, appointment of a dedicated coordinator for “professional enablers,” and reform of the AML/CTF supervisory regime toward a single regulator.

    What it does not contain is an explicit enforcement activation timeline for ECCTA s.199. No prosecutorial priority sequencing for new offences. No case-initiation metrics. No acknowledgment of the structural dormancy pattern that has characterised every preceding failure-to-prevent regime.

    The Strategy reads as political signalling — confirming where governmental attention is directed — not as an operational prosecution framework. This is not a deficiency unique to the current government. No UK enforcement strategy has ever published an explicit first-year activation protocol for a new corporate liability offence. The omission spans administrations.

    The Counterargument: Dormancy as Design

    The strongest objection to characterising early enforcement gaps as structural failure is that they reflect appropriate prosecutorial discretion. The OECD’s Phase 4 UK Report (2017) found that the Bribery Act had prompted substantial progress in corporate anti-corruption compliance — organisations were adopting preventive measures even without prosecutions. Citation reflects reported judicial practice. Verify with primary case law databases for specific authority. On this reading, deterrence operates through the threat of prosecution, not its execution. Early dormancy is an acceptable trade-off for culture change.

    The argument has force. It also has limits.

    If the enforcement threat is never activated — or activated only against firms that have already admitted to absent procedures, as in Sweett Group — the deterrence signal degrades. The FTI 2012 data showed a significant minority of organisations discounting enforcement credibility within the first year. Eight years of zero prosecutions under ss.45–46 CFA 2017 is not a deterrence strategy. It is a credibility deficit.

    The further counterargument — that DPAs constitute active enforcement even when criminal convictions are absent — is jurisdictionally specific. DPAs were available for s.7 Bribery Act cases. Their availability for ECCTA s.199 is not yet tested, and the broader offence scope (Schedule 13 fraud offences) may shift the enforcement calculus entirely. Relying on DPA precedent from one regime to predict enforcement patterns in another is an assumption, not an analysis.

    The Cross-Regime Pattern

    The enforcement trajectories across all three regimes are structurally consistent:

    • Bribery Act s.7 (2010): Commencement July 2011. Guidance lag approximately nine months post-Royal Assent. First corporate prosecution five and a half years post-commencement. No published activation timeline.
    • CFA ss.45–46 (2017): Commencement September 2017. Guidance lag approximately six months. First prosecution eight years post-commencement. No published activation timeline.
    • ECCTA s.199 (2023): Commencement September 2025. Guidance lag approximately twelve months post-Royal Assent. No prosecution as of March 2026. No published activation timeline.

    The dormancy period is lengthening. 5.5 years, then 8. Whether this reflects increasing evidential difficulty, declining prosecutorial capacity, or the normalisation of paper-compliance as a prosecution barrier cannot be determined from current data. No study has disaggregated these variables across regimes.

    The Home Office’s Post-Legislative Scrutiny Memorandum for the CFA 2017, published in May 2024 — seven years after commencement — confirmed zero corporate convictions under ss.45–46 at that date. The first prosecution followed four months later. Parliamentary scrutiny did not accelerate enforcement activation.

    What the Evidence Does Not Cover

    Several material gaps constrain this analysis.

    No published survey measures large-organisation compliance adoption rates, board-level engagement, or training uptake in the first six months following ECCTA s.199 commencement. Pre-commencement advisory materials describe what organisations should do. No data establishes what organisations have done. The FTI 2012 survey on Bribery Act adoption is the nearest proxy — but it measured a different offence, in a different enforcement environment, fourteen years ago.

    No causal disaggregation study separates prosecutorial resource constraints, evidential threshold complexity, deliberate DPA-preference strategy, and organisational paper-compliance opacity as independent contributors to the dormancy period. This is the single most significant analytical gap for policymakers considering activation-trigger design.

    Scotland and Northern Ireland enforcement under both CFA ss.45–46 and ECCTA s.199 is not separately documented. Cross-border enforcement consistency remains uncharted.

    No comparative analysis maps UK dormancy patterns against equivalent regimes in other jurisdictions — Australia’s corporate liability reforms, the US FCPA enforcement model, or France’s Sapin II obligations. Whether the UK pattern is exceptional or typical of common law corporate liability design is an open question.

    The Case for First-Year Activation Protocols

    The evidence supports a specific institutional recommendation: enforcement agencies should publish explicit activation protocols covering the first twelve to twenty-four months of new corporate liability offences.

    An activation protocol would not mandate prosecutions within the first year. It would require published metrics — investigation initiation targets, intelligence-gathering benchmarks, sectoral engagement indicators — that signal prosecutorial capacity and intent during the period of highest behavioural uncertainty. The current model, in which guidance is published and enforcement materialises years later, produces a predictable credibility deficit. The compliance industry fills it with paper documentation. The regulated population fills it with rational discounting.

    The SFO Director’s public statement that corporations must “get their house in order or be ready to face investigation” is necessary but insufficient. Statements of intent without published enforcement scheduling replicate the signalling pattern that preceded dormancy in both prior regimes.

    The UK’s 2025 Anti-Corruption Strategy had an opportunity to break this cycle. It did not take it. Whether the ECCTA s.199 enforcement trajectory will replicate the five-to-eight-year dormancy of its predecessors depends on choices that prosecutors have not yet made public — and that the institutional design of UK corporate criminal enforcement does not currently require them to make.


    About VeritasJPS

    VeritasJPS provides evidence-based research and advisory at the intersection of corporate criminal liability, compliance science, and institutional enforcement design. Our work supports institutional decision-makers — general counsels, compliance directors, policymakers, and regulators — with rigorous analysis grounded in empirical evidence and legal scholarship.

    Learn more: