Before the Audit: How Pre-Oversight AI Deployment Undermines Judicial Legitimacy
Dr. Wasif Ali Shah
PhD Psychology · Barrister · Former Judge

Abstract
Judicial systems across multiple jurisdictions are deploying AI in decision-support functions before external oversight architecture exists to detect or challenge errors. The structural consequence is not hallucination risk or explicit bias — both of which receive adequate attention — but the normalization of opacity in judicial reasoning before any accountability mechanism is operational. This analysis maps the AI judicial oversight vacuum across the EU AI Act’s classification-without-competency gap, Pakistan’s Supreme Court directive that remains without implementing guidelines, Canadian courts sanctioning AI-fabricated citations, and the Stimson Center’s identification of four bias vectors in Global Majority judicial systems. The evidence converges on a single structural failure pattern: deployment speed consistently outpaces oversight readiness, and the resulting legitimacy erosion compounds before institutions recognize the deficit. A minimum AI governance readiness standard — established at the international level before further operationalization — is not a regulatory luxury. It is a prerequisite for maintaining the institutional authority on which judicial legitimacy depends.
The Structural Problem: AI Deployment Without Oversight Detection
The dominant framing of AI risk in judicial settings focuses on two failure modes: hallucination (AI fabricating legal authorities) and explicit bias (algorithmic outputs that discriminate along racial or socioeconomic lines). Both are real. Neither captures the deeper structural problem.
The structural legitimacy risk operates at a different level. When an AI system enters a judicial decision-support function — case scheduling, risk assessment, legal research assistance, sentencing recommendation — without external audit requirements, the system’s reasoning becomes embedded in institutional practice before anyone outside the deploying body can examine how it works. Opacity becomes the default. And defaults, once institutionalized, resist reversal. The absence of AI judicial oversight at the point of deployment is the root structural failure.
The Stimson Center’s January 2026 report identifies four distinct bias vectors in judicial AI deployment across Global Majority systems: data bias (training data that reflects existing disadvantage), coding bias (programmer assumptions embedded in legal logic translation), intentional misuse (political exploitation of AI’s apparent neutrality in weak judicial systems), and human-AI interaction bias (judges either over-relying on or superficially dismissing AI outputs). The report concludes that opaque AI tools generate an accountability deficit producing what it terms “obscure justice.” Each vector is individually addressable — but only if an external audit mechanism exists at the point of deployment. Without one, the vectors compound undetected.
The Hallucination Cases: Demand-Side Evidence of Systemic Fragility
Canada’s courts produced three separate sanctions for AI-fabricated legal citations in 2025, each escalating in severity.
In Ko v Li, 2025 ONSC 2766, the Ontario Superior Court addressed a lawyer who submitted non-existent cases generated by AI. Justice Meyers noted that the legal community had been explicitly warned since 2023 that AI-generated content requires verification — the failure was not technological ignorance but institutional discipline breakdown. In October 2025, a Quebec court imposed a C$5,000 sanction on a self-represented litigant who submitted eight fictitious case citations. By December, the Alberta Court of Appeal levied $500 in costs against a litigant for three fabricated authorities, with an explicit warning that future violations would attract substantially greater penalties.
These are demand-side failures — lawyers and litigants misusing AI tools, not courts deploying them. But they expose the same structural vulnerability. The fabricated authority entered the judicial record each time through a channel that lacked any automated verification gate. The court detected the error only through traditional human review. Scale that detection requirement across hundreds of thousands of filings per year, and the governance gap becomes quantifiable: human review cannot catch what automated systems generate at volume without institutional infrastructure built for the task.
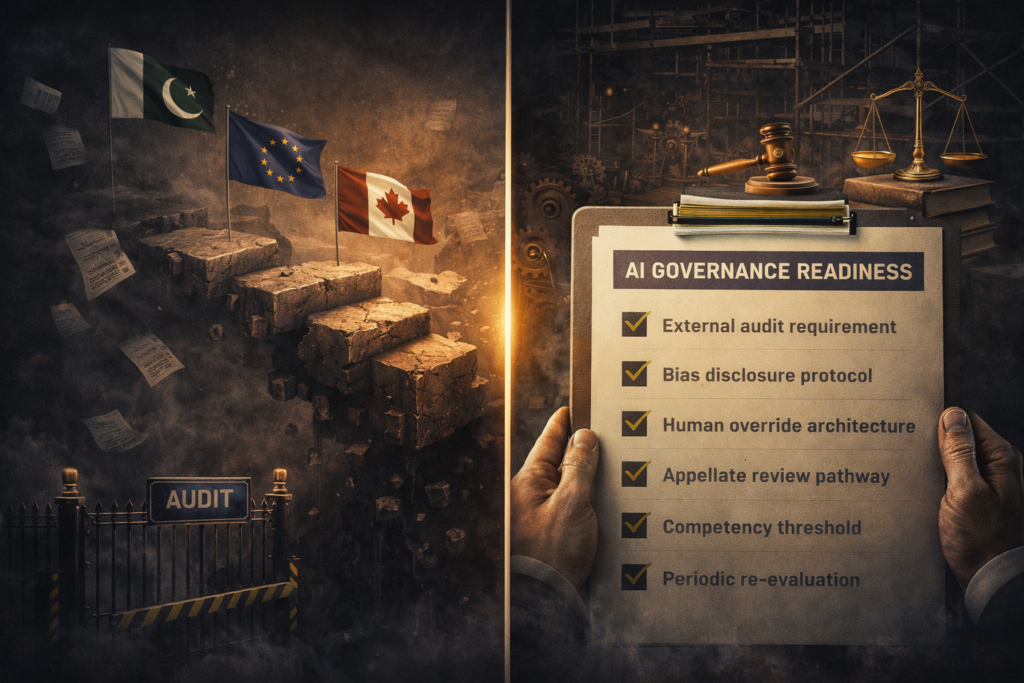
Pakistan’s “Calibrated Integration”: AI Judicial Oversight Without Architecture
In April 2025, Pakistan’s Supreme Court issued an 18-page ruling addressing AI use in the judiciary. Led by Justice Syed Mansoor Ali Shah, the two-judge bench articulated a “calibrated integration” standard: AI functions as a facilitative tool only, never replacing human judicial autonomy or constitutional fidelity under Articles 10A and 37(d) (the rights to fair trial and speedy justice).
The ruling directed the National Judicial (Policy Making) Committee and the Law and Justice Commission of Pakistan to jointly develop guidelines delineating clear boundaries for permissible AI uses in courts. The diagnosis was precise. The institutional follow-through has been absent.
As of early 2026, available records contain no published guidelines from either body. The ruling identifies the governance gap without closing it. “Calibrated integration” remains a standard without operational definition — a judicial instruction that AI deployment should be careful, issued to institutions that have not yet built the infrastructure to determine what “careful” means in practice.
Citation reflects reported judicial practice. Verify with primary case law databases for specific authority.
This pattern — a senior court articulating the principle while the implementing bodies lack the capacity or mandate to operationalize it — is not unique to Pakistan. It is the structural failure mode that pre-oversight deployment produces. The diagnosis exists. The institutional machinery to act on it does not.
The EU AI Act: Classification Without Competency
The EU AI Act (Regulation 2024/1689) addresses judicial AI directly. Annex III, Category 8(a) classifies AI systems intended for use by courts to research and interpret facts or law, or to apply law to concrete facts, as high-risk. This classification triggers conformity assessment before deployment, risk management systems, technical documentation, transparency obligations, and human oversight requirements. The compliance deadline for Annex III systems is August 2, 2026.
The classification is correct. The governance infrastructure to support it is incomplete.
The Act does not prescribe minimum audit competency standards for national judicial bodies. It does not specify what technical expertise, what independence criteria, or what institutional capacity a national court system must possess to commission or validate a conformity assessment for an AI system it intends to deploy. The conformity assessment obligation under Article 43 falls primarily on providers — the companies building the systems — not on the judicial institutions deploying them.
Article 6(3) compounds the problem. It creates a derogation: a system is not classified as high-risk if it does not “materially influence the outcome of decision making” or performs only a “narrow procedural task.” A provider can claim that a legal research tool merely surfaces information — it does not influence outcomes. Whether that claim is tested depends on whether the deploying institution has the audit capacity to challenge it. Most do not.
The gap between classification and operational readiness is the EU AI Act’s structural weakness for judicial deployment. The Act tells member states that judicial AI is high-risk. It does not tell judicial institutions how to verify that classification is being properly enforced.
The Fairness Impossibility: What AI Governance Cannot Solve
Any governance framework for judicial AI must confront a mathematical constraint that limits what even the best-designed oversight can achieve.
Chouldechova (2017) demonstrated that when base rates differ across demographic groups — as recidivism rates do across racial groups in every jurisdiction where they have been measured — no algorithm can simultaneously satisfy predictive parity (equal accuracy across groups) and equalized error rates (equal false positive and false negative rates across groups). These fairness criteria are mutually exclusive. The ProPublica analysis of COMPAS — examining over 7,000 defendants in Broward County, Florida — found that Black defendants who did not reoffend were nearly twice as likely as white defendants to be incorrectly classified as high-risk (45% versus 23% false positive rate). Northpointe contested the analysis by arguing that COMPAS satisfies predictive parity. Both findings are independently replicated. The conflict is mathematical, not empirical.
This matters for the governance argument because it establishes what external audit can and cannot deliver. Pre-deployment oversight can guarantee bias detection and disclosure. It cannot guarantee bias elimination. A governance readiness checklist must therefore include not only audit mechanisms but also disclosure protocols: how will courts inform defendants, litigants, and the public that the system they rely on produces irreducible disparities? No framework currently in operation answers that question.
Counterpoint: Governance-First Models That Work
The structural failure pattern is not universal. Several jurisdictions have built governance infrastructure before or alongside deployment.
The National Center for State Courts published its AI Readiness for State Courts guide in October 2025, convening 16 subject-matter experts to produce a three-level framework: strategic planning (governance committee, guiding principles, data governance), project implementation (stakeholder co-creation, total cost assessment), and continuous adaptation (human oversight, performance monitoring, drift prevention). The framework operationalizes a 12-month governance plan. Its core principle is direct: governance infrastructure must be established before deployment, not retrofitted.
Singapore’s Ministry of Justice launched a public consultation in September 2025 on a Guide for Using Generative AI in the Legal Sector, mandating a “lawyer in the loop” and verification of all AI output before use. Singapore’s broader public-sector agentic AI framework, analyzed by GovInsider in November 2025, operates from a principle that trust is infrastructure — governance reduces adoption resistance rather than increasing it.
The CEPEJ 2025 guidelines on generative AI in judicial systems — building on the Council of Europe’s 2018 Ethical Charter — require incremental deployment, pilot phases with evaluation, regular audits, ongoing monitoring, and independent expert certification. These are non-binding recommendations, and compliance tracking is not yet publicly available. But they represent the most detailed international standard for judicial AI governance currently in existence.
The counterpoint is real but limited. No jurisdiction has published longitudinal data demonstrating that governance-first deployment prevented the legitimacy harm that deployment-first approaches produce. The NCSC framework has not been empirically tested against outcomes. Singapore’s framework is too recent for outcome measurement. The evidence supports the feasibility of pre-deployment governance. It does not yet demonstrate its effectiveness at the institutional trust level.
The Perception Problem: Judicial Legitimacy Is Not Outcome-Neutral
A 2025 peer-reviewed study published in PubMed Central examined public perception of judges’ use of AI tools in bail and sentencing decisions. Using an experimental survey design grounded in Tyler’s (2006) procedural justice framework, the study found that AI tools affect public perception of procedural fairness and judicial legitimacy — even when the outcomes are equivalent.
The finding is direct: AI in judicial decision-making is not perception-neutral. The process by which AI is used materially affects whether the public attributes legitimacy to the resulting decision. The authors concluded that failure to implement ethical guidelines, regulations, and monitoring systems for AI threatens perceived procedural justice and produces legitimacy loss.
Citation reflects reported judicial practice. Verify with primary case law databases for specific authority.
This creates a compounding problem. Deployment without oversight produces opacity. Opacity reduces perceived procedural fairness. Reduced fairness perception erodes institutional legitimacy. And legitimacy erosion, once established in public perception of a court system, does not reverse when the governance framework is eventually built. The damage is structurally cumulative. It is not retroactively correctable.
What a Minimum AI Governance Readiness Standard Requires
The evidence supports a specific institutional response: international judicial standards bodies — the CEPEJ, the International Association for Court Administration, relevant UN bodies — should establish a minimum AI governance readiness checklist that must be satisfied before any AI system is operationalized in judicial decision-support functions.
Based on the evidence reviewed, that checklist must address at minimum:
- External audit requirement — no judicial AI system deployed without independent technical review by a body with no commercial relationship to the provider (addressing the Stimson Center’s accountability deficit and the EU AI Act’s provider-side conformity assessment gap)
- Bias disclosure protocol — mandatory disclosure to affected parties of known algorithmic fairness trade-offs, including which fairness criterion was selected and which was sacrificed (addressing the Chouldechova impossibility constraint)
- Human override architecture — documented mechanism for judicial officers to override AI recommendations, with audit trails capturing override frequency and rationale (addressing human-AI interaction bias)
- Appellate review pathway — procedural mechanism allowing parties to challenge the AI methodology used in their case, not only the outcome (addressing due process concerns raised in State v. Loomis and the opacity problem)
- Competency threshold for deploying institutions — minimum technical expertise, independence criteria, and institutional capacity a judicial body must demonstrate before commissioning AI deployment (addressing the EU AI Act’s classification-without-competency gap)
- Periodic re-evaluation mandate — scheduled external re-audit, not only at deployment but at defined intervals, to detect model drift, data staleness, and changing baseline conditions
The absence of any of these elements does not merely increase risk. It creates a governance vacuum that normalizes opacity before detection mechanisms exist — the structural failure pattern this analysis documents.
Conclusion
The structural legitimacy risk of judicial AI is not that the technology fails. It is that the technology is deployed into institutions that lack the architecture to know when it fails.
The Stimson Center’s four bias vectors, Pakistan’s directive without guidelines, Canada’s hallucination sanctions, the EU AI Act’s classification without competency standards, and the mathematical impossibility of simultaneous fairness criteria all converge on a single finding: deployment speed consistently exceeds oversight readiness. That gap is not a temporary inefficiency to be corrected by catching up. It is a structural failure that produces cumulative, difficult-to-reverse legitimacy damage.
International judicial standards bodies have the institutional authority to establish minimum AI judicial oversight requirements. The CEPEJ 2025 guidelines provide the closest existing template. The NCSC framework operationalizes the pre-deployment governance principle for U.S. state courts. Neither has been empirically validated at scale. But the alternative — continued deployment into governance vacuums — has an evidence base. COMPAS demonstrated it. Canada’s sanction escalation documents it. Pakistan’s unfulfilled directive illustrates it.
A minimum readiness checklist is not a barrier to efficiency gains. It is the prerequisite for those gains to be exercised without dismantling the institutional legitimacy that makes judicial authority possible.
About VeritasJPS
VeritasJPS provides evidence-based research and advisory at the intersection of jurisprudence, behavioral science, and institutional governance. Our work supports institutional decision-makers — judges, policymakers, and compliance leaders — with rigorous analysis grounded in empirical evidence and legal scholarship.
Cite This Analysis
Shah, S. W. A. (2026). Before the Audit: How Pre-Oversight AI Deployment Undermines Judicial Legitimacy. VERITAS Jurisprudence & Psychological Science. Published 18 February 2026. https://veritasjps.com/research-analysis/ai-judicial-oversight-pre-deployment-legitimacy-risk/Published 18 February 2026 · Updated 19 March 2026
VeritasJPS — Law, Policy & Behavioral Research
Browse All Research & Analysis →Related Research

Automation Bias in AI Human Oversight Under the EU AI Act
Quick Answer: Automation bias is the cognitive mechanism Article 14 of the EU AI Act names but does not functionally regulate. The Act requires awareness of over-reliance, yet it does not mandate behavioral countermeasures such as cognitive forcing, override protocols, or audit trails for judicial AI oversight. Abstract The EU AI Act is the first […]

Optimism Bias and the Enforcement Communication Gap: Why Regulated Entities Discount Compliance Risk
Optimism bias in compliance risk helps explain why regulated entities discount enforcement exposure. This article analyses asymmetric belief updating, omission neglect, and the communication design gap that leaves paper-compliance structurally intact.

Physical Infrastructure Failure as Structural Denial of Access to Justice for Persons with Disabilities
Court accessibility under CRPD remains largely unverifiable because states acknowledge the right, document physical barriers, and still avoid independent audit of justice facilities, police stations, and detention sites.