Author: wasif

  • Why GBV Response Protocols Fail at Early Intervention

    Why GBV Response Protocols Fail at Early Intervention

    Abstract

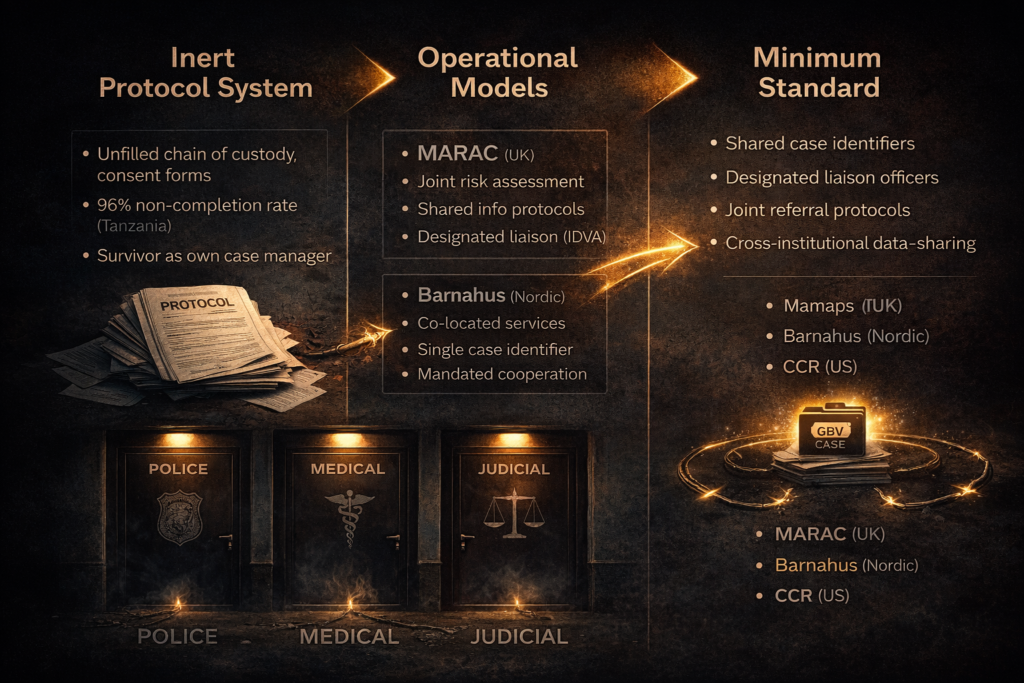
    Cross-institutional coordination protocols for gender-based violence response exist across most jurisdictions that have committed to prevention frameworks. They are also, by every available measure, operationally inert. In Tanzania, direct observation found that only 16.4% of health care providers adhered to GBV screening protocols — with more than 95% failing to complete the chain-of-custody documents that enable cross-institutional evidence transfer. In South Africa, 85% of GBV survivors reported police incompetence, with officials consistently failing to follow established procedures for inter-agency case handling. The consequence is structural: survivors are forced to act as their own case managers, carrying information between police, medical, and judicial institutions that should be sharing it automatically. This analysis examines why the gap between protocol existence and protocol operation persists, what design standards have been shown to reduce it, and why no binding international framework mandates the minimum requirements — shared case identifiers, designated liaisons, joint referral protocols — that would make written commitments operational.

    Why the GBV Protocol-to-Operation Gap Is Systemic

    Most GBV reform discourse assumes the problem is attitudinal — that training, awareness campaigns, and cultural change will close the gap between law on paper and law in practice. The evidence suggests otherwise. The failure is architectural.

    In Dodoma Region, Tanzania, Mtaita et al. conducted direct observational measurement of health care provider adherence to GBV screening protocols using the WHO/CDC Gender Based Violence Quality Assurance tool — a 12-item checklist applied in health facilities. The result: only 16.4% of providers adhered to established protocols and procedures. More than 95% did not complete chain-of-custody forms, consent forms, or GBV medical forms — the exact documents that enable evidence to move between health, police, and judicial systems. Providers without GBV-specific training were significantly less likely to comply than trained staff, but even among trained providers, completion rates for cross-institutional documentation remained negligible.

    This is not a training deficit alone. It is a system design failure. The protocols exist. The forms exist. The institutional expectation exists. What does not exist is any enforcement mechanism, accountability structure, or feedback loop that makes non-compliance visible or consequential.

    At scale, the pattern holds. The Centre for Justice’s 2025 study of GBV survivors in South Africa reported that 85% experienced police incompetence, with officials consistently failing to follow established cross-agency case-handling procedures. Eighty-three percent of survivors did not know what resources were available to them. Seventy-nine percent cited lack of police resources, and 87% lacked the financial means to access services independently. The burden of managing handoffs between police stations, hospitals, courts, and social services fell on survivors themselves.

    Citation reflects reported judicial practice. Verify with primary case law databases for specific authority.

    How Survivors Become Their Own Case Managers

    When inter-agency case handling collapses, the failure does not produce a vacuum. It produces a transfer of labour. The administrative, evidentiary, and relational work that a functioning referral system should perform automatically shifts to the person least equipped to perform it: the survivor.

    CFJ’s data documents this transfer directly. Survivors reported facilitating required paperwork and interactions between police, medical, judicial, and social service systems — work that presupposes familiarity with institutional processes, physical mobility between dispersed service points, emotional capacity to repeat disclosures across agencies, and time that competing survival needs do not spare.

    The International Development Law Organization’s 2022 multi-country analysis of GBV justice delivery in conflict and fragile-state settings identified the same structural pattern at system level. IDLO reported that functional, accessible referral pathways were absent, with gaps between state services, humanitarian actors, and local organizations going unaddressed. Roles and responsibilities in case handling remained undefined across agencies. Without a designated authority responsible for implementing a multisectoral framework, no institution owned the handoff function — and survivors filled the gap by default.

    This is not merely inconvenient. It is structurally destructive to early intervention. Each failed handoff delays evidence collection, erodes forensic value, forces repeat disclosure (with documented re-traumatisation effects), and increases the probability of case abandonment. The model is also self-defeating: the individuals most likely to abandon a justice process are those required to manage it themselves while simultaneously recovering from the violence that initiated it.
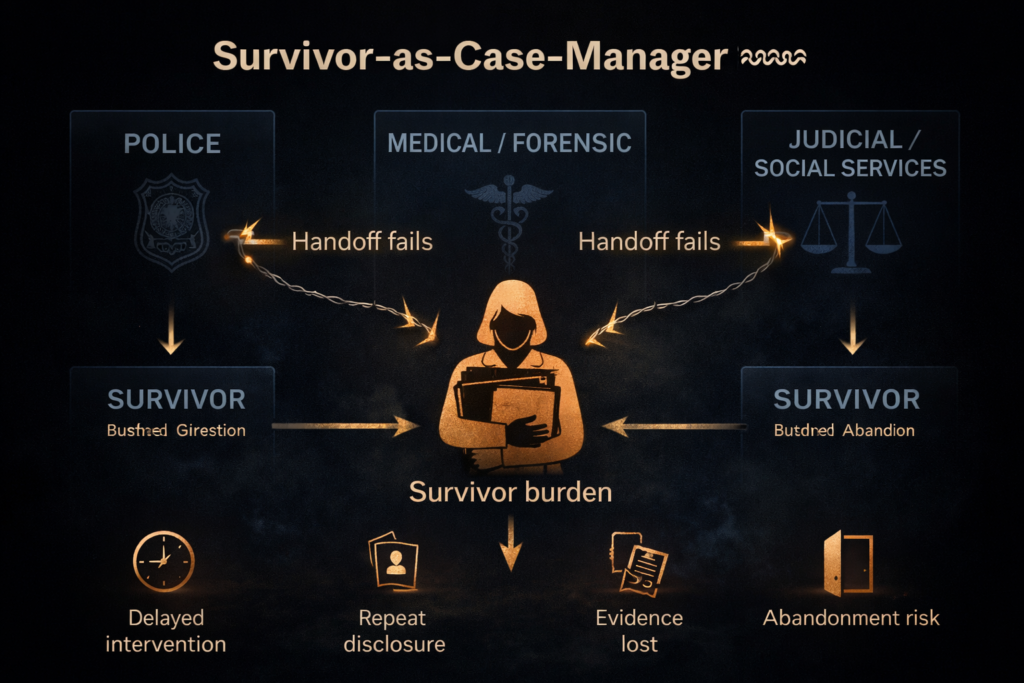
    GBV response protocols breaking down between police, health, and courts

    Three GBV Coordination Models with Measurable Outcomes

    The evidence is not uniformly bleak. Three models — each operating in different institutional contexts — have demonstrated measurable improvements in survivor outcomes by building referral and accountability architecture into institutional structure rather than relying on individual compliance.

    The UK Multi-Agency Risk Assessment Conference (MARAC)

    Evaluated by SafeLives across England and Wales, the MARAC model operates on a core design premise: no single agency can see the complete picture of a survivor’s risk, but each holds information critical to safety assessment. MARACs bring police, health, housing, children’s services, probation, and specialist domestic violence services into structured information-sharing meetings. A standardised risk identification checklist (DASH) determines referral thresholds.

    SafeLives’ pilot evaluation showed that 40% of survivors suffered no further abuse one year after their MARAC case. Design features include shared information-sharing protocols, an Independent Domestic Violence Adviser (IDVA) who represents survivor voice without requiring survivor attendance, and agency-specific action plans with designated accountability.

    Replicated in Scotland, Ireland, Australia, and Canada, the MARAC model is not self-sustaining. SafeLives’ own quality assurance data shows that MARACs fail their operational standards when agency representatives lack authority to commit resources, or when agencies under-resource their participation. The 40% figure derives from pilot conditions — national rollout data shows significant variation in case quality and safety-plan follow-through. Where the model’s structure is enforced, it works. Where it is treated as an optional inter-agency courtesy, it degrades.

    The Nordic Barnahus (Children’s House) Model

    Evaluated nationally in Norway by Bakketeig et al. and reviewed comparatively across Nordic states by Kaldal for the Council of Europe, the Barnahus model addresses a different but structurally parallel problem: the fragmentation of institutional responses to child victims of sexual abuse and violence.

    Barnahus centres integrate forensic interviewing (police), medical examination, therapeutic support, and legal process into a single physical location. Norway’s national evaluation showed that children interviewed at Barnahus received better care outcomes than those interviewed at police stations. In Iceland, forensic interviews were conducted within one week of allegation, with recorded interviews used directly as court evidence — eliminating repeat disclosure entirely.

    The architectural insight is simple: shared physical location functions as a shared case identifier by design. When all agencies operate from the same site, information exchange is a byproduct of proximity rather than a protocol that must be separately policed.

    A significant limitation applies. The Barnahus model was designed for child victims, and no formally evaluated adult-GBV equivalent exists. Its success depends on Nordic welfare-state conditions — high inter-agency trust, stable funding, professionalized and relatively low-corruption agencies, and legislative frameworks that require cooperation. Documented tension between therapeutic and forensic objectives (therapeutic support can only begin after the forensic interview concludes) remains unresolved across implementations.
    Conflict zones where weak GBV response protocols increase impunity

    The US Coordinated Community Response (CCR/Duluth Model)

    Originating from the Duluth Domestic Abuse Intervention Program and synthesised in a 2021 N8 Policing Research Partnership analysis, the CCR model builds accountability into each point of case processing — not just at intake. Administrative data tools track context, risk, and relationship history across agencies. Advocacy organizations are positioned as inter-agency connectors, not add-on services, enabling survivor input to identify system gaps in real time.

    Victim safety and offender accountability are treated as co-equal mandates, distributed across all participating agencies rather than concentrated in any single gatekeeping institution.

    Replication evidence is mixed. Communities with strong advocacy sector capacity show higher fidelity; communities where advocacy organizations are under-resourced or where law enforcement resists non-statutory actor involvement in case processing show lower fidelity and degraded outcomes. No randomised controlled trial has evaluated the model, and effect sizes for survivor attrition reduction are not consistently documented across sites.

    The International Normative Gap: CEDAW Mandates Outcomes, Not Architecture

    All three models share common design elements: standardised risk assessment instruments, shared information exchange (whether by protocol or physical co-location), designated cross-agency representatives with decision-making authority, and accountability mechanisms for non-participation. None is mandated by binding international law.

    The CEDAW Committee’s General Recommendation No. 35 (2017), updating GR 19 (1992), obliges States Parties to adopt diverse institutional measures “in coordination with the relevant State branches” — including public policy design, monitoring mechanisms, and competent national tribunals. GR 35 establishes the prohibition of gender-based violence as a norm of international customary law and defines levels of State liability for acts, omissions, and failure to act with due diligence.

    What GR 35 does not do is specify minimum inter-agency design standards. No mandate for shared case identifiers. No requirement for designated liaison officers between police, medical, and judicial institutions. No specification of joint referral protocol standards. No minimum data-sharing requirements between agencies handling the same survivor’s case.

    GR 35 requires coordination outcomes — prevention, investigation, prosecution, and reparation. It does not prescribe the operational architecture through which those outcomes must be achieved. That gap — between normative obligation and implementation specification — is precisely what permits jurisdictions to maintain nominally compliant frameworks that are, in practice, operationally inert. Tanzania and South Africa are not outliers. They are the pattern.

    The Crisis Multiplier: When Institutional Capacity Collapses, Impunity Scales

    The silo failure documented in stable-state jurisdictions compounds exponentially in conflict and crisis settings. UN Women’s 2026 report on access to justice for women and girls — released March 5, 2026 — reported that 676 million women and girls lived within 50 kilometres of a deadly conflict in 2024, the highest figure since the 1990s. Reports of conflict-related sexual violence increased by 87% that year. Nearly 70% of countries surveyed maintained discriminatory legal frameworks preventing equal justice access for women, and 54% lacked consent-based definitions of rape.

    In these settings, collapsed or disrupted capacity functions as a structural multiplier of impunity. The referral mechanisms that are merely dysfunctional in stable states are entirely absent in crisis zones. IDLO’s 2022 analysis of Honduras, Afghanistan, and comparable fragile-state jurisdictions documented corruption, limited forensic specialist capacity, poor information systems, and absence of national data collection as compounding inhibitors — structural conditions under which even well-designed protocols cannot operate.

    A concurrent funding crisis accelerates the collapse. UN Women’s 2026 data reports that 90% of organizations working to end violence against women face cuts to essential services, and only 5% believe they can sustain operations beyond two years without increased funding. Designing minimum inter-agency standards is therefore inseparable from a documented collapse in the capacity to operate any framework at all.

    Toward a Minimum Standard

    The evidence points to a specific, addressable gap. GBV inter-agency response is not impossible — the MARAC, Barnahus, and CCR models demonstrate measurable success where referral and accountability structures are built into institutional operation. What is missing is a binding framework that mandates the minimum design elements separating operational systems from nominal ones.

    A minimum standard — applicable across police, medical, and judicial institutions — would require at least:

    • Shared case identifiers that follow a survivor’s case across all institutions handling it, eliminating the requirement for survivors to re-establish their case at each contact point.
    • Designated liaison officers in each participating institution with cross-agency authority to share information and commit resources — not discretionary representatives who attend meetings without decision-making power.
    • Joint referral protocols with specified timeframes, documentation requirements, and accountability mechanisms for non-compliance — enforced through institutional performance metrics, not voluntary goodwill.
    • Cross-institutional data-sharing agreements that are operationally active (not merely signed), with audit mechanisms to measure actual information flow.

    None of these elements requires new legal theory. Each exists in at least one evaluated model. The gap is that no international or regional instrument compiles them into a binding minimum that domestic judicial and administrative systems must meet.

    The CEDAW Committee is positioned to issue such technical guidance — building on GR 35’s normative framework with architecture-level specification. Until it does, the pattern will persist across South Africa, Tanzania, Honduras, Afghanistan, and the 676 million women living within reach of armed conflict: protocols that exist on paper, institutions that do not follow them, and survivors forced to manage their own cases through systems designed to serve them.


    About VeritasJPS

    VeritasJPS provides evidence-based research and advisory at the intersection of jurisprudence, behavioral science, and institutional governance. Our work supports institutional decision-makers — judges, policymakers, and compliance leaders — with rigorous analysis grounded in empirical evidence and legal scholarship.
    Learn more:

  • Before the Audit: How Pre-Oversight AI Deployment Undermines Judicial Legitimacy

    Before the Audit: How Pre-Oversight AI Deployment Undermines Judicial Legitimacy


    Abstract

    Judicial systems across multiple jurisdictions are deploying AI in decision-support functions before external oversight architecture exists to detect or challenge errors. The structural consequence is not hallucination risk or explicit bias — both of which receive adequate attention — but the normalization of opacity in judicial reasoning before any accountability mechanism is operational. This analysis maps the AI judicial oversight vacuum across the EU AI Act’s classification-without-competency gap, Pakistan’s Supreme Court directive that remains without implementing guidelines, Canadian courts sanctioning AI-fabricated citations, and the Stimson Center’s identification of four bias vectors in Global Majority judicial systems. The evidence converges on a single structural failure pattern: deployment speed consistently outpaces oversight readiness, and the resulting legitimacy erosion compounds before institutions recognize the deficit. A minimum AI governance readiness standard — established at the international level before further operationalization — is not a regulatory luxury. It is a prerequisite for maintaining the institutional authority on which judicial legitimacy depends.

    The Structural Problem: AI Deployment Without Oversight Detection

    The dominant framing of AI risk in judicial settings focuses on two failure modes: hallucination (AI fabricating legal authorities) and explicit bias (algorithmic outputs that discriminate along racial or socioeconomic lines). Both are real. Neither captures the deeper structural problem.

    The structural legitimacy risk operates at a different level. When an AI system enters a judicial decision-support function — case scheduling, risk assessment, legal research assistance, sentencing recommendation — without external audit requirements, the system’s reasoning becomes embedded in institutional practice before anyone outside the deploying body can examine how it works. Opacity becomes the default. And defaults, once institutionalized, resist reversal. The absence of AI judicial oversight at the point of deployment is the root structural failure.

    The Stimson Center’s January 2026 report identifies four distinct bias vectors in judicial AI deployment across Global Majority systems: data bias (training data that reflects existing disadvantage), coding bias (programmer assumptions embedded in legal logic translation), intentional misuse (political exploitation of AI’s apparent neutrality in weak judicial systems), and human-AI interaction bias (judges either over-relying on or superficially dismissing AI outputs). The report concludes that opaque AI tools generate an accountability deficit producing what it terms “obscure justice.” Each vector is individually addressable — but only if an external audit mechanism exists at the point of deployment. Without one, the vectors compound undetected.

    The Hallucination Cases: Demand-Side Evidence of Systemic Fragility

    Canada’s courts produced three separate sanctions for AI-fabricated legal citations in 2025, each escalating in severity.

    In Ko v Li, 2025 ONSC 2766, the Ontario Superior Court addressed a lawyer who submitted non-existent cases generated by AI. Justice Meyers noted that the legal community had been explicitly warned since 2023 that AI-generated content requires verification — the failure was not technological ignorance but institutional discipline breakdown. In October 2025, a Quebec court imposed a C$5,000 sanction on a self-represented litigant who submitted eight fictitious case citations. By December, the Alberta Court of Appeal levied $500 in costs against a litigant for three fabricated authorities, with an explicit warning that future violations would attract substantially greater penalties.

    These are demand-side failures — lawyers and litigants misusing AI tools, not courts deploying them. But they expose the same structural vulnerability. The fabricated authority entered the judicial record each time through a channel that lacked any automated verification gate. The court detected the error only through traditional human review. Scale that detection requirement across hundreds of thousands of filings per year, and the governance gap becomes quantifiable: human review cannot catch what automated systems generate at volume without institutional infrastructure built for the task.

    Timeline comparing AI judicial oversight frameworks across EU, Pakistan, Canada, and Singapore

    Pakistan’s “Calibrated Integration”: AI Judicial Oversight Without Architecture

    In April 2025, Pakistan’s Supreme Court issued an 18-page ruling addressing AI use in the judiciary. Led by Justice Syed Mansoor Ali Shah, the two-judge bench articulated a “calibrated integration” standard: AI functions as a facilitative tool only, never replacing human judicial autonomy or constitutional fidelity under Articles 10A and 37(d) (the rights to fair trial and speedy justice).

    The ruling directed the National Judicial (Policy Making) Committee and the Law and Justice Commission of Pakistan to jointly develop guidelines delineating clear boundaries for permissible AI uses in courts. The diagnosis was precise. The institutional follow-through has been absent.

    As of early 2026, available records contain no published guidelines from either body. The ruling identifies the governance gap without closing it. “Calibrated integration” remains a standard without operational definition — a judicial instruction that AI deployment should be careful, issued to institutions that have not yet built the infrastructure to determine what “careful” means in practice.

    Citation reflects reported judicial practice. Verify with primary case law databases for specific authority.

    This pattern — a senior court articulating the principle while the implementing bodies lack the capacity or mandate to operationalize it — is not unique to Pakistan. It is the structural failure mode that pre-oversight deployment produces. The diagnosis exists. The institutional machinery to act on it does not.

    The EU AI Act: Classification Without Competency

    The EU AI Act (Regulation 2024/1689) addresses judicial AI directly. Annex III, Category 8(a) classifies AI systems intended for use by courts to research and interpret facts or law, or to apply law to concrete facts, as high-risk. This classification triggers conformity assessment before deployment, risk management systems, technical documentation, transparency obligations, and human oversight requirements. The compliance deadline for Annex III systems is August 2, 2026.

    The classification is correct. The governance infrastructure to support it is incomplete.

    The Act does not prescribe minimum audit competency standards for national judicial bodies. It does not specify what technical expertise, what independence criteria, or what institutional capacity a national court system must possess to commission or validate a conformity assessment for an AI system it intends to deploy. The conformity assessment obligation under Article 43 falls primarily on providers — the companies building the systems — not on the judicial institutions deploying them.

    Article 6(3) compounds the problem. It creates a derogation: a system is not classified as high-risk if it does not “materially influence the outcome of decision making” or performs only a “narrow procedural task.” A provider can claim that a legal research tool merely surfaces information — it does not influence outcomes. Whether that claim is tested depends on whether the deploying institution has the audit capacity to challenge it. Most do not.

    The gap between classification and operational readiness is the EU AI Act’s structural weakness for judicial deployment. The Act tells member states that judicial AI is high-risk. It does not tell judicial institutions how to verify that classification is being properly enforced.

    The Fairness Impossibility: What AI Governance Cannot Solve

    Any governance framework for judicial AI must confront a mathematical constraint that limits what even the best-designed oversight can achieve.

    Chouldechova (2017) demonstrated that when base rates differ across demographic groups — as recidivism rates do across racial groups in every jurisdiction where they have been measured — no algorithm can simultaneously satisfy predictive parity (equal accuracy across groups) and equalized error rates (equal false positive and false negative rates across groups). These fairness criteria are mutually exclusive. The ProPublica analysis of COMPAS — examining over 7,000 defendants in Broward County, Florida — found that Black defendants who did not reoffend were nearly twice as likely as white defendants to be incorrectly classified as high-risk (45% versus 23% false positive rate). Northpointe contested the analysis by arguing that COMPAS satisfies predictive parity. Both findings are independently replicated. The conflict is mathematical, not empirical.

    This matters for the governance argument because it establishes what external audit can and cannot deliver. Pre-deployment oversight can guarantee bias detection and disclosure. It cannot guarantee bias elimination. A governance readiness checklist must therefore include not only audit mechanisms but also disclosure protocols: how will courts inform defendants, litigants, and the public that the system they rely on produces irreducible disparities? No framework currently in operation answers that question.

    Counterpoint: Governance-First Models That Work

    The structural failure pattern is not universal. Several jurisdictions have built governance infrastructure before or alongside deployment.

    The National Center for State Courts published its AI Readiness for State Courts guide in October 2025, convening 16 subject-matter experts to produce a three-level framework: strategic planning (governance committee, guiding principles, data governance), project implementation (stakeholder co-creation, total cost assessment), and continuous adaptation (human oversight, performance monitoring, drift prevention). The framework operationalizes a 12-month governance plan. Its core principle is direct: governance infrastructure must be established before deployment, not retrofitted.

    Singapore’s Ministry of Justice launched a public consultation in September 2025 on a Guide for Using Generative AI in the Legal Sector, mandating a “lawyer in the loop” and verification of all AI output before use. Singapore’s broader public-sector agentic AI framework, analyzed by GovInsider in November 2025, operates from a principle that trust is infrastructure — governance reduces adoption resistance rather than increasing it.

    The CEPEJ 2025 guidelines on generative AI in judicial systems — building on the Council of Europe’s 2018 Ethical Charter — require incremental deployment, pilot phases with evaluation, regular audits, ongoing monitoring, and independent expert certification. These are non-binding recommendations, and compliance tracking is not yet publicly available. But they represent the most detailed international standard for judicial AI governance currently in existence.

    The counterpoint is real but limited. No jurisdiction has published longitudinal data demonstrating that governance-first deployment prevented the legitimacy harm that deployment-first approaches produce. The NCSC framework has not been empirically tested against outcomes. Singapore’s framework is too recent for outcome measurement. The evidence supports the feasibility of pre-deployment governance. It does not yet demonstrate its effectiveness at the institutional trust level.

    Chart illustrating the mathematical impossibility of simultaneous algorithmic fairness criteria

    The Perception Problem: Judicial Legitimacy Is Not Outcome-Neutral

    A 2025 peer-reviewed study published in PubMed Central examined public perception of judges’ use of AI tools in bail and sentencing decisions. Using an experimental survey design grounded in Tyler’s (2006) procedural justice framework, the study found that AI tools affect public perception of procedural fairness and judicial legitimacy — even when the outcomes are equivalent.

    The finding is direct: AI in judicial decision-making is not perception-neutral. The process by which AI is used materially affects whether the public attributes legitimacy to the resulting decision. The authors concluded that failure to implement ethical guidelines, regulations, and monitoring systems for AI threatens perceived procedural justice and produces legitimacy loss.

    Citation reflects reported judicial practice. Verify with primary case law databases for specific authority.

    This creates a compounding problem. Deployment without oversight produces opacity. Opacity reduces perceived procedural fairness. Reduced fairness perception erodes institutional legitimacy. And legitimacy erosion, once established in public perception of a court system, does not reverse when the governance framework is eventually built. The damage is structurally cumulative. It is not retroactively correctable.

    What a Minimum AI Governance Readiness Standard Requires

    The evidence supports a specific institutional response: international judicial standards bodies — the CEPEJ, the International Association for Court Administration, relevant UN bodies — should establish a minimum AI governance readiness checklist that must be satisfied before any AI system is operationalized in judicial decision-support functions.

    Based on the evidence reviewed, that checklist must address at minimum:

    • External audit requirement — no judicial AI system deployed without independent technical review by a body with no commercial relationship to the provider (addressing the Stimson Center’s accountability deficit and the EU AI Act’s provider-side conformity assessment gap)
    • Bias disclosure protocol — mandatory disclosure to affected parties of known algorithmic fairness trade-offs, including which fairness criterion was selected and which was sacrificed (addressing the Chouldechova impossibility constraint)
    • Human override architecture — documented mechanism for judicial officers to override AI recommendations, with audit trails capturing override frequency and rationale (addressing human-AI interaction bias)
    • Appellate review pathway — procedural mechanism allowing parties to challenge the AI methodology used in their case, not only the outcome (addressing due process concerns raised in State v. Loomis and the opacity problem)
    • Competency threshold for deploying institutions — minimum technical expertise, independence criteria, and institutional capacity a judicial body must demonstrate before commissioning AI deployment (addressing the EU AI Act’s classification-without-competency gap)
    • Periodic re-evaluation mandate — scheduled external re-audit, not only at deployment but at defined intervals, to detect model drift, data staleness, and changing baseline conditions

    The absence of any of these elements does not merely increase risk. It creates a governance vacuum that normalizes opacity before detection mechanisms exist — the structural failure pattern this analysis documents.

    Conclusion

    The structural legitimacy risk of judicial AI is not that the technology fails. It is that the technology is deployed into institutions that lack the architecture to know when it fails.

    The Stimson Center’s four bias vectors, Pakistan’s directive without guidelines, Canada’s hallucination sanctions, the EU AI Act’s classification without competency standards, and the mathematical impossibility of simultaneous fairness criteria all converge on a single finding: deployment speed consistently exceeds oversight readiness. That gap is not a temporary inefficiency to be corrected by catching up. It is a structural failure that produces cumulative, difficult-to-reverse legitimacy damage.

    International judicial standards bodies have the institutional authority to establish minimum AI judicial oversight requirements. The CEPEJ 2025 guidelines provide the closest existing template. The NCSC framework operationalizes the pre-deployment governance principle for U.S. state courts. Neither has been empirically validated at scale. But the alternative — continued deployment into governance vacuums — has an evidence base. COMPAS demonstrated it. Canada’s sanction escalation documents it. Pakistan’s unfulfilled directive illustrates it.

    A minimum readiness checklist is not a barrier to efficiency gains. It is the prerequisite for those gains to be exercised without dismantling the institutional legitimacy that makes judicial authority possible.


    About VeritasJPS

    VeritasJPS provides evidence-based research and advisory at the intersection of jurisprudence, behavioral science, and institutional governance. Our work supports institutional decision-makers — judges, policymakers, and compliance leaders — with rigorous analysis grounded in empirical evidence and legal scholarship.
    Learn more:

  • When Judicial Reform Mandates Die at Implementation: Structural Friction in Self-Governance Bodies

    When Judicial Reform Mandates Die at Implementation: Structural Friction in Self-Governance Bodies

    Abstract

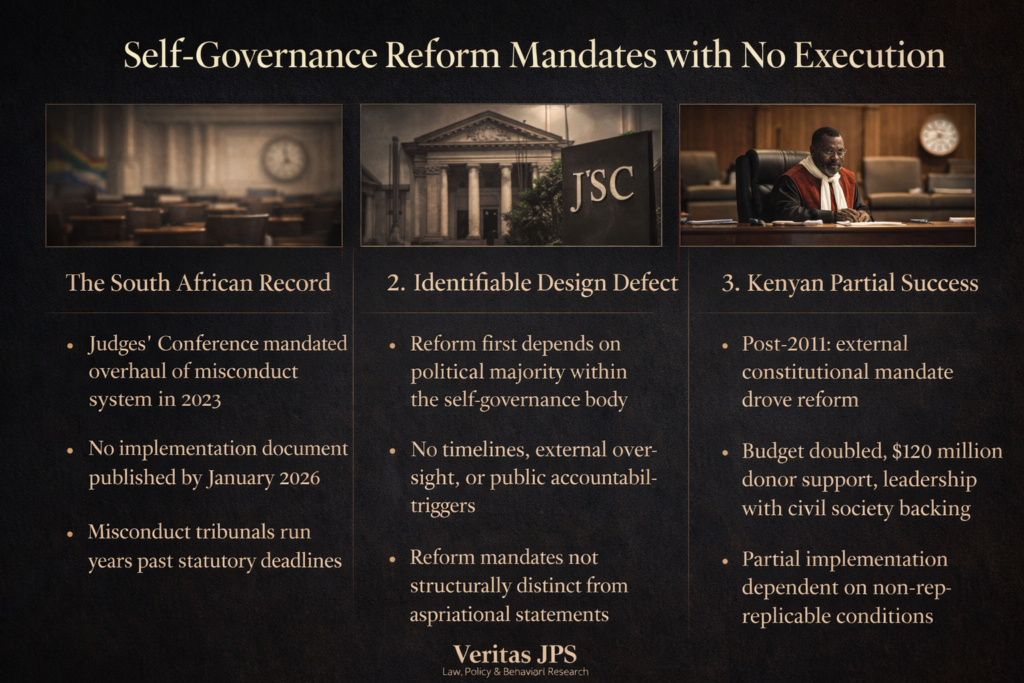
    Judicial reform mandates are routinely issued — and routinely fail at implementation. South Africa’s 2023 Judges’ Conference directed a complete overhaul of the judicial misconduct system. By January 2026, no implementation document had been released. This is not an isolated failure. The Parker misconduct complaint ran nearly six years from filing to determination. The Maumela Tribunal entered its fourth year without producing findings — against a three-month statutory reporting deadline. This analysis examines the structural friction inside judicial self-governance bodies that converts judicial reform mandates into multi-year inaction, drawing on South African, Kenyan, and English institutional evidence alongside the Bangalore Principles framework. The central design defect is identifiable: reform mandates issued without mandatory implementation timelines, public accountability triggers, or external monitoring are structurally indistinguishable from aspirational statements. The question is whether judicial governance architecture should treat them differently.

    The South African Record: From Mandate to Silence

    In 2023, the Judges’ Conference — the judiciary’s own deliberative forum — mandated an overhaul of the misconduct system. Chief Justice Maya confirmed that a Code of Judicial Conduct review was underway. By January 2026, as documented by [EXT-LINK: Judges Matter’s institutional review → institutional review], nothing had been made public. No draft code. No implementation timeline. No progress report. A mandate generated by the judiciary’s own conference, directed at its own governance infrastructure, had produced zero public output in over a year.

    The same architecture produced the Parker Tribunal timeline: a complaint filed in March 2020 that reached a JSC gross misconduct determination only in [EXT-LINK: January 2026 → institutional case report]. Nearly six years. The Maumela Tribunal, documented in [EXT-LINK: Judges Matter’s December 2025 review → institutional review], entered its fourth year with hearings still subject to rolling postponements. The statutory deadline for a tribunal finding is three months. Maumela exceeded that by a factor of twelve.

    These are not delays in the ordinary sense. They are the predictable output of a governance architecture that assigns reform responsibility to the bodies that benefit from the status quo, imposes no enforceable timelines, and provides no external trigger when mandates stall.

    Diagram showing how judicial reform mandates stall at implementation inside self-governance bodies

    The Structural Design Defect

    The Helen Suzman Foundation’s [EXT-LINK: analysis of JSC composition → policy report] identifies the architecture that enables this. The JSC has up to fifteen members from political spheres against eight from non-political backgrounds — judiciary, legal profession, academia. No code of conduct governs commissioner behaviour during interviews or deliberations. The JSC does not meet its own annual reporting obligations. Eleven reform proposals catalogued in the HSF report share a single structural feature: none require binding timelines or external enforcement. All depend on JSC self-implementation.

    This is not a South African peculiarity. It is a design feature of judicial self-governance wherever the Bangalore Principles model operates.

    The [EXT-LINK: Bangalore Principles of Judicial Conduct (2002) → international standard] — the nearest thing to a universal normative framework for judicial accountability — establish that the judiciary should assume an active role in strengthening judicial integrity by effecting systemic reforms within its competence. The [EXT-LINK: Commentary → interpretive guidance] confirms: judges are accountable to appropriate institutions established to maintain judicial standards.

    The defect is embedded in the accountability architecture itself. The Principles presuppose that judges will design, constitute, and operate their own accountability institutions. They contain no mechanism for external intervention when those institutions fail to act on their own mandates. The framework is self-referential. When the self-governance body does not implement its own reform mandate, the Principles provide no consequence, no escalation path, no trigger for external review.

    That gap between normative obligation and enforcement architecture is not a bug in the Bangalore framework. It is the framework.

    Comparative Evidence: Kenya’s Partial Reform and Its Conditions

    Kenya’s post-2010 judicial overhaul offers the most instructive comparison — not because it succeeded, but because the conditions under which it partially succeeded are absent from most self-governance contexts.

    Maya Gainer’s [EXT-LINK: Princeton ISS case study (2015) → case study] documents that by 2010, Kenya had accumulated thirteen separate prior reports on judicial reform. None implemented. The explanation was structural: no political will at leadership level, and an institutional culture characterised by unaccountability, distance, hierarchy, opacity — sometimes driven by a self-serving invocation of the principle of independence.

    Post-2011, partial implementation occurred under a specific combination: an external constitutional mandate; a reform-credentialled Chief Justice (Willy Mutunga) with civil society legitimacy; a judiciary budget that doubled from KSh 3.9 billion to KSh 7.5 billion in a single year; $120 million in World Bank support; thirty-eight nationwide workshops designed to build bottom-up ownership.

    Even then, implementation was incomplete. ICT reforms mandated from the centre failed where internal buy-in was absent. The principal-agent problem persisted — central leadership lacked reliable information about what judicial officers around the country were doing. Many reforms remained in early stages four years in. No post-2015 data tracks whether gains survived Mutunga’s departure.

    Two conclusions follow. Voluntary reform implementation can work — under conditions that include external constitutional mandate, dedicated leadership, doubled budget, and substantial donor support. Those conditions are not replicable by institutional design alone. Where they are absent — as in South Africa’s JSC misconduct reform — the default outcome is the one structural friction predicts: indefinite deferral.

    The HMCTS Counter-Case: External Audit Without Enforcement

    England and Wales offer a different lesson. The HMCTS court and tribunals reform programme — £1.3 billion, multi-year — was subject to independent public audit by the [EXT-LINK: National Audit Office → public audit report]. The 2023 report found that after seven years, HMCTS had completed fifty-five percent of reform projects. The 2018 audit had already identified successful delivery as a significant risk. Four years passed between those two findings.

    The HMCTS case involves operational-technical reform, not judicial conduct governance. The relevance is structural: even with external audit monitoring, programme targets were repeatedly revised without enforcement consequence. The NAO could identify underperformance. It could not compel delivery. Scope reductions and timeline extensions proceeded with no binding accountability trigger at intermediate milestones.

    External monitoring without enforceable consequence functions as documentation, not accountability. Publishing a reform mandate creates a record. Publishing an audit of non-implementation creates a better record. Neither creates a mechanism for compelling action.

    Comparison of judicial reform mandates in South Africa, Kenya, England, and Mexico

    The Counterevidence: When Timelines Become Instruments of Capture

    The strongest argument against mandatory implementation timelines comes from Mexico. López Nachón’s [EXT-LINK: analysis in the Yale Journal of International Law (2025) → legal analysis] documents the 2024 constitutional judicial reform — passed in record time without deliberation by state legislatures. Popular election of judges, terms synchronised to presidential electoral cycles.

    Speed-forcing in judicial reform, when controlled by an executive branch with consolidation objectives, becomes an instrument of authoritarian capture. The absence of deliberation — the condition mandatory timelines could create if politically weaponised — is the mechanism by which reform quality deteriorates and institutional legitimacy erodes.

    That is the legitimate constraint on the mandatory timeline thesis. Timelines imposed from outside the judiciary risk the pathology Mexico demonstrates. The [EXT-LINK: American Progress analysis (2024) → policy analysis] adds a secondary qualification: where the only enforcement mechanism is congressional impeachment — a politically prohibitive threshold — mandatory commitments without functional enforcement create compliance theatre.

    These cases qualify the proposal but do not defeat it. Mexico involves externally imposed reform by an executive branch. South Africa’s problem is the reverse: a self-governance body failing to implement its own mandate. The design variable is who controls the timeline and whether deliberation is preserved. Self-binding timelines — where the governance body commits itself to deadlines with public reporting obligations — sit in a different category from externally imposed political compression.

    The Unaddressed Design Variable: Self-Binding Implementation Architecture

    The evidence across jurisdictions converges. Judicial reform mandates issued without implementation architecture are structurally inert. South Africa documents this. Kenya shows the conditions under which it can be partially overcome. HMCTS shows that monitoring without enforcement is insufficient. Mexico shows that externally imposed speed-forcing creates its own pathologies.

    What no jurisdiction has systematically tested is self-binding implementation architecture: a model in which the governance body that issues a reform mandate simultaneously commits to a public implementation timeline, designates a responsible implementation body distinct from the deliberative body, establishes intermediate milestones with public reporting obligations, and triggers automatic external review — not intervention — when milestones are missed.

    This model preserves judicial independence. The governance body sets its own timeline and milestones. It eliminates the structural permission for indefinite deferral — public reporting and automatic external review create reputational and institutional cost for non-implementation. It is distinct from both the Mexico model (externally imposed, no deliberation) and the current Bangalore model (normatively aspirational, no enforcement).

    The [EXT-LINK: Oslo Law Review analysis (2023) → legal scholarship] identifies one reason this model is underexplored: legal frameworks governing judicial accountability focus almost exclusively on institutional independence, structurally underaddressing individual and internal dimensions. Reform mandates that presuppose individual-level compliance — a code of conduct requiring each judge to act in specified ways — cannot be enforced through institutional accountability frameworks alone. Self-binding implementation architecture would need to operate at both levels.

    Institutional Implications

    Five conclusions for institutional decision-makers.

    Judicial reform mandates issued without implementation timelines, designated implementation bodies, and public reporting obligations are structurally equivalent to aspirational statements. The South African record from 2023 to 2026 documents this with precision.

    The Bangalore Principles framework contains a design-level gap. It establishes the normative obligation for self-governance bodies to implement reform but provides no architecture for accountability when they do not. The gap is inherent to the self-referential accountability model.

    External audit without enforcement authority — the HMCTS model — documents non-implementation but does not remedy it. Monitoring creates transparency. Only enforceable timelines create accountability.

    Mandatory timelines imposed by external political actors — the Mexico model — risk authoritarian capture and deliberation collapse. The design challenge is self-binding architecture, not externally imposed deadlines.

    Kenya’s partial success under specific non-replicable conditions demonstrates that voluntary implementation can work but cannot be relied upon as a structural default.

    The structural question is not whether judicial reform mandates should have implementation timelines. The evidence that undated mandates produce indefinite deferral is consistent across jurisdictions. The question is whether judicial governance bodies will adopt self-binding implementation architecture voluntarily — or whether the structural friction documented here will continue to convert conference-level reform mandates into multi-year inaction.


    About VeritasJPS

    VeritasJPS provides evidence-based research and advisory at the intersection of judicial governance, policy design, and institutional accountability. Our work supports institutional decision-makers — judges, policymakers, and compliance leaders — with rigorous analysis grounded in empirical evidence and legal scholarship.
    Learn more:

  • Paper-Compliance Lag: Why UK Corporate Liability Regimes Structurally Fail in Their First Years

    Paper-Compliance Lag: Why UK Corporate Liability Regimes Structurally Fail in Their First Years

    Abstract

    Paper-compliance lag defines the first-year enforcement pattern visible across three successive UK corporate liability regimes — the Bribery Act 2010 (s.7), the Criminal Finances Act 2017 (ss.45–46), and the Economic Crime and Corporate Transparency Act 2023 (s.199, failure to prevent fraud).

    Three successive UK corporate liability regimes — the Bribery Act 2010 (s.7), the Criminal Finances Act 2017 (ss.45–46), and the Economic Crime and Corporate Transparency Act 2023 (s.199, failure to prevent fraud) — share a structurally repeatable enforcement trajectory: legislation passes, guidance follows, organisations adopt paper compliance, and prosecutions arrive years later. The first s.7 corporate conviction took approximately five and a half years. The first prosecution under ss.45–46 took eight. No prosecution has been brought under s.199 since it entered force in September 2025. This paper-compliance lag pattern is not random.. It is produced by identifiable features of legislative design, prosecutorial resourcing, and organisational response — and it is design-predictable. This analysis argues that enforcement agencies should adopt explicit first-year activation protocols for new corporate liability regimes, rather than accepting structural dormancy as an inevitable cost of corporate criminal law.

    The Dormancy-Then-Activation Arc

    Every major UK “failure to prevent” offence has traced the same arc. Legislation receives Royal Assent. The government publishes guidance — typically months after assent, sometimes after commencement. Organisations respond with compliance documentation. Prosecutors accumulate intelligence. Years later, the first case arrives.

    The Bribery Act 2010 entered force in July 2011. The Ministry of Justice published its “adequate procedures” guidance in March 2011 — nine months after Royal Assent but four months before commencement. The first corporate conviction under s.7, Sweett Group PLC, came in February 2016. Five and a half years. Sweett did not rely on the adequate procedures defence — the company admitted its procedures were absent entirely. The penalty was £2.25 million, a fraction of the financial sanctions secured through Deferred Prosecution Agreements over the same period.

    The Criminal Finances Act 2017 (ss.45–46, failure to prevent facilitation of tax evasion) entered force in September 2017. HMRC published guidance that year. The first corporate prosecution — against an accountancy firm in Stockport — arrived in August 2025. Eight years. By autumn 2025, HMRC confirmed 11 live investigations, 27 “opportunities” under review, and 121 further cases reviewed but not proceeded with. Citation reflects reported judicial practice. Verify with primary case law databases for specific authority.

    The ECCTA 2023 failure to prevent fraud offence (s.199) entered force on 1 September 2025 — nearly two years after Royal Assent in October 2023. Government guidance was published in November 2024. As of March 2026, no prosecution has been brought. The dormancy clock is running.

    What Produces the Lag

    Compliance commentary treats early dormancy as incidental — a by-product of case-building timelines and prosecutorial caution. It is structural. Four interlocking mechanisms generate it across all three regimes.

    Guidance publication timing. In each regime, the gap between Royal Assent and usable guidance opens a window of statutory ambiguity. The MoJ’s Bribery Act guidance drew criticism from Transparency International UK for its insufficient clarity on what “adequate procedures” required — a judgment the House of Lords Select Committee on the Bribery Act endorsed in its 2019 post-legislative scrutiny (HL Paper 303). The Committee found guidance to be vague, high-level, and insufficiently prescriptive. The ECCTA guidance, published twelve months before commencement, was framed as giving organisations time to build fraud prevention procedures. That framing is deliberate design. But it replicates the same compliance-signal-without-enforcement dynamic that characterised each predecessor regime.

    Evidential threshold complexity. Each offence imposes a distinct burden that prosecutors must discharge before initiating proceedings. Under ss.45–46 CFA 2017, HMRC must prove that an “associated person” criminally facilitated tax evasion — not merely that the organisation’s controls were deficient. The ratio of 121 cases reviewed but not proceeded with against 11 live investigations tells a clear story: evidential thresholds operate as a structural brake on prosecution volume in the early years, irrespective of political intent.

    Prosecutorial resource allocation. The SFO’s first decade of s.7 enforcement was characterised by a marked preference for Deferred Prosecution Agreements over criminal convictions. Six DPAs secured financial sanctions exceeding £1 billion — dwarfing the £2.25 million criminal penalty in Sweett Group. That preference may reflect strategic prioritisation rather than incapacity. But it means criminal conviction rates are a misleading metric for enforcement activity — and organisations calibrating their compliance investment to conviction risk are reading the wrong signal. Under ECCTA s.199, both the SFO and CPS hold prosecution authority. The SFO’s updated Compliance Programme Guidance (November 2025) addresses evaluation criteria for “reasonable fraud prevention procedures” but publishes no case-initiation targets or priority sequencing for the new offence.

    Organisational paper compliance. This is the most persistent mechanism and the hardest to measure. When organisations respond to new offences by documenting policies rather than changing conduct, the resulting compliance posture is difficult for prosecutors to falsify at investigation stage. Nine months after the Bribery Act’s commencement, an FTI Consulting survey found that 29% of respondents described themselves as “risk takers” prepared to contravene the Act to win business. Twenty per cent were confident they could do so without detection. Citation reflects reported judicial practice. Verify with primary case law databases for specific authority. That gap — between documented compliance and actual behavioural intent — is precisely where enforcement dormancy takes root.

    The 2025 Anti-Corruption Strategy: Signalling Without Sequencing

    The UK Anti-Corruption Strategy 2025, published in December 2025, contains 123 stated commitments. It signals expansion of the Domestic Corruption Unit, deployment of AI to accelerate investigations, appointment of a dedicated coordinator for “professional enablers,” and reform of the AML/CTF supervisory regime toward a single regulator.

    What it does not contain is an explicit enforcement activation timeline for ECCTA s.199. No prosecutorial priority sequencing for new offences. No case-initiation metrics. No acknowledgment of the structural dormancy pattern that has characterised every preceding failure-to-prevent regime.

    The Strategy reads as political signalling — confirming where governmental attention is directed — not as an operational prosecution framework. This is not a deficiency unique to the current government. No UK enforcement strategy has ever published an explicit first-year activation protocol for a new corporate liability offence. The omission spans administrations.

    The Counterargument: Dormancy as Design

    The strongest objection to characterising early enforcement gaps as structural failure is that they reflect appropriate prosecutorial discretion. The OECD’s Phase 4 UK Report (2017) found that the Bribery Act had prompted substantial progress in corporate anti-corruption compliance — organisations were adopting preventive measures even without prosecutions. Citation reflects reported judicial practice. Verify with primary case law databases for specific authority. On this reading, deterrence operates through the threat of prosecution, not its execution. Early dormancy is an acceptable trade-off for culture change.

    The argument has force. It also has limits.

    If the enforcement threat is never activated — or activated only against firms that have already admitted to absent procedures, as in Sweett Group — the deterrence signal degrades. The FTI 2012 data showed a significant minority of organisations discounting enforcement credibility within the first year. Eight years of zero prosecutions under ss.45–46 CFA 2017 is not a deterrence strategy. It is a credibility deficit.

    The further counterargument — that DPAs constitute active enforcement even when criminal convictions are absent — is jurisdictionally specific. DPAs were available for s.7 Bribery Act cases. Their availability for ECCTA s.199 is not yet tested, and the broader offence scope (Schedule 13 fraud offences) may shift the enforcement calculus entirely. Relying on DPA precedent from one regime to predict enforcement patterns in another is an assumption, not an analysis.

    The Cross-Regime Pattern

    The enforcement trajectories across all three regimes are structurally consistent:

    • Bribery Act s.7 (2010): Commencement July 2011. Guidance lag approximately nine months post-Royal Assent. First corporate prosecution five and a half years post-commencement. No published activation timeline.
    • CFA ss.45–46 (2017): Commencement September 2017. Guidance lag approximately six months. First prosecution eight years post-commencement. No published activation timeline.
    • ECCTA s.199 (2023): Commencement September 2025. Guidance lag approximately twelve months post-Royal Assent. No prosecution as of March 2026. No published activation timeline.

    The dormancy period is lengthening. 5.5 years, then 8. Whether this reflects increasing evidential difficulty, declining prosecutorial capacity, or the normalisation of paper-compliance as a prosecution barrier cannot be determined from current data. No study has disaggregated these variables across regimes.

    The Home Office’s Post-Legislative Scrutiny Memorandum for the CFA 2017, published in May 2024 — seven years after commencement — confirmed zero corporate convictions under ss.45–46 at that date. The first prosecution followed four months later. Parliamentary scrutiny did not accelerate enforcement activation.

    What the Evidence Does Not Cover

    Several material gaps constrain this analysis.

    No published survey measures large-organisation compliance adoption rates, board-level engagement, or training uptake in the first six months following ECCTA s.199 commencement. Pre-commencement advisory materials describe what organisations should do. No data establishes what organisations have done. The FTI 2012 survey on Bribery Act adoption is the nearest proxy — but it measured a different offence, in a different enforcement environment, fourteen years ago.

    No causal disaggregation study separates prosecutorial resource constraints, evidential threshold complexity, deliberate DPA-preference strategy, and organisational paper-compliance opacity as independent contributors to the dormancy period. This is the single most significant analytical gap for policymakers considering activation-trigger design.

    Scotland and Northern Ireland enforcement under both CFA ss.45–46 and ECCTA s.199 is not separately documented. Cross-border enforcement consistency remains uncharted.

    No comparative analysis maps UK dormancy patterns against equivalent regimes in other jurisdictions — Australia’s corporate liability reforms, the US FCPA enforcement model, or France’s Sapin II obligations. Whether the UK pattern is exceptional or typical of common law corporate liability design is an open question.

    The Case for First-Year Activation Protocols

    The evidence supports a specific institutional recommendation: enforcement agencies should publish explicit activation protocols covering the first twelve to twenty-four months of new corporate liability offences.

    An activation protocol would not mandate prosecutions within the first year. It would require published metrics — investigation initiation targets, intelligence-gathering benchmarks, sectoral engagement indicators — that signal prosecutorial capacity and intent during the period of highest behavioural uncertainty. The current model, in which guidance is published and enforcement materialises years later, produces a predictable credibility deficit. The compliance industry fills it with paper documentation. The regulated population fills it with rational discounting.

    The SFO Director’s public statement that corporations must “get their house in order or be ready to face investigation” is necessary but insufficient. Statements of intent without published enforcement scheduling replicate the signalling pattern that preceded dormancy in both prior regimes.

    The UK’s 2025 Anti-Corruption Strategy had an opportunity to break this cycle. It did not take it. Whether the ECCTA s.199 enforcement trajectory will replicate the five-to-eight-year dormancy of its predecessors depends on choices that prosecutors have not yet made public — and that the institutional design of UK corporate criminal enforcement does not currently require them to make.


    About VeritasJPS

    VeritasJPS provides evidence-based research and advisory at the intersection of corporate criminal liability, compliance science, and institutional enforcement design. Our work supports institutional decision-makers — general counsels, compliance directors, policymakers, and regulators — with rigorous analysis grounded in empirical evidence and legal scholarship.

    Learn more:

  • The Enforcement Void: How Non-Binding Regulatory Guidance Produces Structural Accountability Gaps

    The Enforcement Void: How Non-Binding Regulatory Guidance Produces Structural Accountability Gaps

    Executive Summary

    Regulatory bodies increasingly rely on non-binding regulatory guidance rather than binding rules to govern high-risk domains — including artificial intelligence in financial services. The assumption is that flexibility encourages innovation while maintaining oversight. The evidence contradicts this.

    Compliance science consistently identifies enforcement credibility, not instrument design, as the variable that determines whether regulated entities change behaviour or produce documentation. The EU AI Act’s phased enforcement (2025–2027) offers a live test: 18 of 27 member states missed the August 2025 deadline to designate national competent authorities. The UK’s Financial Conduct Authority has explicitly declined to introduce AI-specific rules. No binding federal AI framework exists in the United States.

    This analysis examines the structural failure pattern that emerges when non-binding guidance proliferates without enforcement teeth — and what institutional accountability looks like when every jurisdiction’s enforcement architecture is incomplete.

    The Compliance Science Problem: Why Non-Binding Guidance Underperforms

    The question is not whether non-binding regulatory guidance is theoretically sound. The question is whether it produces behavioural change in regulated entities — and the empirical record is uncomfortable.

    Wu, Tse and Zhang (2022) examined how FDA non-binding guidance documents influenced clinical trial endpoint selection. Their finding was blunt: non-binding guidance “imperfectly influences trialist behaviour.” A quantifiable subset of investigators chose alternative endpoints that guidance did not recommend, not because they disagreed with the science, but because the instrument carried no enforcement consequence. The mechanism matters more than the context. When compliance is optional, a predictable percentage of regulated actors treat the option as permission to diverge.

    The pattern is structural, not anecdotal. Van Rooij et al. (2024) synthesised 35 empirical studies on regulatory compliance across the EU, US, and Australia, applying the [EXT-LINK: COM-B (Capability-Opportunity-Motivation-Behaviour) framework → Michie et al. 2011 original framework paper]. Their conclusion cuts directly against the principles-only model: cooperative regulatory approaches without an inspection backstop produced mixed effectiveness. Face-to-face enforcement with consequences — inspections — was the intervention most consistently associated with compliance. Psychological capability, social opportunity, and reflective motivation outperformed physical compliance mechanisms, but only when the enforcement backstop was credible.

    Sah et al. (2024) developed a “compliance continuum” model integrating behavioural economics and neuroscience that isolates the mechanism. Compliance is not binary. Firms comply where enforcement credibility is high and do not comply — or comply incompletely — where it is low. Non-binding regulatory guidance creates what they call a “low-obligation framing” that systematically depresses compliance motivation in firms with weaker ethical commitments. The implication is structural: guidance without enforcement self-selects for non-compliance among exactly the actors regulators most need to reach.

    Timeline of EU AI Act enforcement deadlines and member state designation status 2025 to 2027

    Principles-Based Regulation: The Historical Lesson

    The binding-versus-principles debate is not new. Julia Black’s landmark analysis (2010) of the UK Financial Services Authority’s principles-based regime from 2001 to 2009 identified four rationales for PBR adoption: effectiveness, durability, efficiency, and ethical outcomes. Each rationale held — but only contingently. When the FSA exercised enforcement discretion credibly, [LINK: principles-based regulation → /principles-based-regulation or equivalent cornerstone] delivered lower compliance costs and comparable outcome quality. When it did not, the regime drifted.

    Then 2008 happened. The failure was not in the principles themselves. It was in the enforcement architecture that surrounded them. Black’s analysis distinguishes between instrument design and institutional will — a distinction the current AI governance debate consistently fails to make. A principles-based framework backed by credible enforcement can outperform a prescriptive regime. A principles-based framework without it produces regulatory drift. That drift is predictable, not accidental.

    Proponents of principles-based AI governance frequently cite the theoretical advantages of non-binding regulatory guidance without accounting for the enforcement precondition. The FSA’s experience demonstrates that the precondition is not optional.

    The Counterargument: When Binding Rules Fail

    The structural critique cuts both directions. The ESRB Advisory Scientific Committee (2019) examined EU financial regulation post-2008 — the regime that replaced principles-based approaches with detailed prescriptive rules. Their finding directly challenges the assumption that binding rules automatically produce better outcomes: prescriptive regulation “undermined rather than enhanced ethical standards, by substituting compliance for values.”

    The evidence is specific. MiFID II, EMIR, and Solvency II generated documented gaming behaviour, regulatory arbitrage, and box-ticking at prevalence levels comparable to — or exceeding — those observed under the prior principles-only regime. The mechanism was regulatory complexity, not regulatory laxity. When rules multiply beyond institutional absorption capacity, organisations optimise for procedural compliance rather than substantive behavioural change.

    This is the regulatory design paradox at the centre of the AI governance challenge. Non-binding regulatory guidance produces compliance gaps because [LINK: enforcement credibility → /enforcement-credibility or equivalent analysis] is absent. Binding prescriptive rules can produce compliance gaps because rule volume exceeds institutional capacity. The failure mode differs. The outcome — accountability without substance — is the same.

    The resolution lies not in choosing between instruments but in designing enforcement architectures that maintain credibility without generating complexity-driven gaming. Neither the EU, UK, nor US approach to AI governance currently achieves this.

    The 2026 Live Case: AI Governance Enforcement Across Three Jurisdictions

    The EU: Binding Rules, Dormant Enforcement

    The EU AI Act (Regulation (EU) 2024/1689) is the most substantial binding AI governance framework globally. It establishes multi-level enforcement: the EU AI Office at the supranational level and national competent authorities at the member state level. The design is structurally sound on paper.

    Operational reality diverges. As of early 2026, only 9 of 27 member states have officially designated national competent authorities. The August 2, 2025 deadline has passed with [EXT-LINK: 18 states in various stages of non-compliance → EU official implementation tracker]. Tracking by Technology’s Legal Edge (November 2025) confirms a further 10 states in pending designation, leaving at least 8 with no public progress.

    The structural gap is specific and measurable. The AI Act mandates enforcement obligations for high-risk AI systems but contains no explicit accountability mechanism for member state enforcement dormancy during the transitional period. Designation is a necessary precondition for enforcement. Without designated authorities, the binding framework produces the same outcome as a non-binding one: no enforcement activity. The instrument changed. The enforcement void persists.

    No public data exists on whether even the 9 designated states have commenced enforcement activity. Designation and operational enforcement capacity are analytically distinct. The record is silent.

    The UK: Principles Without Enforcement Infrastructure

    The UK has taken the opposite path. In September 2025, the FCA reconfirmed its position as a “technology-agnostic, principles-based and outcomes-focused regulator” and explicitly confirmed it will not introduce AI-specific regulations. Governance relies exclusively on existing frameworks: the Consumer Duty and the Senior Managers and Certification Regime (SMCR).

    The theoretical argument is that these existing powers are sufficient — AI is a technology, not a separate regulatory domain, and existing conduct rules already capture the relevant harms. The practical test is whether these powers have been exercised: no AI-specific enforcement action, investigation, or supervisory finding has been recorded under either framework. The FCA’s AI Lab, launched in October 2024, is a testing and collaboration platform — not an enforcement mechanism.

    The UK’s own 2025 Anti-Corruption Strategy inadvertently documents the failure pattern. The strategy introduces no new offences, no new regulators, and no new legislative duties. Its framing is explicitly about “better enforcement, stronger supervision and more coordinated oversight” using existing powers. That is a government acknowledgment — in an adjacent policy domain — that enforcement dormancy is the structural problem, not legislative gaps. Analysts at VinciWorks noted the strategy lacks concrete deadlines, while ICAEW flagged the absence of specific new rules and gaps in enforcement integration.

    The test writes itself. If the UK government recognises that existing powers without enforcement activation constitute a governance failure in anti-corruption, the same structural logic applies to AI governance — where enforcement activation is even less advanced.

    Illustration of regulatory drift from principles-based regulation without enforcement backstop

    The United States: Voluntary Standards Displacing State Rules

    The US presents a third variant. No binding federal AI governance framework exists. Federal governance relies on the NIST AI Risk Management Framework — which is voluntary — and OMB guidance for federal agencies. FTI Consulting (January 2026) describes the result as a “widening regulatory vacuum” being filled by state-level legislation.

    The December 2025 Executive Order on eliminating state AI regulation created an additional structural distortion. Voluntary federal standards now preempt potentially more stringent state binding rules. The mechanism is worth isolating: a non-binding federal framework displaces binding state frameworks, producing a net reduction in enforceable obligations. The enforcement void is not a gap — it is an architectural choice.

    The FSB’s October 2025 report on AI monitoring in financial services confirms the global picture. Financial authorities’ AI monitoring remains at “an early stage.” Data gaps and a lack of standardised taxonomies prevent effective monitoring. No binding monitoring framework exists at the G20 level. Regulators acknowledge they lack the infrastructure to assess whether any AI governance guidance — binding or voluntary — is producing [LINK: behavioural compliance → /behavioural-compliance or equivalent analysis] change.

    The Guidance Dilution Hypothesis

    The evidence reviewed above establishes that non-binding regulatory guidance produces weaker compliance outcomes than binding instruments backed by credible enforcement. A further hypothesis warrants examination: that the proliferation of guidance documents itself reduces compliance salience — that each new guidance instrument diminishes the perceived urgency of all prior instruments in the same domain.

    No peer-reviewed study directly tests this in AI governance. The mechanism draws indirect support from the regulatory fatigue literature. [EXT-LINK: Thomson Reuters’ Cost of Compliance surveys (2014–2015) → Thomson Reuters Cost of Compliance Report] documented that the accumulation of regulatory instruments — binding and non-binding — generates compliance fatigue, fragmented attention, and reduced salience of individual requirements across financial services.

    The ESRB’s 2019 findings reinforce the mechanism from the binding-rules side: prescriptive rule proliferation produces the same attention-dilution effect. Guidance dilution is not unique to non-binding regulatory guidance — it is a feature of instrument proliferation itself. What distinguishes non-binding instruments is their vulnerability: they lack the enforcement signal that maintains salience when attention fragments.

    This remains a hypothesis, not a confirmed finding. No study has isolated guidance frequency or volume as an independent variable predicting compliance rate decline in a specific regulatory domain. That gap matters. It is precisely the mechanism that would explain why the accumulation of AI governance guidance across regulators, international bodies, and industry groups has not produced proportional behavioural change.

    Institutional Implications for Regulatory Enforcement

    The evidence supports three structural conclusions.

    First, enforcement credibility is the decisive variable — not whether the instrument is binding or principles-based. Black (2010) and Van Rooij et al. (2024) converge on this from different methodological traditions. Sah et al. (2024) provide the behavioural mechanism. A principles-based framework with credible enforcement outperforms a prescriptive framework without it. The instrument type matters less than the enforcement architecture surrounding it.

    Second, the EU AI Act’s transitional period (August 2024 – August 2026) represents a known failure window. The regulation establishes binding obligations. It does not establish accountability for the period during which member states fail to designate enforcement authorities. During the transition, a binding framework and a non-binding one produce identical enforcement outcomes: none. Institutional designers should treat this gap as a systemic risk, not an administrative delay.

    Third, the US approach — voluntary federal standards preempting binding state rules — produces a net reduction in enforceable obligations. This is not a principles-versus-rules trade-off. It is a structural choice to reduce enforcement capacity. Institutional oversight bodies should assess whether this architecture creates accountability gaps that no existing enforcement mechanism can close.

    The evidence does not support a simple prescription that binding rules are superior. The ESRB’s findings caution against that conclusion. What the evidence does support is that regulatory architectures without credible enforcement — whether they rely on non-binding regulatory guidance or prescriptive rules — produce predictable compliance failures.

    Those failures concentrate among the regulated entities that pose the highest institutional risk.


    About VeritasJPS

    VeritasJPS provides evidence-based research and advisory at the intersection of regulatory governance, institutional design, and [LINK: behavioural compliance science → /behavioural-compliance-science or equivalent cornerstone]. Our work supports institutional decision-makers — judges, policymakers, and compliance leaders — with rigorous analysis grounded in empirical evidence and legal scholarship.
    Learn more:

  • Witness Credibility Assessment: Courts Still Trust Demeanor

    Witness Credibility Assessment: Courts Still Trust Demeanor

    Abstract

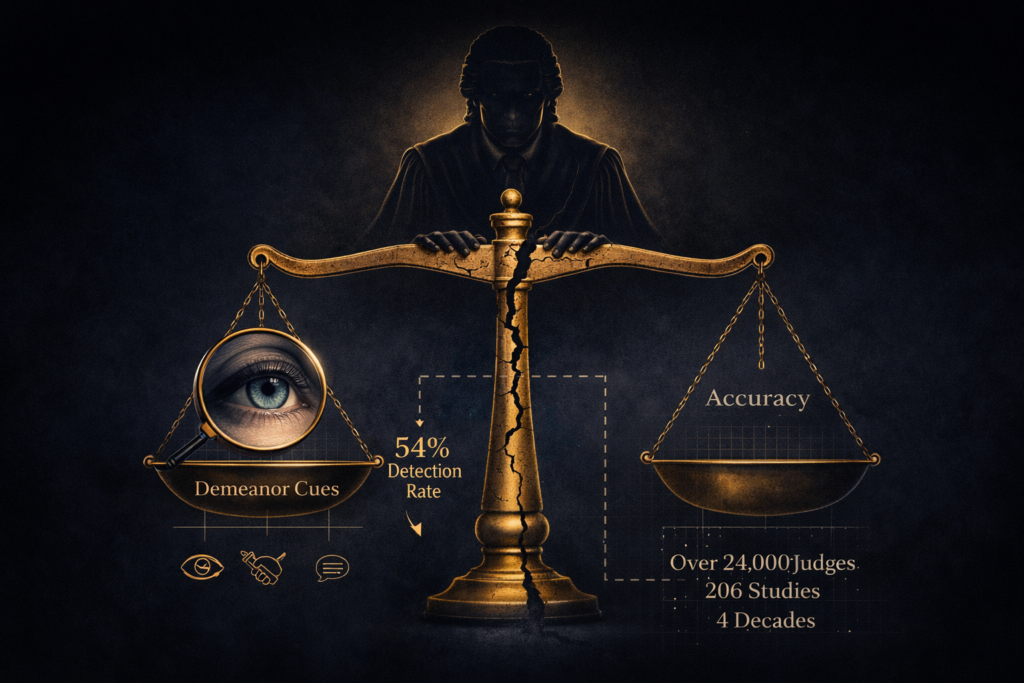
    Witness credibility assessment remains anchored to demeanor observation — the belief that judges can detect deception by watching how witnesses behave on the stand. The empirical record contradicts this belief categorically. Meta-analytic evidence spanning four decades and tens of thousands of judgments places unaided human lie-truth discrimination at 54% accuracy — barely above coin-flip. The behavioral cues courts treat as deception indicators (gaze aversion, fidgeting, speech hesitation) carry near-zero diagnostic value, and professional experience does not improve detection rates. Yet no major jurisdiction has structurally retired demeanor-based credibility assessment from judicial training. This is not a training gap. It is a structural failure sustained by appellate deference doctrine, asymmetric admissibility standards, and a professional culture that rewards confident credibility findings. Comparative data from the Netherlands and Norway confirms that even jurisdictions with strong legal psychology integration continue embedding contested demeanor criteria in judicial reasoning. The question is no longer whether demeanor-based assessment works. It is why the institutions responsible for fact-finding accuracy continue to use a method the evidence has disqualified.

    The Empirical Verdict on Witness Credibility Assessment

    The foundational claim for demeanor-based witness credibility assessment is that experienced adjudicators develop reliable intuitions about witness honesty by observing behaviour. The data rejects this claim.

    Bond and DePaulo’s 2006 meta-analysis, synthesizing 206 studies and over 24,000 judges, established that mean lie-truth discrimination accuracy sits at 54% — with truth identification marginally stronger (61%) than lie detection (47%). Variation between studies was small, pointing to a structural ceiling rather than a sampling artefact. The more damaging finding for demeanor-reliance advocates: accuracy was higher when judges heard statements without visual access to the speaker. The visual channel — the one courts privilege — actively degrades detection performance. [EXT-LINK: Bond and DePaulo’s 2006 meta-analysis → peer-reviewed study]

    DePaulo and colleagues’ 2003 cue-level analysis reinforced this. Examining 158 potential deception indicators across 1,338 estimates, they found that the behavioural cues courts most commonly associate with dishonesty — gaze aversion, fidgeting, speech errors, postural shifts — show near-zero effect sizes. Several operate in the opposite direction from lay belief. Liars speak for shorter periods and include fewer details than truth-tellers, directly contradicting the “over-elaborating liar” model that underpins much judicial intuition about witness behaviour.

    The 54% figure is not contested. It is the baseline from which every subsequent study departs.

    Why Demeanor Evidence Fails as a Deception Signal

    A common institutional defence is that deception detection is simply difficult — the cues too subtle for reliable identification. Hartwig and Bond’s 2011 lens model meta-analysis dismantled this. [EXT-LINK: Hartwig and Bond’s 2011 lens model meta-analysis → peer-reviewed study]

    Applying Brunswik’s lens framework to separate “invalid cue use” from “absent cue” explanations, they showed that lie-catchers fail because they rely on wrong indicators — not because diagnostic information is unavailable. Professional credibility assessors report using cues that have no actual association with deception. The disconnect runs between institutional belief and empirical reality.

    The implication is precise. Judges do not lack training in behavioural observation. The observational framework itself targets the wrong signals.

    Hartwig and Bond’s 2014 follow-up sharpened this. Analysing 144 samples with over 26,000 messages, they found that algorithmic combination of multiple behavioural cues achieves approximately 70% detection accuracy — stable across forensic settings, motivated liars, and demographic variation. But that ceiling applies only to computational extraction. Human judges observing the same data do not approach it. [EXT-LINK: Hartwig and Bond’s 2014 follow-up → peer-reviewed study]

    The diagnostic signal exists. Human cognition cannot reliably extract it through observation. That distinction is the entire case against training-based reform.

    Appellate Deference Locks Demeanor-Based Reasoning in Place

    If the scientific case is this settled, why has no major jurisdiction retired demeanor-based assessment?

    Common law systems grant trial courts substantial deference on credibility findings. The rationale: trial judges see the witness — observe demeanor, tone, composure — and appellate courts, working from transcripts, cannot. This doctrine converts demeanor observation from an evidentiary method into a jurisdictional boundary. Challenging a credibility finding on appeal requires demonstrating that the trial court’s assessment was not merely wrong but unreasonable — a threshold that insulates demeanor-based reasoning from empirical scrutiny. [LINK: appellate deference doctrine → article on standards of appellate review in credibility findings]

    The structural effect is circular. Deference protects demeanor findings from correction. Absence of correction reinforces institutional belief that the method works. Training curricula continue teaching witness observation because no higher court has formally repudiated it. The doctrine that shields the method is the same doctrine that prevents its evaluation within the system.

    Comparative view of judicial credibility assessment in common law and inquisitorial courts

    Why Daubert Does Not Regulate Judicial Credibility Assessment

    A parallel failure operates through evidence admissibility. Under Daubert and its equivalents, expert testimony on witness credibility — forensic psychology evidence about deception cues, memory reliability, suggestibility — must satisfy reliability and relevance gates. Courts assess whether the expert’s methodology meets scientific standards, whether research has been peer-reviewed, whether error rates are known. [LINK: Daubert and its equivalents → explainer on admissibility standards for expert evidence]

    No equivalent gate applies to the judge’s own credibility assessment. A forensic psychologist must demonstrate scientific validity before testifying about witness reliability. The judge evaluating the same witness from the bench faces no such requirement. One adjudicator applies an unvalidated method to the same factual question the other must validate before addressing.

    This asymmetry has no principled justification. Admissibility doctrines were designed to regulate evidence placed before fact-finders, not the cognitive methods fact-finders themselves deploy. The Istanbul Protocol — revised in 2022 — provides structured forensic assessment standards for torture documentation, but its scope remains confined to that evidentiary domain. No equivalent protocol governs civilian witness credibility in domestic courts. [EXT-LINK: Istanbul Protocol — revised in 2022 → UN standard / protocol] [LINK: Istanbul Protocol → article on forensic assessment standards in torture documentation]

    Comparative Evidence From the Netherlands and Norway

    If demeanor-based assessment were merely an Anglo-American common law artefact, the structural failure might be contained. Comparative evidence from inquisitorial systems suggests otherwise.

    Meijer and colleagues’ 2025 study examined Dutch legal professionals on two dimensions: stated credibility criteria (survey, n=79) and criteria appearing in actual court rulings (content analysis, n=518 sexual assault decisions). Content-based factors dominated stated practice — consistency (66%), accuracy (66%), detailedness (53%). But 28% of respondents also named non-verbal behaviour, emotion, or “authentic impression.” In actual rulings, authentic impression surfaced in 21% of decisions, emotionality in 13%, signs of trauma in 9.5%. No validated protocol governed which indicators were applied, how they were weighted, or how conflicts between content and demeanor signals were resolved.

    The Netherlands operates an inquisitorial system with strong legal psychology integration. Contested credibility criteria persist there regardless. The failure is not jurisdiction-specific.

    Bjørndal and colleagues’ 2020 survey of 98 Norwegian judges found no significant aggregate knowledge improvement over a decade — comparing 2019 scores against Magnussen and colleagues’ 2008 baseline. One item shifted dramatically: recognition that witness confidence does not reliably indicate accuracy moved from 31% correct to 78%. But gains on individual items were offset by declines elsewhere, producing flat aggregate scores. Judges grew more sceptical of others’ eyewitness knowledge while their own knowledge base stayed largely unchanged. [LINK: eyewitness knowledge → post on judicial misunderstanding of memory reliability]

    Norway abolished jury trial in 2017, concentrating credibility-assessment responsibility on professional judges. The adjudicators now solely responsible for witness assessment have not, collectively, absorbed the science governing the methods they use.

     witness credibility assessment

    How Scottish Directions Reinforce Demeanor Reliance

    Clark, Keane, and Sheridan’s 2022 study added a procedural dimension from the Scottish adversarial context. Across 863 mock jurors in 64 jury deliberations, demeanor-based reasoning surfaced consistently — even when jurors also applied content-based criteria. Scottish judicial directions explicitly instruct jurors to consider manner of delivery. The directions do not caution against demeanor reliance. They endorse it.

    This is how structural failure self-replicates. Directions are drafted from existing doctrine. Doctrine defers to trial-level demeanor findings. Trial-level practice treats demeanor observation as legitimate. Each layer validates the one below it. The empirical evidence has no formal entry point into this chain.

    Why Training Alone Will Not Fix Witness Credibility Assessment

    Most institutional discussion frames demeanor-reliance as a training gap — fixable by adding a cognitive bias module to judicial education curricula. The diagnosis is wrong.

    The failure persists because institutional incentives actively sustain it. Confident credibility assessments produce clean judicial outcomes. Epistemic humility about witness reliability introduces uncertainty — it complicates decision-making, extends proceedings, may require additional procedural safeguards. Professional rewards flow toward confidence, not calibration.

    Appellate deference amplifies this. A trial judge who states “I found the witness credible based on their demeanor” produces a virtually unreviewable finding. A judge who states “the behavioural evidence was equivocal, and I relied primarily on documentary corroboration” invites closer appellate scrutiny of the documentary record. The system rewards the less epistemically honest assessment.

    Norway’s data confirms it. A decade of published memory science produced no aggregate improvement in judicial knowledge scores. Information transfer without incentive realignment does not change practice.

    What Structural Reform Would Require

    Replacing demeanor-based witness credibility assessment requires intervention at three institutional levels. [LINK: structured assessment frameworks → article on evidence-based judicial decision protocols]

    First, appellate doctrine must permit empirical challenge to demeanor-based credibility findings. Not abandoning deference — but permitting evidence that the assessment method used by the trial court has no scientific validity. The same standard already applied to expert evidence under Daubert.

    Second, judicial training curricula must formally repudiate demeanor observation as a credibility tool and replace it with structured assessment frameworks grounded in validated indicators. The Istanbul Protocol’s approach to forensic assessment in torture documentation provides a methodological template — not direct application, but proof that structured credibility protocols can be institutionalised.

    Third, the professional incentive structure must change. Practice directions requiring judges to articulate which specific evidentiary factors supported credibility findings — and prohibiting reliance on demeanor alone — would create accountability mechanisms that do not currently exist. Reasoned credibility assessments, not conclusory ones, must become the institutional standard.

    No jurisdiction has implemented all three. The question is which moves first — and whether the institutional culture of adjudication can accommodate the epistemic humility that evidence-based credibility assessment demands.


    About VeritasJPS

    VeritasJPS provides evidence-based research and advisory at the intersection of jurisprudence, behavioural science, and institutional governance. Our work supports institutional decision-makers — judges, policymakers, and compliance leaders — with rigorous analysis grounded in empirical evidence and legal scholarship.
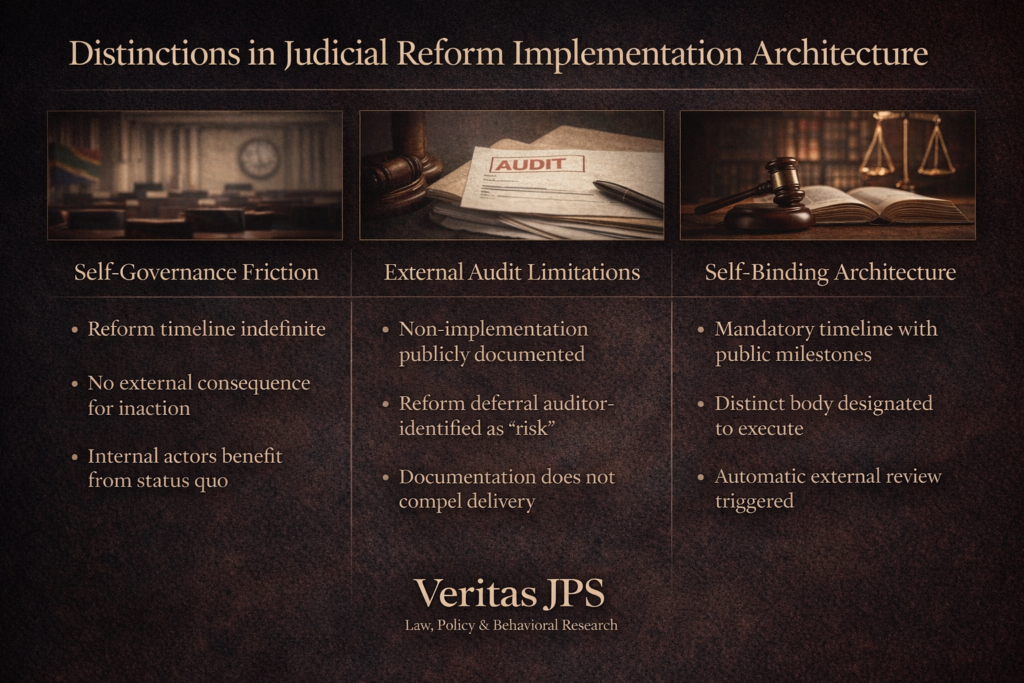
    Learn more:

  • When Lay Certainty Overrides Judicial Doubt: The Structural Failure of Mixed Court Deliberation

    When Lay Certainty Overrides Judicial Doubt: The Structural Failure of Mixed Court Deliberation

    Abstract

    Mixed courts — panels combining professional judges with lay assessors — are a constitutional fixture across Nordic, Germanic, and civil-law jurisdictions. The institutional justification is democratic legitimacy: citizens participate in adjudication as a check on professional insularity. But ethnographic research from Swedish courts, published in late 2024, documents a failure mode that no judicial council protocol currently addresses. When professional judges express uncertainty during deliberation and lay judges enter with confident pre-formed positions, the deliberation does not correct toward accuracy. It cascades toward the confident voice. The mechanism is not individual incompetence. It is structural: deliberation architectures that treat all expressions of certainty as equal input cannot distinguish between legally trained doubt and lay conviction. This article examines the evidence across five jurisdictions — Sweden, Germany, France, Japan, and the Netherlands — and argues that the absence of deliberation sequencing protocols in mixed panels constitutes an undiagnosed design defect in judicial institutions that claim to value both democratic participation and verdict accuracy.

    The Cascade Mechanism: What the Swedish Evidence Shows

    The clearest documentation of how lay certainty displaces professional judicial reasoning comes from Bergman Blix and Törnqvist’s 2024 ethnographic study of Swedish district and appellate courts. The researchers observed deliberations across more than seventy criminal cases — homicide, fraud, domestic abuse — with access to judicial chambers that is exceptionally rare in comparative legal research. Their method combined direct observation, shadowing, and semi-structured interviews with forty-seven judges across both court levels.

    The finding that matters is not that lay judges sometimes disagree with professionals. Disagreement is the point of mixed panels. What matters is the form in which a professional judge expresses uncertainty — and whether that form produces collaborative reasoning or collapses into confidence-driven dominance.

    In one documented case — a domestic assault involving intoxication — the presiding judge expressed what the researchers term “undelimited uncertainty”: doubt not anchored to a specific legal question, radiating outward as general hesitation about the evidence. A lay judge who had displayed pre-formed confidence from the outset (no notes taken, arms folded throughout the trial) seized deliberative control. The deliberation shifted from evidentiary analysis to moral evaluation entirely detached from the applicable legal standard. The professional judge did not lose the argument. She lost the frame.

    The contrast case matters. In a separate assault prosecution, the presiding judge expressed “delimited uncertainty” — doubt focused on a discrete legal question (whether the evidence met the threshold for a specific intent element). That bounded expression produced exactly the collaborative exchange mixed panels are designed to generate: lay judges contributed factual perspectives, the presiding judge retained analytical authority, and the panel reached a reasoned verdict.

    Undelimited uncertainty triggers status degradation. Delimited uncertainty enables productive collaboration. No current judicial training programme or court protocol makes this distinction explicit.

    Why This Is Not a Training Problem

    The instinctive institutional response to deliberation failures is retraining. If judges lose control of deliberations, the assumed remedy is better communication skills. Bergman Blix’s earlier theoretical work (2022) demonstrates why that framing misdiagnoses the problem.

    Professional judges enter mixed panels carrying what Bergman Blix describes as “constrained generalised trust” toward lay assessors — formally obligated to treat them as equals, while privately sceptical of their competence. This structural ambivalence is not a personality defect. It is a rational response to institutional design: the judge knows the assessors have no legal training, yet the rules require treating their input as equivalent.

    Uncertainty expression becomes structurally dangerous. Revealing doubt risks confirming lay judges’ latent suspicion that the presiding judge is unsure — which, in the Swedish ethnographic data, triggers exactly the status inversion that degrades verdict quality. Training judges to “communicate uncertainty better” does not resolve this. It sharpens the vulnerability. The more openly a judge expresses doubt in an architecture that rewards confidence, the more exposed she becomes to displacement.

    The German and French Evidence: Passivity as the Mirror Failure

    The Swedish evidence documents the active failure mode — lay certainty overriding professional doubt. German and French evidence documents the passive counterpart: lay judges so marginalised by professional dominance that their participation becomes ceremonial.

    Machura’s survey of German Schöffen courts (2011), drawing on questionnaire data from approximately 469 lay assessors across Bochum and Frankfurt, found that professional judges in high-caseload courts routinely bypassed lay participation — compressing hearing and deliberation time, reaching agreements with parties without consulting assessors. Lay judges’ deliberation behaviour was heavily mediated by power-distance orientation: those who believe authority figures should not be questioned participated least. The legitimacy-generating function that justifies the system — informing the wider community about judicial reasoning — largely fails. Most Schöffen do not communicate their experience to others.

    Rennig’s 1993 analysis of Schöffen deliberation dynamics records an asymmetric persuasion pattern: a lay assessor in the minority is readily persuaded by the majority, while a professional judge in the minority retains capacity to persuade lay assessors. Formally equal. Epistemically asymmetric.

    Philippe’s quasi-experimental study of French courts (2017) provides the strongest causal evidence in this evidence base, though it points in a different direction. A 2011 law introduced two lay jurors into courts of three professional judges for specific offence categories in two appellate jurisdictions. The study analysed approximately 597,000 individual case observations using difference-in-differences and triple-difference regressions. No detectable change in conviction rates, imprisonment probability, sentence length, or sentence dispersion. The official evaluation report recorded that the jurors deferred entirely to professional judges.

    This null result does not refute the cascade hypothesis. It documents the opposite failure condition. The French jurors were numerically outweighed (two against three professionals), did not receive investigation files in advance, and did not lead deliberation. They were structurally positioned for passivity. The Swedish evidence, where lay judges hold majority voting weight at the district court level, shows what happens when those structural conditions reverse.

    The Group Dynamics Literature: Why Mixed Panels Are Vulnerable

    The deliberation failures documented in Sweden and Germany are not unique to judicial settings. Sunstein’s synthesis of the group polarisation literature (2004) identifies three mechanisms that operate in any deliberating body, including judicial panels:

    • Informational cascades: Early, confident speakers establish a dominant framing. Later speakers defer to apparent certainty rather than contributing independent analysis. In mixed panels, lay judges who arrive with confident pre-formed positions function as early anchors.
    • Reputational cascades: Members suppress dissenting views to avoid disapproval. Professional judges constrained by norms of collegiality and respect for democratic participation are structurally positioned to absorb rather than challenge lay confidence.
    • Group polarisation: Deliberating groups end in positions more extreme than the pre-deliberation individual mean. Where lay judges’ pre-deliberation positions are more punitive or morally charged than the legal standard warrants, polarisation amplifies that divergence.

    Sunstein acknowledges that some deliberating groups outperform individual decision-makers — but only under specific structural conditions: genuinely diverse composition, explicit counter-argument protocols, and active surfacing of unshared information. These are design features. They demand architectural intervention, not exhortation.

    The Counterevidence: Democratic Legitimacy and Net Positive Outcomes

    The structural critique must be weighed against the institutional benefits. Marder’s 2024 comparative review in the Annual Review of Law and Social Sciences concludes that lay participation strengthens fact-finding through community knowledge exchange, increases the perceived legitimacy of outcomes, and promotes democratic governance. Mixed courts have the capacity to test interpretations of evidence through perspectives that professional judges alone cannot access.

    This is not a minor consideration. Judicial systems without democratic participation mechanisms face different legitimacy risks — insularity, detachment from community norms, the appearance of technocratic self-governance. The question is not whether lay participation has value. It does. The question is whether that value can be preserved while addressing the specific failure mode the Swedish ethnographic evidence documents.

    Japan’s saiban-in system offers a partial model. Since 2009, panels of three professional judges and six lay judges have adjudicated serious criminal cases. Research on the system’s first fifteen years documents sustained public legitimacy and instances of genuine collaborative decision-making. The design is instructive: professional judges lead evidence framing, deliberation is structured, and the lay majority is by number but not by institutional authority. Whether this architectural compromise successfully interrupts the epistemic cascade documented in Swedish courts remains empirically unresolved — direct deliberation process data from saiban-in proceedings is limited in the English-language literature.

    The Missing Protocol: Deliberation Sequencing as Institutional Design

    Only one jurisdiction in the evidence base has produced explicit guidance addressing the epistemic hierarchy problem in panel deliberations. The Netherlands Council for the Judiciary’s Professional Standards for three-judge decision-making directly identifies the “production block” effect — when one member speaks, others’ independent reasoning is suppressed — and prescribes a response: the presiding judge speaks last, less experienced members speak first, and a devil’s advocate role is explicitly recommended.

    This protocol applies to professional-only panels. It does not address mixed professional-lay interaction. But the underlying principle — that who speaks when determines the quality of collective reasoning — is exactly what the Swedish evidence demonstrates for mixed courts.

    No equivalent protocol exists anywhere for mixed professional-lay panels. The Bangalore Principles address individual judicial conduct — impartiality, integrity, competence — not the collective epistemic dynamics of panel deliberation. The UN Basic Principles on the Independence of the Judiciary address structural independence, not deliberation architecture. European judicial council guidance addresses lay assessor selection, training, and terms of service. None of it addresses the sequencing of uncertainty expression that determines whether lay participation improves or degrades deliberative quality.

    Implications for Institutional Design

    The evidence points toward specific architectural intervention, not a general recommendation for “better deliberation.”

    Deliberation protocols in mixed courts should formally distinguish between delimited and undelimited uncertainty expression. The Swedish evidence demonstrates that the form of judicial doubt — not its presence — determines whether deliberation cascades. Professional judges need structural permission to express bounded uncertainty without risking status degradation.

    Sequencing protocols that require professional judges to speak after lay assessors on factual matters — and before them on legal standards — would interrupt the confidence cascade at its activation point. The Netherlands protocol demonstrates this is institutionally feasible for professional panels. Extending it to mixed panels requires no new theory. Only adaptation.

    The passive failure mode documented in Germany and France — lay judges who participate ceremonially — deserves equal institutional attention. Deliberation architectures that produce either active displacement or passive marginalisation are failing the same design test from opposite directions.

    The gap in outcome data is itself an institutional failure. No jurisdiction has linked specific deliberation process dynamics to measurable verdict quality metrics — appeal rates, reversal rates, sentence consistency. Until that evidence exists, the cascade mechanism is documented at the process level but not confirmed at the outcome level. Judicial councils designing deliberation reforms should build evaluation into the protocol from inception.

    The democratic legitimacy of lay participation is not in question. What is in question is whether judicial institutions can design deliberation architectures that extract the democratic benefits of lay participation while structurally interrupting the epistemic cascades that degrade professional judicial reasoning. The evidence says the problem is architectural. The remedy should be too.


    About VeritasJPS

    VeritasJPS provides evidence-based research and advisory at the intersection of jurisprudence, behavioural science, and institutional governance. Our work supports institutional decision-makers — judges, policymakers, and compliance leaders — with rigorous analysis grounded in empirical evidence and legal scholarship.
    Learn more:

  • Constitutional Redesign as the Structural Mechanism for Judicial Delegitimization: Pakistan, Hungary, Poland, and the International Standards Gap

    Constitutional Redesign as the Structural Mechanism for Judicial Delegitimization: Pakistan, Hungary, Poland, and the International Standards Gap

    Abstract

    Constitutional amendment — not military coup, not executive decree — has become a dominant contemporary instrument for dismantling judicial independence across democracies with weak insulation mechanisms. Pakistan’s 26th Constitutional Amendment (2024) and 27th Constitutional Amendment (2025) represent the most structurally complete recent execution of this pattern, transferring apex court jurisdiction to an executive-appointed Federal Constitutional Court. Parallel trajectories in Hungary, Poland, and Indonesia confirm a replicable escalation sequence: appointment capture, composition shift, jurisdictional transfer. The UN Basic Principles on the Independence of the Judiciary (1985) and the Bangalore Principles of Judicial Conduct (2002) — the two primary international instruments governing judicial independence — were designed to protect individual judges, not court architectures. They contain no provisions addressing structural court bifurcation, minimum procedural thresholds for constitutional amendments restructuring courts, or jurisdictional transfer as a delegitimization vector. This gap leaves constitutional redesign as a fully documented but underregulated pathway to institutional collapse.

    The Pattern: Amendment as an Insulation-Bypassing Tool

    The conventional account of judicial independence threats centres on dramatic ruptures — military coups, emergency decrees, the outright abolition of courts. That account is outdated. The dominant mechanism now operates inside constitutional frameworks, exploiting the ordinary amendment process to reconstruct courts in ways that strip the institutional preconditions for independence before any individual judge is touched.

    The logic is structural, not personal. Four mechanisms should be distinguished at the outset. Court-packing changes who decides by altering appointments or bench composition. Jurisdiction-stripping changes what an existing court is allowed to decide by removing categories of cases from its reach. Court bifurcation creates a parallel judicial body and reallocates core constitutional functions to it. Apex replacement is the terminal form of the sequence: the formal supreme court remains, but a newly created body becomes the effective final constitutional authority. These mechanisms can occur separately, but in contemporary democratic backsliding they often appear sequentially.

    Court-packing through appointment control shifts the composition of a bench. Court bifurcation goes further: it manufactures an entirely new apex body, transfers constitutional jurisdiction to it, and subordinates the original court — all through amendments that satisfy formal procedural requirements. The existing court retains its name but loses its function. The legitimacy question shifts from “Did the court decide correctly?” to “Does the court still exist in any meaningful operational sense?”

    Across jurisdictions, the pattern holds, though not in identical doctrinal form. What is shared is not institutional identity but structural logic: formal legal redesign used to neutralize courts without formally abolishing them. V-Dem data across Hungary and Poland documents measurable judicial independence erosion following amendment-based restructuring. Indonesia’s Constitutional Court has faced parallel regression through formal instruments, as documented in a 2024 three-country comparison examining court-packing across post-democratic-transition systems. The sequence is consistent: appointment control leads to composition capture, which enables jurisdictional subordination.

    Pakistan: The 26th Amendment (2024)

    Pakistan’s 26th Constitutional Amendment, passed on October 20–21, 2024, overhauled the judicial appointment and tenure architecture of the Supreme Court through ordinary parliamentary majority. Three changes matter.

    First, the Chief Justice of Pakistan is no longer the most senior judge by automatic succession. A Special Parliamentary Committee — eight members from the National Assembly, four from the Senate — now nominates the CJP from the three most senior judges. The government commands a built-in majority on that committee.

    Second, the Judicial Commission of Pakistan was recomposed. Political members — the law minister, attorney general, and parliamentary nominees — now outnumber judicial members on appointment decisions.

    Third, a Constitutional Bench was created within the Supreme Court, carrying exclusive suo motu and advisory jurisdiction. A court within a court, with its own presiding judge nominated by the reconstituted JCP. The bench exercises the most constitutionally sensitive work — the kind that tests executive power — under an appointment architecture in which the executive holds the deciding vote.

    The International Commission of Jurists assessed this as a blow to judicial independence, citing the UN Basic Principles requirement that appointing bodies remain independent of executive control.

    Pakistan: The 27th Amendment (2025) — Court Bifurcation as the Endgame

    The 27th Constitutional Amendment, passed in November 2025, completed what the 26th began. Where the 26th captured appointments, the 27th captured jurisdiction.

    The amendment established a Federal Constitutional Court as a new apex body with exclusive authority over constitutional interpretation, federal-provincial disputes, fundamental rights enforcement, and any substantial question of law involving constitutional interpretation. FCC judgments bind all courts, including the Supreme Court. The Supreme Court was reduced to a non-constitutional appellate body — retaining its name, losing its constitutional role.

    The appointment mechanism for the FCC’s inaugural bench was stripped bare. The first Chief Justice and first batch of judges are appointed by the President on the advice of the Prime Minister. No selection criteria. No transparency requirement. No judicial-body consent. Subsequent appointments run through the JCP and Special Parliamentary Committee — the same bodies already captured by the 26th Amendment, in which judicial members hold a 5-of-13 minority.

    The circularity is documented and deliberate. The 27th Amendment designates the FCC itself as the forum for challenges to its own constitutionality. Court officials refused to accept petitions contesting the amendment. A body created by executive appointment adjudicates challenges to its own creation — a design that forecloses external review by definition.

    Additional provisions reinforced the shift. High Court judges can be forcibly transferred without consent; refusal within 30 days triggers disciplinary proceedings and a bar from judicial functions. Lifetime criminal immunity was extended to the President and to the holder of the Field Marshal rank — currently the Chief of Army Staff.

    The ICJ’s Secretary-General described the 27th Amendment as “dismantling justice” and “a full-frontal assault on the rule of law,” invoking UN Basic Principles 10, 12, 14, 18, and 19: the requirement that appointing bodies be independent, that objective criteria govern selection, and that removal occur only for serious misconduct through appropriate procedure.

    The Escalation Sequence: Replicable Preconditions Across Jurisdictions

    Pakistan’s 26th-to-27th trajectory is not improvised. It mirrors a documented escalation observable across jurisdictions.

    Stage 1 — Appointment capture. The executive gains effective control over who sits on the bench. In Hungary, Fidesz’s constitutional supermajority restructured the nomination process after 2010. In Poland, PiS used its parliamentary majority to alter the composition of the Constitutional Tribunal from 2015. In Pakistan, the 26th Amendment achieved this through JCP recomposition and the Special Parliamentary Committee.

    Stage 2 — Jurisdictional transfer. Once composition is controlled, jurisdiction gets redirected. Pakistan’s Constitutional Bench (26th Amendment) and then the FCC (27th Amendment) are the clearest recent examples — but the pattern echoes Hungary’s creation of the Kúria as the new supreme court body and the subsequent establishment of administrative courts designed to handle politically sensitive cases.

    Stage 3 — Structural insulation of the new architecture. The reformed body is made self-referential: challenges to its constitutionality route through itself. Pakistan’s 27th Amendment is the most explicit contemporary example, but the principle holds wherever the new court controls the forum for reviewing its own validity.

    A synthetic control study of Hungary and Poland published in the Journal of European Public Policy found a counterintuitive result: Hungary’s formal constitutional redesign — conducted through a supermajority — eroded judicial independence more severely than Poland’s explicit court-packing through simple majority. Hungary’s V-Dem rule-of-law index dropped from 0.89 to 0.71; Poland’s from 0.96 to 0.83 over the 2009–2019 window. Formal process did not legitimize the change. It may have insulated it from challenge. Citation reflects reported judicial practice. Verify with primary case law databases for specific authority.

    What Enables the Pattern: Bilateral Preconditions

    The structural-attack narrative — governments dismantling independent courts — is incomplete. Kureshi (2025), writing in Government and Opposition, identifies a bilateral precondition: judiciaries that adopt what he terms a “representation-replacement approach” — treating themselves as more representative than elected institutions — create the political conditions for structural dismantling. When courts appropriate executive and legislative functions, they hand populist governments rhetorical cover for counter-restructuring.

    This does not excuse constitutional capture. It exposes a second vulnerability: the pattern is not solely about executive overreach but also about institutional overextension by courts themselves. Pakistan’s Supreme Court had, in the decades preceding the 26th Amendment, expanded its reach into territory conventionally occupied by elected branches — a trajectory that Pakistan’s legislative actors subsequently cited as justification for rewriting the rules.

    Separately, Aydin-Cakir and Akarçay (2025) document in the International Review of Law and Economics that verbal government attacks on the judiciary intensify as political corruption rises, specifically in countries with independent media. The mechanism is exposure avoidance: governments go after courts when courts threaten to expose corruption. While this study addresses verbal confrontation rather than structural redesign, it identifies the upstream trigger — corruption-driven accountability avoidance — that precedes the escalation to constitutional amendment.

    The Legitimacy Consequence: What the Evidence Measures

    Gibson’s body of work on judicial legitimacy — the most extensive empirical programme on the subject — supplies the theoretical framework for understanding what constitutional redesign destroys. His 2024 analysis in Science Advances found that the U.S. Supreme Court’s post-Dobbs legitimacy impact may have been the largest documented blow to court legitimacy, with approval polarizing along partisan lines for the first time in decades. His 2025 follow-up in the Annals of the American Academy of Political and Social Science tracked whether those effects persisted — and found evidence they did.

    The critical distinction is between decision-based erosion and structural erosion. Gibson’s work measures legitimacy shifts after controversial rulings — a court that exists and functions but decides unpopularly. Constitutional redesign operates on a different plane. It removes the institutional conditions for diffuse support before any individual ruling can be contested. When Pakistan’s 27th Amendment transferred constitutional jurisdiction to a body appointed by the Prime Minister, the question was no longer “Did the court get it right?” but “Is there a court capable of getting it right at all?”

    Gibson’s own positivity theory — that courts enjoy deep reservoirs of goodwill and institutional loyalty is substantially resilient — provides a partial counterweight. But the theory was developed and tested in the U.S. context, where institutional legitimacy reserves run deep. Whether positivity theory holds in younger democracies with shallower reserves — Pakistan, Hungary, Indonesia — is empirically untested at the structural-redesign level.

    The International Standards Gap

    The two primary international instruments governing judicial independence — the UN Basic Principles on the Independence of the Judiciary (1985) and the Bangalore Principles of Judicial Conduct (2002) — were designed for a different threat model.

    The UN Basic Principles address what can be done to individual judges: Principle 10 governs appointment integrity, Principle 12 secures tenure, Principle 14 protects case assignment, Principle 18 restricts removal. The Bangalore Principles address how judges should conduct themselves: independence, impartiality, integrity, propriety, equality, competence.

    Neither instrument addresses what can be done to courts as institutions. No provision governs structural court bifurcation — the creation of a parallel apex body that displaces an existing court’s jurisdiction. No minimum procedural threshold exists for constitutional amendments that restructure court systems: no requirement for a supermajority, a referendum, or judicial-body consent. No prohibition covers jurisdictional transfer as a mechanism for reducing a court’s scope without formally abolishing it. No standard addresses composite appointment bodies in which judges hold a permanent minority.

    By invoking these instruments against Pakistan’s 27th Amendment, the ICJ exposes their limits. The ICJ can point to principles governing appointment criteria and judge-level conduct. It cannot point to any binding standard that prohibits what Pakistan did: creating a new court, transferring constitutional jurisdiction to it, and appointing its judges without institutional constraint. The instruments were written to protect judges. The threat has moved to court architectures.

    Whether the insulation question — should judicial appointment frameworks be shielded from ordinary legislative amendment? — can be answered through international standard reform remains unclear. León (2024), writing in Global Constitutionalism, examines supermajority rules in judicial decision-making — but no retrieved study evaluates whether requiring supermajority or referendum approval for court-restructuring amendments produces measurably higher judicial independence or legitimacy scores. The design question is real. The evidence base for answering it does not yet exist.

    What This Means for Institutional Decision-Makers

    Five implications follow.

    First, the threat model for judicial independence must expand beyond individual-judge protections. Court bifurcation — creating new bodies that absorb constitutional jurisdiction — is a distinct attack vector that existing international instruments do not cover.

    Second, the escalation from appointment capture to jurisdictional transfer to self-referential insulation is a documented sequence, not a theoretical construct. Monitoring systems that fixate on appointment processes alone will miss the later stages until they are constitutionally entrenched.

    Third, formal constitutional procedure does not legitimate structural dismantling. The Hungary-Poland comparison suggests that constitutional-supermajority redesign may produce deeper independence erosion than simple-majority court-packing — because it is harder to challenge and carries the procedural imprimatur of constitutional legitimacy.

    Fourth, bilateral preconditions matter. Judicial overextension — courts appropriating executive or legislative functions — creates the political conditions for counter-restructuring. Institutional self-restraint is not weakness; it is structural defence.

    Fifth, the absence of empirical measurement is itself a governance failure. No public-opinion instrument has been deployed to measure diffuse support for judicial institutions before and after constitutional court bifurcation in any of the affected jurisdictions. The legitimacy consequences of Pakistan’s amendments, Hungary’s Kúria restructuring, and Indonesia’s Constitutional Court regression are inferred from structural analysis and expert assessment — not from population-level data. That gap must close before evidence-based institutional design can proceed.


    About VeritasJPS

    VeritasJPS provides evidence-based research and advisory at the intersection of jurisprudence, behavioural science, and institutional governance. Our work supports institutional decision-makers — judges, policymakers, and compliance leaders — with rigorous analysis grounded in empirical evidence and legal scholarship.
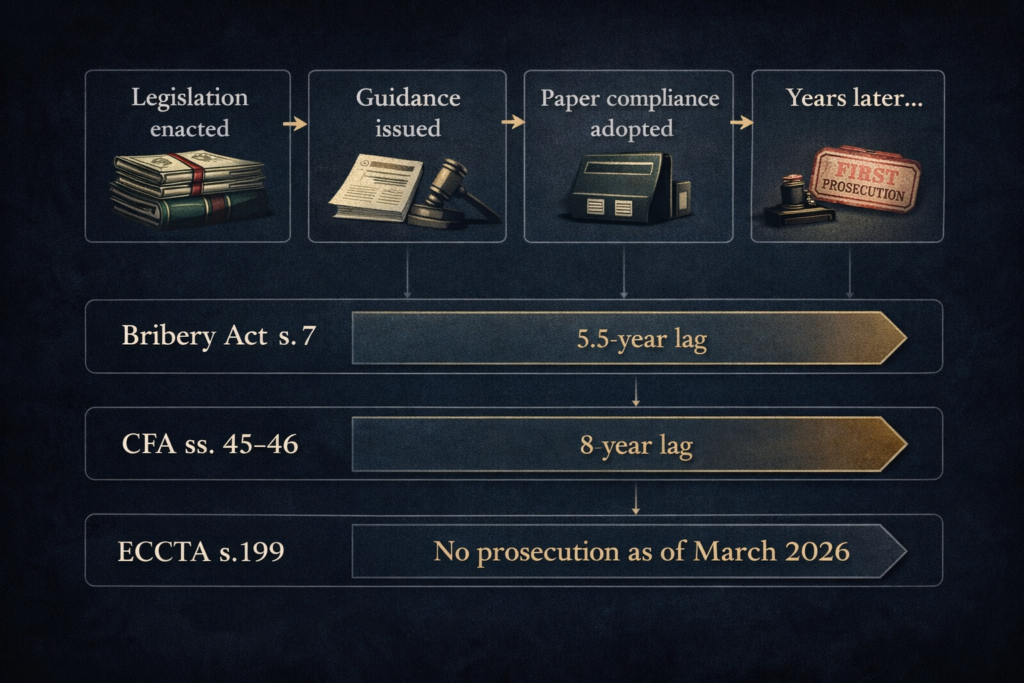
    Learn more:


  • Zero-Score Ethics: Why Judicial Integrity Systems Fail by Design

    Zero-Score Ethics: Why Judicial Integrity Systems Fail by Design

    Abstract

    Judicial integrity systems fail when their enforcement architecture is empty. When Nigeria’s Independent Corrupt Practices Commission assessed 330 federal bodies in 2024, the Supreme Court scored zero percent across every ethics and integrity indicator — management culture, financial management, and administrative systems. The score repeated in 2025. In South Africa, a gross misconduct complaint against a High Court judge required seventy months to reach a finding under a statutory framework designed to resolve such complaints. Neither case represents isolated judicial misconduct. Both expose a structural design vacuum: the simultaneous absence of independent external audit authority, binding accountability timelines, and statutory whistleblower protections — three features the governing international standard, the , neither prescribes nor recommends. This analysis draws on evidence from six jurisdictions and one global index. The central argument: independent external ethics audit bodies with binding reporting timelines should be treated as a minimum institutional design requirement for apex courts, separate from and parallel to judicial conduct committees.

    Judicial Integrity Systems Fail as Architecture, Not Conduct

    Anti-corruption discourse centres on enacting codes and establishing committees. The structural failure that receives insufficient attention sits inside those committees — where absent timelines, absent external audit, and absent whistleblower protection render the ethics architecture inert by design.

    The distinction matters. The standard institutional response to an ethics scandal is to strengthen the code. Add new provisions. Expand the conduct committee’s mandate. Issue guidance. But if the architecture surrounding the code has no mechanism to verify compliance, no deadline to resolve complaints, and no protected channel for reporting misconduct, the code operates as documentation rather than governance.

    The offers a rare instrument for testing this claim. Deployed since 2016 across Nigerian federal agencies, the EICS uses a three-KPI framework — management culture and structure, financial management systems, and administrative systems — to produce composite compliance scores. In the 2024 assessment, the Supreme Court of Nigeria scored 0.00% across all three domains. Fifteen of 330 assessed bodies scored zero. None achieved full compliance.

    That is not a one-cycle anomaly. The 2025 EICS repeated it.

    What a Zero Ethics Score Measures — and What It Misses

    A zero score on the EICS indicates failure on documentation compliance: governance and executive management practices, financial auditing processes, ethics education, and whistleblowing mechanisms. ICPC officers visit agencies physically; submissions are cross-validated against FIRS, Bureau of Public Procurement, and ICPC investigative data; the agency CEO must certify accuracy by signature.

    The limitation is real. The EICS measures documentation compliance, not behavioural outcomes. A zero score may reflect refusal to participate rather than demonstrated substantive failure — and ICPC’s public reporting does not consistently distinguish between non-responsive agencies classified as “Corruption High Risk” by assumption and agencies assessed as substantively non-compliant. The Commission’s own methodology documentation acknowledges that 37.5% of agencies did not respond during the 2020 virtual deployment cycle. That selection bias goes unflagged in the published results.

    The measurement limitation does not neutralize the architectural finding. Whether the Supreme Court scored zero because its integrity infrastructure is substantively absent or because the institution refused to engage with the assessment process, the result exposes the same design failure: no external mechanism compels participation, verification, or consequence.

    The Parker Tribunal and Accountability Delay

    South Africa’s Parker Tribunal offers a timeline specimen for structural delay under a statutory framework. In March 2020, ten Western Cape High Court judges filed formal complaints with the Judicial Service Commission under , alleging gross misconduct — specifically, two mutually contradictory affidavits under oath regarding an alleged assault.

    The procedural timeline: complaint filed March 2020; referral to Judicial Conduct Committee May 2020; prima facie gross misconduct finding June 2020; Tribunal established October 2020; gross misconduct findings delivered January 2026; Parliament’s Justice Committee briefed February 2026. Seventy months from complaint to finding. The underlying allegation — giving contradictory sworn statements — was not factually complex.

    The JSC Act prescribes no binding completion timelines for Tribunal proceedings. The extended duration may partially reflect legitimate procedural safeguards: right to legal representation, multi-stage review, pandemic disruption during 2020–2021. European standards, as Seibert-Fohr notes in comparative analysis of Council of Europe frameworks, require access to judicial review for disciplinary measures — long timelines can represent a design cost of due process rather than evidence of architectural failure.

    But the question is whether due process and accountability timelines are genuinely in tension, or whether the absence of a statutory deadline is a design choice that removes institutional pressure to resolve complaints within a reasonable period.

    Institutional design triangle showing three missing elements of judicial integrity systems: external audit, binding timelines, whistleblower protections

    What Functional Judicial Integrity Design Looks Like: NSW

    The Judicial Commission of New South Wales, established under the Judicial Officers Act 1986, operates with three design features absent from the Parker Tribunal framework and from most apex court integrity systems.

    Statutory binding timelines. Ninety percent of complaints finalized within six months; all within twelve months. Every complaint acknowledged within five working days.

    Structural independence from the judicial hierarchy. The Commission is not controlled by or answerable to the Chief Justice for complaint decisions. Complaints are processed by non-judicial staff, with serious matters escalated to a Conduct Division whose findings can result in a parliamentary removal recommendation.

    Institutional coordination without absorption. Corruption allegations are referred to the Independent Commission Against Corruption rather than handled internally — creating an external accountability channel that self-governance models lack.

    The NSW model is not without problems. As the UNSW Law Journal (2025) notes, external complaints bodies risk becoming forums for litigants making unsubstantiated allegations against judicial officers — diverting investigative resources from substantial misconduct. The Commission covers state-level judiciary only; the High Court of Australia is not subject to it. No published independent audit confirms the twelve-month statutory cap is met in practice for complex cases.

    The design comparison remains instructive. Where the JSC Act creates a framework with no completion deadline and produces a seventy-month resolution cycle, the NSW model creates a framework with a statutory twelve-month cap and delivers measurably faster resolution. The difference is architectural, not cultural.

    The Bangalore Principles Gap in Judicial Integrity Systems

    The (2002) and the UNODC Commentary (2007) remain the governing international framework for judicial integrity. Endorsed by UN ECOSOC Resolution 2006/23 and consulted with judiciaries in over eighty countries, the Principles address six values: independence, impartiality, integrity, propriety, equality, and competence and diligence.

    On accountability architecture, the Principles contain three structural omissions that national frameworks have overwhelmingly replicated rather than corrected.

    The Preamble vests primary responsibility for integrity maintenance with the judiciary itself. It presupposes judges are accountable to “appropriate institutions established to maintain judicial standards, which are themselves independent and impartial” — but leaves the design, powers, and mandates of those institutions entirely to member states. No institutional design floor is prescribed. No minimum staffing, powers, or independence criteria are defined.

    Principle 6 (Competence and Diligence) contains no provision for mandatory complaint resolution timelines or consequences for procedural delay. The Commentary is silent on resolution timelines.

    No Principle or Commentary provision requires external audit of integrity framework performance, financial disclosure verification, or conduct committee operations. No protected disclosure mechanism for judicial staff, court employees, or litigants observing misconduct is established. Principle 6.5 on financial disclosure explicitly defers to national legislation, imposing no floor standard.

    The UNDP’s 2023 guidance on transparent and accountable judiciaries confirms the implementation pattern: Bangalore-aligned reforms remain judiciary-driven, with external experts limited to facilitating judicial self-assessment.

    The US Supreme Court and Self-Governance Without External Oversight

    The US Supreme Court illustrates the terminal condition of the self-governance model. As the Alliance for Justice documented in 2023 and Harvard Law Review analyzed in 2024, SCOTUS adopted a voluntary Code of Conduct in November 2023 that leaves determinations of propriety entirely to individual Justices.

    Three design absences are documented: no independent enforcement body, no mandatory reporting or resolution timeline, and no external audit authority over financial disclosure compliance. The Judicial Conduct and Disability Act 1980 does not apply to SCOTUS Justices. The Code is structurally non-binding — it creates an appearance of accountability infrastructure without the enforcement mechanisms that make infrastructure operational.

    Harvard Law Review’s assessment identifies legislative enforcement as necessary given the documented failure of internal oversight to prevent publicized violations. The Judicial Conference’s stated objective of preserving public trust through internal oversight is directly undermined by recurring lapses. The Courthouse Ethics and Transparency Act represents a moderate legislative response — but even moderate reform faces separation-of-powers resistance that the Bangalore framework’s self-governance premise reinforces.

    Comparison of judicial integrity design across Nigeria, South Africa, and NSW showing enforcement architecture gaps and outcomes

    Regulatory Design Analysis in India and the United Kingdom

    Huchanavar (2023), writing in the Oslo Law Review from a Durham doctoral thesis, applies a three-dimensional regulatory model to judicial conduct frameworks in India and the United Kingdom. The analysis identifies systematic gaps in both systems: failure to address abuses of disciplinary discretion by senior judges, violations of regulatory protocols by first-tier bodies, and unfair application of regulatory processes by investigative authorities. Internal judicial independence — described as a “vanishing point of jurisprudence” — is systematically underemphasized in both jurisdictions.

    The UK finding matters for the broader argument. UK regulatory mechanisms, which include a statutory Judicial Conduct Investigations Office, show some effectiveness in enforcing conduct standards — suggesting that intermediate models between pure self-governance and fully externalized audit can produce functional output. This complicates a binary “self-governance equals inert architecture” thesis and directs attention to specific design features rather than wholesale external takeover.

    The UK model does not resolve the accountability timeline question or the whistleblower protection gap. Huchanavar’s analysis is doctrinal, not empirical — it does not measure complaint resolution rates, actual timelines, or protected disclosure usage.

    Macro-Level Evidence from the WJP Rule of Law Index

    The covering 143 countries, reports deterioration on indicators directly adjacent to judicial integrity enforcement. Indicators measuring whether the judiciary limits executive power declined in 61% of countries. Civil justice free from improper government influence weakened in 67%. Civil justice overall declined in 68%.

    The WJP Index measures perceived outcomes and behaviours rather than design features directly. The correlation between declining scores and specific structural gaps — absent external audit, absent binding timelines, absent whistleblower protection — is inferential, not directly tested. The methodology uses approximately 29 expert survey responses per country, limiting statistical power for cross-country causal analysis.

    The macro-level trend confirms that the structural weaknesses documented in individual jurisdictions — Nigeria, South Africa, the United States, India, the United Kingdom — are not outliers. They reflect a systemic pattern consistent with the Bangalore framework’s self-governance premise producing inadequate enforcement infrastructure across legal traditions.

    The Missing Empirical Foundation

    Seven research gaps constrain the institutional design argument:

    No peer-reviewed longitudinal study measures whether formal ethics code adoption at apex court level produces statistically significant change in complaints filed, sustained, or resolved. The causal link between architecture and behavioural outcomes remains empirically untested.

    No validated cross-national methodology distinguishes “inert” integrity architecture (framework present but non-operational) from absent architecture — the ICPC’s zero-score instrument does not resolve this distinction.

    Binding timeline mechanisms exist in sub-apex systems (NSW), but no study measures whether mandatory timelines reduce substantive misconduct occurrence or merely accelerate administrative processing.

    No empirical study has measured the complaints-suppression effect of absent for judicial staff and court users.

    Positive-design comparator evidence at apex court level is structurally thin: NSW covers state judiciary only; the UK JCIO has not been independently audited for outcome effectiveness.

    The ICPC EICS instrument has not been validated against external behavioural outcomes — its predictive validity for actual anti-corruption results is unestablished.

    No comparative study simultaneously examines the full institutional design triangle — independent external audit, mandatory timelines, and statutory whistleblower protections — as a combined predictor of integrity system performance.

    These gaps do not weaken the architectural argument. They define the research programme required to test it.

    Institutional Design Implications

    The evidence supports five conclusions for institutional designers.

    Judicial integrity codes without independent external verification mechanisms are architecturally incomplete. The Bangalore framework’s self-governance premise has been tested across jurisdictions — Nigeria, the United States, South Africa — and produces documentable enforcement failure at apex court level.

    Binding accountability timelines with enforceable consequences for breach are a resolvable design feature, not an irreconcilable tension with procedural fairness. The NSW model demonstrates that a twelve-month statutory cap and due process coexist within a single framework.

    Whistleblower protection for judicial staff, court employees, and litigants is absent from both the international standard and most national frameworks. This is the least-documented structural omission — and the one most likely to suppress complaint volume at the point of origination.

    The Bangalore Principles require revision. A 2007 Commentary that prescribes no external audit mechanism, no binding timelines, and no whistleblower protections cannot serve as the governing international standard for judicial integrity in 2026. These are not gaps awaiting supplementary guidance — they are architectural choices that national frameworks replicate by default.

    Independent external integrity audit bodies with binding reporting timelines should be treated as a minimum institutional design requirement for apex courts — separate from and parallel to judicial conduct committees. The conduct committee addresses individual complaints. The external audit body assesses whether the integrity system itself is operational. Distinct governance functions require distinct institutional homes.

    Citation reflects reported institutional practice for Tier 2 sources (AFJ 2023, Seibert-Fohr comparative paper). Verify with primary case law databases for specific authority.

    About VeritasJPS

    VeritasJPS provides evidence-based research and advisory at the intersection of judicial integrity, institutional governance, and behavioural science. Our work supports institutional decision-makers — judges, policymakers, anti-corruption bodies, and compliance leaders — with rigorous analysis grounded in empirical evidence and legal scholarship.
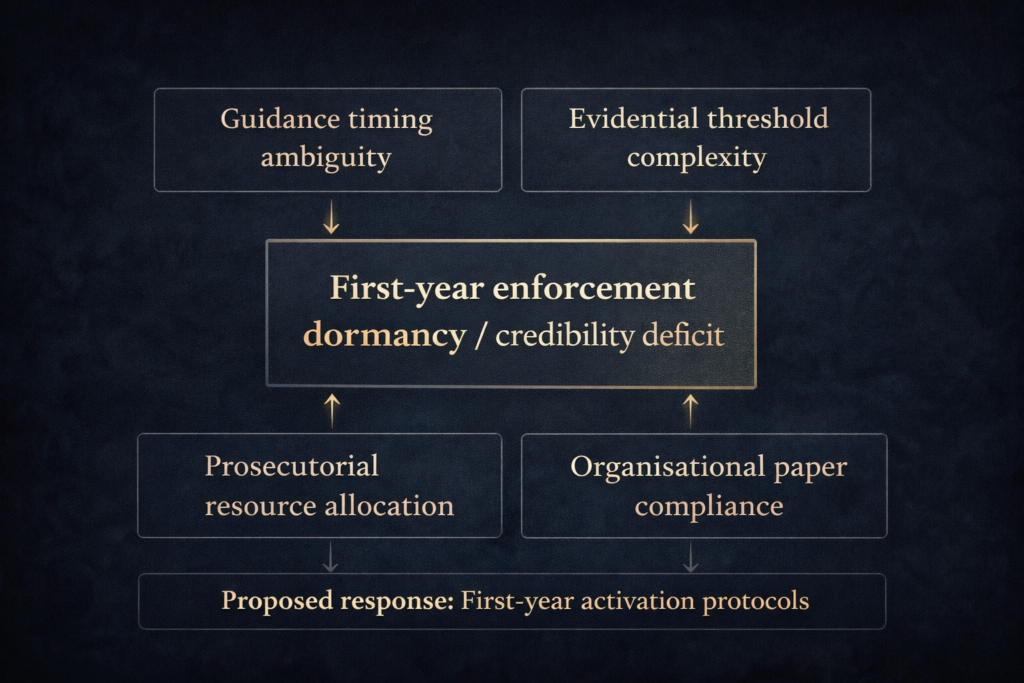
    Learn more: